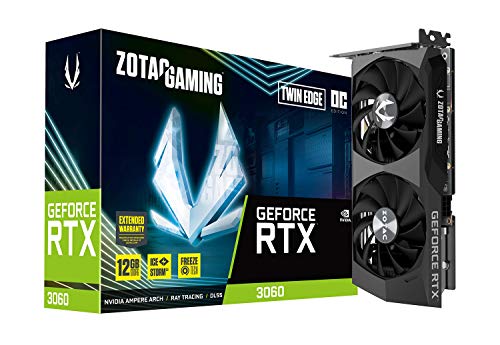
For one user on a desk with an RTX 3060 12GB, LM Studio is the easier choice — install, browse models, chat in five minutes. For two-or-more users sharing a local LLM, or for any agentic workflow with tool calls and document context, Open WebUI (source on GitHub) is the right answer. Both run any model at the same token-per-second rate because they sit on top of the same backends; the choice is about user model and surface area, not raw performance.
Two products, two philosophies
LM Studio is a desktop application — one binary, one user, one machine. It has a model browser, a quantization picker, a chat window with conversation history, and a server mode that exposes an OpenAI-compatible API for other apps on the same machine. The whole point is to compress "decide to try local LLMs" into ten minutes of installation and zero terminal commands.
Open WebUI is a containerized web app — usually Docker, multi-user, persistent, designed to live on a homelab server. It is the closest open replication of the ChatGPT web UI, with accounts, conversation history, file uploads, tool-use plugins, prompt libraries, RAG document ingestion, and a workspace concept that lets users curate their own templates. Behind it sits any OpenAI-compatible backend — Ollama, llama.cpp server, vLLM, or a hosted cloud endpoint.
The choice is structural. One is for "me, at my desk, today." The other is for "my household and my hobby projects, on a server I'll keep running for years."
Key takeaways
- LM Studio — best for one person, one machine, fastest setup, polished desktop UX.
- Open WebUI — best for multi-user, agentic workflows, RAG, tool calls.
- Both run on top of llama.cpp / Ollama; inference speed is identical.
- An RTX 3060 12GB hosts 7B–12B models at usable speeds for either.
- For most readers, the answer is "both" — LM Studio at the desk, Open WebUI on the server.
Hardware floor
Both apps run on Apple Silicon, AMD ROCm, and NVIDIA CUDA, but the open-LLM ecosystem in 2026 still leans heavily NVIDIA. An RTX 3060 12GB or MSI RTX 3060 Ventus 2X 12G is the sweet-spot card: 12 GB VRAM hosts 7B–12B models comfortably at Q4–Q5 quantization, generation rates of 40–80 tok/s depending on model. Pair with a Ryzen 7 5700X, 32 GB system RAM, and a 1 TB SSD for a sub-$700 build.
For a smaller, second-class endpoint — say a kitchen voice-assistant — a Raspberry Pi 4 8GB can host a 1B–3B model at conversational speeds and act as a low-power always-on companion to a desktop-grade Open WebUI install.
LM Studio walkthrough
The flow:
- Download the LM Studio installer for your OS.
- Launch, browse the model catalog (it's a friendly HuggingFace browser with quant filters).
- Click a model, click download. Wait a few minutes.
- Open chat tab, select model, start typing.
- Optionally toggle server mode — exposes an OpenAI-compatible HTTP endpoint on localhost:1234.
That's it. There is no Docker, no docker-compose, no port mapping, no reverse proxy. The model loads, KV cache spins up, and you chat. For someone who just wants to try out Mistral-Small-2 12B on a fresh RTX 3060 build, you'll be talking to it in under fifteen minutes including the model download.
What LM Studio does well:
- Clean desktop chat UI; conversation branching; system prompt editing.
- Built-in model browser with quant comparison.
- Server mode exposes OpenAI-compatible API to other apps.
- Apple Silicon (MLX) and CUDA both well-supported.
- Real-time token/sec metering during generation.
What LM Studio doesn't do:
- Multi-user. One person, one machine.
- RAG with document collections (you can wire it via the API but it's not native).
- Plugin ecosystem for tools.
- Robust headless server deployment.
Open WebUI walkthrough
The flow:
- Install Docker on your server.
docker run -d -p 3000:8080 --gpus all -v ollama:/root/.ollama -v open-webui:/app/backend/data --name open-webui ghcr.io/open-webui/open-webui:ollama- Open http://server:3000, create the first admin account.
- Pull a model: in the UI's model picker, type
mistral-small:12b-q5(Ollama-style identifier), let it download. - Chat.
Once Open WebUI is running, you add users from the admin panel, set per-user quotas if you want, and connect additional backends (an external llama.cpp server, a vLLM endpoint, even a cloud API for fallback). The web UI is the ChatGPT-style mainstream chat experience; users won't notice it's not OpenAI's product unless you tell them.
What Open WebUI does well:
- Multi-user with persistent per-user conversations.
- Document upload + RAG with built-in vector indexing.
- Function-calling and tool-use plugins, MCP integration.
- Prompt library, workspace templates.
- Multiple backends in one front-end; per-conversation backend choice.
- Mobile-friendly responsive UI.
What Open WebUI doesn't do:
- Run without Docker comfortably. Native install works but is friction-heavy.
- Match LM Studio's polish for solo-desktop use.
- Provide a model browser as smooth as LM Studio's — Ollama tag discovery is functional but less curated.
The next question: with the front-end settled, the decision moves to what to load into it. Best Local LLM You Can Run on 12GB of VRAM in 2026 ranks the general-purpose and coding models that fit a 12 GB card, and which quant keeps each one inside the buffer.
Side-by-side
| Aspect | LM Studio | Open WebUI |
|---|---|---|
| Install | Single installer | Docker / docker-compose |
| Surface | Desktop app | Web app |
| Users | One | Many |
| Model browser | Built-in, HuggingFace + quant picker | Ollama tags |
| Inference backend | llama.cpp / MLX | Any OpenAI-compatible |
| RAG | API-only (you build it) | Built-in document collections |
| Function calling / tools | Yes | Yes + plugin ecosystem |
| MCP support | Limited | Mature |
| Mobile use | No | Yes, responsive UI |
| Resource overhead | Negligible | ~200 MB RAM for the container |
| Best for | One person at a desk | Household / homelab / projects |
Performance — identical on the same backend
This is worth emphasizing because it confuses people: neither front-end "is faster" at LLM inference. Both delegate generation to the same backend (llama.cpp, Ollama, or vLLM, per llama.cpp on GitHub). On an RTX 3060 12GB hosting Mistral-Small-2 12B at Q4_K_M you'll see 35–45 tokens per second under either UI.
What does differ is UI latency:
- LM Studio: faster to start a new chat after a model is loaded; near-instant.
- Open WebUI: ~50–150 ms web-request overhead per turn, imperceptible in normal use.
And concurrency:
- LM Studio: one user, serially.
- Open WebUI: queues concurrent requests; with vLLM as backend, true parallel batching.
What actually fits in 12 GB VRAM (real numbers)
The single biggest question a 12 GB GPU buyer asks is "which models can I actually run?" Both front-ends host the same models because both wrap the same backends — what matters is quantization, context length, and how much VRAM is left over for KV cache. Here is the practical fit table on a ZOTAC RTX 3060 12GB at default settings as of mid-2026:
| Model | Quant | VRAM (weights) | KV cache @ 4k ctx | Total | tok/s |
|---|---|---|---|---|---|
| Llama 3.1 8B | Q4_K_M | 4.8 GB | 0.5 GB | 5.3 GB | 65–80 |
| Mistral Small 2 12B | Q4_K_M | 7.3 GB | 1.1 GB | 8.4 GB | 40–55 |
| Mistral Small 2 12B | Q5_K_M | 8.8 GB | 1.1 GB | 9.9 GB | 35–45 |
| Qwen2.5 14B Instruct | Q4_K_M | 8.5 GB | 1.5 GB | 10.0 GB | 32–42 |
| Phi-4 14B | Q4_K_M | 8.7 GB | 1.5 GB | 10.2 GB | 30–40 |
| Mixtral 8x7B | Q3_K_M | 19.4 GB | n/a | OOM | offload only |
Numbers above are with n_gpu_layers=999 (full offload) and a 4k context window. Going to 8k context costs roughly twice the KV cache, which tips the 14B-class models into partial-offload territory and roughly halves token rate. Both LM Studio and Open WebUI expose n_gpu_layers, context_size, and n_threads knobs; the values that matter are identical across the two UIs because the underlying llama.cpp build is the same.
The clean conclusion: on 12 GB, Mistral Small 2 12B at Q4_K_M is the sweet spot for an excellent generalist chat experience, and Llama 3.1 8B is the fast-turn option for agents and tool-use loops where latency matters more than depth.
Setting up MCP tool servers behind Open WebUI
This is the workflow that justifies the Open WebUI Docker tax. Once you have the container running, you can register Model Context Protocol (MCP) servers — small adapters that expose your local filesystem, a vector DB, a shell, or any HTTP API to the chat as callable tools. The pattern:
- Run an MCP server (e.g.,
mcp-server-filesystem,mcp-server-postgres) as a sidecar container. - In Open WebUI's admin panel, add a new "tool server" pointing at the MCP endpoint.
- Toggle the tools on for individual users or per-conversation.
The chat model now sees the tool list, decides when to call, and Open WebUI handles the round-trip. Combined with a Mistral Small 2 12B or Qwen2.5 14B model at Q4, you have a capable local agent loop that does not phone home. LM Studio supports OpenAI-style function calling but has no equivalent admin UI for registering MCP servers — you wire it from code instead. For a household-scale agentic setup, Open WebUI's plugin model is the meaningful differentiator.
When you actually need vLLM instead
A small but real cohort of readers find their way to vLLM after outgrowing both Open WebUI's bundled inference path and LM Studio's single-user limit. The signals: you are serving 10+ concurrent users; you want continuous batching (multiple in-flight prompts sharing one model load) for throughput rather than latency; you are running a 7B-class model on a 24 GB or 48 GB card and want to fan out. In that regime, point Open WebUI at a vLLM endpoint (OpenAI-compatible) instead of Ollama; you keep the polished front-end and get vLLM's batching gains. On a single RTX 3060 12GB serving one household, you do not need vLLM — Ollama or llama.cpp is plenty.
A hybrid setup that works well
Many readers will end up running both. The pattern:
- LM Studio on your workstation, where you experiment with models, tune prompts, and use the OpenAI-compatible local API for any app that needs an endpoint (Cursor, Aider, etc.).
- Open WebUI on a small homelab server (or even the same workstation behind a separate port), running the production chat for household use, voice-assistant backends, and any RAG/document workflows.
The two surfaces talk to overlapping models on the same hardware without conflict if you carefully gate which is "the chat that's serving right now" — usually by having Open WebUI route to one backend instance and LM Studio's local API on a different port.
Common pitfalls
- Picking by ideology. Open WebUI fans dismiss LM Studio as "closed-source" (the core is, the plugins aren't). LM Studio fans dismiss Open WebUI as "too complicated." Both are wrong for the wrong user.
- Underprovisioning VRAM. A 12 GB card runs a 12B Q4 model fine; an 8 GB card does not. Don't assume cheaper cards work.
- Single SSD for OS + models. Models grow fast. A second drive specifically for
~/.ollamaor LM Studio's model dir saves trouble later. - Forgetting reverse proxy + HTTPS for Open WebUI. If you expose it beyond LAN you want TLS. Caddy is two lines.
- Mismatched quantization expectations. Q4_K_M on a 12B is excellent; Q3 starts showing quality issues. Don't chase quants to fit larger models if quality matters.
When NOT to use either
Skip both if you have unique requirements that need bespoke tooling:
- Heavy custom UI work for a domain app — build directly on the OpenAI-compatible backend.
- High-throughput multi-tenant production — go straight to vLLM with a custom front-end.
- Air-gapped enterprise environments with audit requirements neither product currently meets.
For everyone else — and that's most home, hobby, and small-team users — the two products together cover the surface area beautifully.
Bottom line
LM Studio is the easiest way to run a local LLM on a personal machine in 2026. Open WebUI is the closest thing to a self-hosted ChatGPT for a household or homelab. On the same RTX 3060 12GB they deliver identical inference rates; the choice is about how many people, what surfaces, and how much agentic/RAG complexity you want. The right answer for many readers is both, with each one playing to its strengths.
Citations and sources
- Open WebUI — GitHub repository
- LM Studio — official product page
- llama.cpp — GitHub repository (shared backend)
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.