FLUX.2 Klein 4B for Halloween Art: RTX 3060 12GB vs RTX 5060 8GB
FLUX.2 Klein 4B needs ~13GB at full precision. Here is which card handles the FP8 and NVFP4 checkpoints for Halloween art.
By Mike Perry, Founder & Editor-in-Chief · Published 2026-10-17 · Updated 2026-10-17 · 16 min read
Can FLUX.2 Klein 4B run on 8GB? Only quantized. VRAM by precision, RTX 3060 12GB vs RTX 5060 8GB specs, and which card fits a Halloween art workflow.
Quick Answer
Yes. FLUX.2 Klein 4B runs on an 8GB card, but only with a quantized checkpoint. The Hugging Face model card lists the full model at ~13GB of VRAM, and per the JarvisLabs Klein guide, FP8 cuts that by up to 40% and NVFP4 by up to 55%. For most buyers the pick is the RTX 3060 12GB, which runs FP8 with headroom. The RTX 5060 8GB suits buyers who will stay on FP8 or NVFP4.
Introduction
Halloween 2026 falls on Saturday, October 31, two weeks from this writing. That deadline is why a lot of hobbyists are asking about GPUs right now. Costume concept sheets, yard-sign graphics, party-invite art, printable window silhouettes and "haunted portrait" frames are the kind of work a local image model handles well. Running one on your own PC removes per-image credits, queue waits and the content filters of hosted generators, and you can iterate on a costume idea forty times in an evening without a subscription.
FLUX.2 Klein is the model behind much of this talk. Black Forest Labs released the Klein family on January 15, 2026, per JarvisLabs. It comes in 4B and 9B sizes, and the distilled variants generate in four steps. The 9B weights carry a non-commercial license and need roughly 29GB of VRAM, so for a home desktop the 4B model is the realistic option. The model card describes it as "fully open under Apache 2.0." That means a print you sell on Etsy or a flyer for a paid haunted-house event is covered, as long as you keep the license notice with any redistributed weights.
The buying question is simple to state and easy to get wrong. The model card says the 4B model "fits in ~13GB VRAM and is accessible on NVIDIA RTX 3090/4070 and above." Neither of the two cards most people shortlist under the mid-tier price band, the 12GB RTX 3060 and the 8GB RTX 5060, meets that line at full precision. So the real question is which compromise you would rather live with. One option is a slightly-too-small card with older tensor cores (the 3060). The other is a clearly-too-small card with newer tensor cores that accelerate the very formats that shrink the model (the 5060).
This piece is editorial synthesis. Every figure below links to the public source it comes from, and where no public source exists, the article says so instead of estimating.
Key Takeaways
The full-precision checkpoint needs ~13GB of VRAM, per the FLUX.2 Klein 4B model card. That is above both cards in this comparison.
FP8 cuts VRAM by up to 40% and NVFP4 by up to 55%, per JarvisLabs. That works out to roughly 7.8GB and 5.9GB from the 13GB baseline.
NVIDIA's FLUX.2 launch post credits FP8 with a 40% VRAM cut and a 40% performance gain on RTX GPUs, and documents ComfyUI's "weight streaming" offload to system RAM "with some performance loss" (NVIDIA blog).
Reference speed: on an A100 at 1024x1024 with 4 steps, the 4B model takes 1.22s per image at BF16 and 0.90s with all optimizations, per JarvisLabs. No equivalent public figure exists for either consumer card yet.
Step 0: which checkpoint will you actually run?
Settle this before you compare cards. Whichever checkpoint you load decides which card wins.
BF16 (the reference weights). This is the ~13GB figure from the model card.
Right when you want maximum fidelity for print-size output, or you plan to train or apply LoRAs and want no quantization error to compound.
Not worth it when your card has 12GB or less. Neither card here holds it fully, so you will be offloading layers to system RAM on every generation.
FP8. About 40% smaller, per JarvisLabs and NVIDIA's launch post.
Right when you own a 12GB card. FP8 lands around 7.8GB, which leaves a 12GB card roughly 4GB for activations, the VAE decode at higher resolutions, and your desktop.
Not worth it when you are on an 8GB card and also run a browser with hardware acceleration or a second monitor. ~7.8GB in an 8GB frame buffer leaves almost no margin, so expect ComfyUI to stream some weights from system RAM.
Architecture note: the RTX 5060's 5th-generation tensor cores (Blackwell) support FP8 math in hardware. The RTX 3060's 3rd-generation tensor cores (Ampere) do not. Runtimes such as ComfyUI can still store FP8 weights on Ampere and upcast them for compute. You keep the memory savings, but not the full speedup NVIDIA advertises.
NVFP4. About 55% smaller, per JarvisLabs. JarvisLabs notes that its FP8 and NVFP4 figures were benchmarked on RTX 5080/5090 cards.
Right when you own an RTX 50-series card. NVFP4 is a Blackwell-era 4-bit format, and NVIDIA's RTX 5060 page lists "Max AI performance with FP4" under its fifth-generation tensor cores. At ~5.9GB, it is the format that fits an 8GB card with comfortable room.
Not worth it when you are on Ampere. The RTX 3060 has no FP4 tensor path. Whether an NVFP4 file loads at all depends on your runtime, and even where it does, the hardware speedup does not apply.
Rule of thumb: a 12GB Ampere card wants FP8; an 8GB Blackwell card wants NVFP4. The rest of this article follows from that.
How much VRAM does FLUX.2 Klein 4B need at each precision?
The table below applies the published reductions to the published baseline. These are derived approximations, not measurements. The "up to" wording in the source means real savings can be smaller, and the totals do not include the memory your desktop, browser and the VAE decode use.
If you are also sizing a card for local language models, the per-model breakdown in RTX 5060 8GB vs RTX 4070 12GB for Qwen3 14B applies the same VRAM arithmetic to LLM quantizations.
RTX 3060 12GB vs RTX 5060 8GB: spec delta
The board shortlist here is the MSI Gaming GeForce RTX 3060 12GB against the ASUS Dual GeForce RTX 5060 8GB OC. Both are dual-fan cards built on reference-class power targets. The comparison below uses reference specs and launch MSRP only. Street prices move daily, and the product pages carry live pricing.
The trade is plain. The 3060 gives you 50% more memory. The 5060 gives you three generations of tensor-core progress and native support for the formats that make Klein small. For Stable Diffusion-era models that already fit in 8GB, the newer card's compute usually wins. For a 13GB-baseline model like Klein 4B, memory decides how often you leave the fast path. A head-to-head on gaming and LLM workloads is in RTX 5060 vs RTX 3060 12GB for Local LLMs.
How fast is each card at 1024x1024?
The only public, sourced Klein 4B timing comes from datacenter hardware. Per JarvisLabs, an A100 generates a 1024x1024 image in 4 steps in 1.22s at BF16 and 0.90s with all optimizations. The same page notes that the first run includes kernel compilation and warmup, which can take 2-3 minutes. The model card says end-to-end inference can be "as low as under a second" on capable hardware.
Varies by workload; no public Klein 4B figure as of October 2026
—
RTX 5060 8GB
Varies by workload; no public Klein 4B figure as of October 2026
—
The cost of offloading. When the checkpoint does not fit, ComfyUI's "weight streaming" moves part of the model to system memory. NVIDIA's launch post says this works "albeit with some performance loss, as system memory is slower than GPU memory" (NVIDIA blog). In practice, the size of the penalty depends on how much spills over and on your PCIe link. This is where the cards' bus widths matter: the RTX 5060 uses an x8 PCIe 5.0 link, so in an older PCIe 3.0 board, any offload crosses a narrower pipe than on the x16 RTX 3060. If your motherboard predates PCIe 4.0, that is an argument for keeping the whole model on the card, which means NVFP4 on the 5060 or FP8 on the 3060.
Does the 12GB headroom matter for Halloween workflows?
For a single 1024x1024 image at FP8, both cards produce output. The 4GB gap shows up in the work that follows the first image.
Batching costume variants. Generating four variations of "a homemade scarecrow costume, front and back view" in one batch multiplies activation memory. On a 12GB card running FP8, there is room to batch. On an 8GB card, batching usually means dropping to NVFP4 or generating one at a time.
Upscaling to poster size. The model supports outputs up to about 4 megapixels (for example 2048x2048), per JarvisLabs. A printed yard sign or 18x24 poster wants that resolution or an upscale pass on top of it. VAE decoding at 4MP is memory-hungry, and tiled decoding works around it at the cost of time.
Reference-image editing. Klein supports image editing and multi-reference composition, such as putting a photo of your dog into a pumpkin-patch scene. JarvisLabs notes that the hosted API caps Klein at four reference images, while local limits "depend on GPU memory." Each reference image adds latent tensors to the working set, so 12GB lets you stack more references before falling back to offload.
LoRAs. A style LoRA ("vintage 1950s Halloween postcard") adds weights on top of the base model. A handful of small LoRAs rarely matters. Several large ones on an 8GB card running FP8 will push you into weight streaming.
ComfyUI next to a browser. Chrome or Edge with hardware acceleration, a second monitor and a Discord window each claim a slice of VRAM. On a 12GB card that is noise. On an 8GB card running a ~7.8GB checkpoint, it is the difference between fitting and not fitting.
The most-missed step is checking which checkpoint the workflow template actually loads. Community ComfyUI workflows often point at the BF16 file by default. A new owner downloads the template, hits "Queue", watches the generation crawl through offload, and concludes the card is too slow. Before judging any card, open the loader node and confirm it is the FP8 file (3060) or the NVFP4 file (5060).
Common pitfalls
Assuming FP8 speedups on Ampere. NVIDIA's 40% performance figure for FP8 assumes tensor cores that execute FP8. On the RTX 3060, FP8 saves memory, not compute time.
Mixing up Klein 4B and 9B. The 9B model needs ~29GB and carries a non-commercial license, per JarvisLabs. A "Klein workflow" from a forum may be built for 9B. Check before you download 20+GB of weights.
Downloading re-uploads with different terms. The official 4B weights are Apache 2.0. A community quantization may bundle a different text encoder or carry its own terms, so read the repository card.
Judging speed on the first run. Kernel compilation and warmup can take 2-3 minutes on the first generation, per JarvisLabs. Time the second and later images.
Skipping the driver update. FP8 and FP4 support in PyTorch-based tools depends on a recent NVIDIA driver and CUDA runtime, especially on Blackwell cards that launched in 2025.
Which RTX 3060 12GB board should you buy?
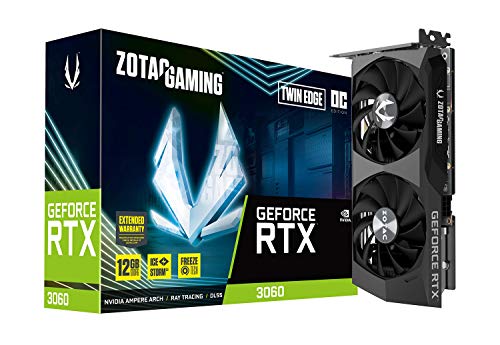
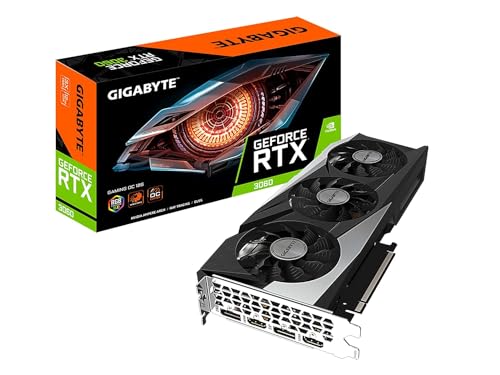
All 12GB RTX 3060 boards share the same GPU and memory configuration, so for Klein the differences come down to physical fit, cooling and noise.
The Gigabyte's third fan spreads the same ~170W load over more blade area, which generally means lower fan speeds during a long batch of costume variants. The ZOTAC is roughly 58mm shorter, which matters in compact cases where a 282mm card will not clear the drive cage. Measure your case before ordering either one.
Step-up option: when 16GB is the right answer
If you want to run the reference BF16 checkpoint without offload and also get Blackwell's FP8 and NVFP4 acceleration, the next tier is the ASUS Dual GeForce RTX 5060 Ti 16GB OC. Per NVIDIA, the RTX 5060 Ti offers 16GB of GDDR7 on a 128-bit bus, 180W total graphics power, 5th-generation tensor cores rated at 759 AI TOPS, and a 600W recommended system power. Its 16GB launch MSRP was $429, per APH Networks.
16GB covers the ~13GB BF16 baseline with about 3GB to spare. It also leaves room for FP8 with heavy batching, multiple reference images, and keeping a small local LLM loaded for prompt-writing at the same time. If you expect Klein to be the first of several local models you run, this is the card that removes the precision decision. Note that the 8GB RTX 5060 Ti shares the name but not the memory, so check the listing says 16GB.
Perf-per-dollar and perf-per-watt math at launch MSRP
Without public Klein 4B timings for either consumer card, the honest value math uses capacity, which is the constraint this article is about. All figures use launch MSRP from the sources above, not current street prices.
Card
VRAM
Launch MSRP
GB per $100 at MSRP
Board power
GB per 100W
Klein 4B precision with no offload
RTX 3060 12GB
12GB
$329
3.65
170W
7.1
FP8 or NVFP4
RTX 5060 8GB
8GB
$299
2.68
145W
5.5
NVFP4 (FP8 borderline)
RTX 5060 Ti 16GB
16GB
$429
3.73
180W
8.9
BF16, FP8 or NVFP4
Two readings stand out. At MSRP, the RTX 3060 and the RTX 5060 Ti 16GB deliver almost identical memory per dollar, and the RTX 5060 is about 27% behind both. Per watt, the 5060 Ti leads, and the 5060's lower 145W board power does not make up for having a third less memory. For compute, NVIDIA quotes 614 AI TOPS for the RTX 5060 and 759 for the 5060 Ti, about 2.05 and 1.77 TOPS per dollar at MSRP. NVIDIA's RTX 3060 page lists no equivalent figure, so a three-way compute comparison is not possible from first-party data.
Worked examples
The costume maker. One person generating front/back reference sheets for a family's costumes, about 30 images a night for two weeks, with occasional reference-photo edits. FP8 on a 12GB RTX 3060 runs this without offload. Pick: RTX 3060 12GB.
The yard-sign printer. Someone producing a handful of 2048x2048 graphics for printing at a local shop. Volume is low, so speed matters less than resolution. High-resolution VAE decoding favors the bigger frame buffer, and tiled decoding on an 8GB card adds time. Pick: RTX 3060 12GB, or the 5060 Ti 16GB if you also want BF16.
The gamer who also makes art. A 1080p gamer who wants DLSS 4 frame generation for games and occasional Klein images for a party invite. NVFP4 on the RTX 5060 fits the image work, and the newer card's gaming features matter more to this buyer. Pick: RTX 5060 8GB.
Verdict matrix
Get the RTX 3060 12GB if…
You want FP8 to fit with room for batching, LoRAs and reference images.
Your workflows come from community templates you would rather not re-quantize.
You print at poster size and want room for high-resolution decoding.
Get the RTX 5060 8GB if…
You will commit to NVFP4 checkpoints and keep the runtime and driver current.
Gaming features (DLSS 4, newer NVENC) matter as much as image generation.
Your case or PSU budget favors a 145W card.
Get the RTX 5060 Ti 16GB if…
You want BF16 without offload, or you plan to run several local models.
You want the precision question settled for the next couple of model generations.
When NOT to buy any of these: if you only need a dozen Halloween images once a year, a hosted generator's free or trial tier costs less than any GPU. Keep your current card and spend the difference on printing.
Recommended pick
The RTX 3060 12GB is the recommended card for FLUX.2 Klein 4B in this price band. Its deciding spec is the 12GB frame buffer: it holds the FP8 checkpoint (~7.8GB, derived from the model card baseline and JarvisLabs reduction) with about 4GB left for batching, references and the desktop. The RTX 5060 8GB is the right call only for buyers committed to NVFP4, where Blackwell's FP4 tensor path turns its smaller memory into a workable trade.
Bottom line
FLUX.2 Klein 4B is the first Apache-2.0 FLUX model that a mid-range desktop can run at four steps. Neither the 8GB nor the 12GB card holds its full-precision weights, so the purchase comes down to precision. A 12GB Ampere card runs FP8 comfortably. An 8GB Blackwell card needs NVFP4. Pick the card whose comfortable format matches how you plan to work. With two weeks until October 31, that leaves enough time to install the card, download the right checkpoint and spend the remaining evenings on costume ideas instead of troubleshooting.
For current pricing on both finalists side by side, see the RTX 3060 12GB vs RTX 5060 8GB live comparison. Prices change frequently and may vary from what you see at checkout. The comparison page pulls live listings rather than the launch MSRPs used in this article.
As an Amazon Associate, SpecPicks earns from qualifying purchases; we also earn on qualifying eBay purchases via the eBay Partner Network. Prices shown were last tracked at crawl time and may vary — check the listing for the current price.
📹 Watch a review
I'm still mad… but buy it anyway - RTX 3060 Review — Linus Tech Tips on YouTube
Frequently asked questions
Can FLUX.2 Klein 4B run on an 8GB graphics card at all?
Yes, but only with a reduced-precision checkpoint. Per the Hugging Face model card, the full-precision model needs about 13GB of VRAM. Per JarvisLabs, Black Forest Labs' FP8 checkpoint cuts that by up to 40% and the NVFP4 checkpoint by up to 55%, which brings it within reach of an 8GB card. Expect some quality and speed tradeoffs versus running BF16 with more memory.
Why does NVFP4 matter more on the RTX 5060 than on the RTX 3060?
NVFP4 is a 4-bit floating-point format that Blackwell GPUs such as the RTX 50-series accelerate in hardware. The Ampere-based RTX 3060 has no native FP4 path, so it gets the memory savings without the matching speedup, or it falls back to FP8 or BF16. That is why the 3060's extra 4GB of VRAM and the 5060's newer tensor cores pull in opposite directions.
Is the license OK for selling Halloween prints or party graphics I generate?
FLUX.2 Klein 4B is released under the Apache 2.0 license, which permits commercial use, modification and redistribution as long as you keep the license notice. That is more permissive than some earlier non-commercial FLUX variants. Check the license on the exact checkpoint you download, because quantized community re-uploads sometimes carry different terms or bundle extra components.
Do I need a bigger power supply to add one of these cards for image generation?
Usually not. NVIDIA's reference board power is about 170W for the RTX 3060 and about 145W for the RTX 5060, so a quality 550-650W unit with the right PCIe power connector covers most single-GPU desktops. Check the specific board's connector type and length against your case before ordering, since some factory-overclocked models are longer than reference designs.
If I buy a GPU in October for Halloween projects, can I still return it after the holidays?
Probably not. Amazon's extended holiday return window generally applies to purchases made from November 1 onward, so an October order normally gets the standard return window, usually 30 days. If you are unsure whether 8GB will be enough for your workflow, test the FP8 or NVFP4 checkpoint early in that window rather than waiting until after Halloween.