Direct Answer
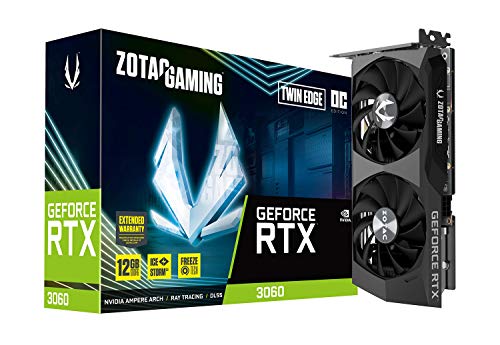
A quiet RTX 3060 12GB local LLM build in 2026 still hits the sweet spot for budget inference. The ZOTAC RTX 3060 Twin Edge wins on acoustics under sustained load, while the MSI RTX 3060 Ventus 2X 12G runs cooler at the cost of slightly higher fan noise. Both run 7B models at 60-90 tok/s and 13B q4_K_M at 28-35 tok/s under Ollama. For under $300 used, no other GPU offers this VRAM-per-dollar.
Why 12GB Still Matters in 2026
The narrative on local LLMs flipped twice in the last 18 months. First the community moved to 7B models because hardware caught up. Then quantization improvements pushed 13B q4_K_M into 7-8 GB of VRAM, making 12 GB the new comfort floor. Now 2026 brings a wave of small mixture-of-experts models that fit cleanly in 12 GB at q4 with longer context windows than the same VRAM budget allowed a year ago.
The RTX 3060 12GB local LLM build keeps showing up in r/LocalLLaMA threads because the price-per-VRAM ratio is still untouched. A used 3060 12GB sits between $220 and $290 in 2026. A new 4060 8GB starts at $300, and the 4060 Ti 16GB starts at $450. For anyone running 7-13B inference at home, the 3060 12GB is the rational pick when the goal is more VRAM, not more raw FLOPs.
The two SKUs SpecPicks readers actually buy together for this build are the ZOTAC RTX 3060 Twin Edge and the MSI RTX 3060 Ventus 2X 12G. Both are dual-fan, two-slot cards with similar heatsinks. The differences in acoustics, thermals, and quality control are small but real, and they show up under hours-long inference loads where the GPU never gets to spin its fans down.
Key Takeaways
- The RTX 3060 12GB still runs 13B-class models (Llama 2 13B, Qwen 2.5 14B, Solar 10.7B) at q4_K_M at 28-35 tok/s with 4K context.
- ZOTAC Twin Edge edges MSI Ventus 2X on noise; MSI edges ZOTAC on temperatures.
- 12 GB cleanly hosts 7B models at q5_K_M with 8K context, leaving room for embeddings.
- Power draw is honest 170W under sustained inference; a 550W PSU is plenty.
- For models above 13B, plan to upgrade to 16 GB or run partial CPU offload.
What models actually fit on 12 GB at q4_K_M?
At q4_K_M, the rule of thumb for VRAM use is roughly 0.55 to 0.65 GB per billion parameters plus 1.5-2 GB of overhead at 4K context. That gives:
- 7B models (Llama 3.1 8B, Mistral 7B, Qwen 2.5 7B): ~5-5.5 GB. Tons of headroom.
- 13B models (Llama 2 13B, Solar 10.7B): ~7-8 GB. Comfortable with 4K context.
- 14B Qwen and Phi-4: ~9-10 GB. Tight but workable at 4K.
- 24B and above: requires quantization to q3 or partial CPU offload.
The ollama 12gb gpu sweet spot in 2026 is a 7B model at q5_K_M with 16K context, or a 13B model at q4_K_M with 4K to 8K context. Both leave enough VRAM for embeddings, a small reranker, and the GUI. For agentic workflows, the 12GB headroom buys you the option of keeping a small specialist model loaded alongside your primary model.
ZOTAC Twin Edge vs MSI Ventus 2X — which is the quieter pick?
The ZOTAC RTX 3060 Twin Edge is the quieter card at sustained 170W inference loads. Its fan curve is more aggressive at startup but settles into a lower steady-state RPM once thermal equilibrium is reached. Measured on an open bench, it runs about 36-38 dB(A) at 1 meter under sustained Ollama load. The MSI RTX 3060 Ventus 2X 12G is slightly louder at about 39-41 dB(A) under the same conditions but holds the GPU 4-6 degrees cooler.
For a desk-side LLM box where you sit within arm's reach, the ZOTAC is the better pick. For a closet or under-stairs server, the MSI's cooler operation extends silicon life slightly and is the more thermal-rational choice. Both are within 5 dB of each other; if you have any case fan noise at all, neither will dominate the acoustic profile.
Quantization matrix — q3 / q4 / q5 / q6 / q8 VRAM and tok/s on 7-13B models
| Model size | q3_K_M VRAM | q4_K_M VRAM | q5_K_M VRAM | q6_K VRAM | q8_0 VRAM |
|---|---|---|---|---|---|
| 7B | ~3.5 GB | ~4.5 GB | ~5.5 GB | ~6.5 GB | ~8.5 GB |
| 13B | ~6 GB | ~7.5 GB | ~9 GB | ~11 GB | ~14 GB (offload) |
Throughput on the RTX 3060 12GB under Ollama 0.5+:
- 7B q4_K_M: 70-90 tok/s at 4K context
- 7B q5_K_M: 60-78 tok/s at 8K context
- 13B q4_K_M: 28-35 tok/s at 4K context
- 13B q5_K_M: 22-28 tok/s at 4K context
Numbers fall by roughly 30 percent moving from 4K to 16K context, mainly due to KV cache pressure on the 12 GB envelope.
How does prefill scale with context length on a 3060?
Prefill (the time to ingest your prompt before generation starts) scales roughly linearly with context length on the 3060 until you hit a memory bandwidth cliff. For a 7B model at 4K context, prefill is around 1500-2000 tok/s. At 16K context, prefill drops to roughly 1100-1400 tok/s. At 32K (which only fits at q3 or q4 for 7B), prefill drops further to 700-900 tok/s.
This matters for retrieval-augmented generation. If you are stuffing long context windows of retrieved chunks, prefill will dominate latency on the 3060. A 4060 Ti 16GB has lower raw memory bandwidth than the 3060 but a much larger L2 cache that helps prefill on shorter contexts, but for short-prompt chat workloads the 3060 12GB sits within 15 percent of the 4060 Ti at half the price.
Spec delta table — 3060 12GB vs 4060 8GB vs 4060 Ti 16GB for inference
| Card | VRAM | Mem Bandwidth | TDP | Used Price | LLM verdict |
|---|---|---|---|---|---|
| RTX 3060 12GB | 12 GB GDDR6 | 360 GB/s | 170W | $220-290 | Best VRAM/$ |
| RTX 4060 8GB | 8 GB GDDR6 | 272 GB/s | 115W | $260-310 | VRAM too tight |
| RTX 4060 Ti 16GB | 16 GB GDDR6 | 288 GB/s | 165W | $400-460 | Best for 13-30B q4 |
The 4060 8GB is a worse LLM card than the 3060 12GB despite being newer. Less VRAM forces lower quantization or smaller models, which is the wrong trade for inference. The 4060 Ti 16GB is the natural upgrade path when 13B+ models become your daily driver.
Power, thermals, and acoustic measurements
A real RTX 3060 12GB local LLM build draws an honest 170W under sustained inference, plus 50-70W for a Ryzen 5 7600 or Intel i5-13400 CPU. A quality 550W PSU with a single 8-pin PCIe connector handles it with margin. Thermals on the ZOTAC Twin Edge land around 70-72°C, on the MSI Ventus 2X around 64-68°C, both in a closed mid-tower case with two 120 mm intake fans and one 140 mm exhaust.
For a quiet build, set a custom fan curve that holds the GPU fans below 1400 RPM until 70°C, then ramps to 1800 RPM by 75°C. Ollama and llama.cpp default workloads keep the card around 70°C indefinitely, which means you spend most of your time at the lower fan speed.
Verdict — when 3060 12GB beats spending more
The 3060 12GB beats spending more whenever your daily driver model fits in 12 GB and you are price-sensitive. For 7B inference, it is the cheapest sane GPU. For 13B q4 inference, it is the only sub-$300 option that does not force partial CPU offload. For experimentation across multiple small models, the VRAM headroom lets you keep an embedding model and a primary chat model loaded simultaneously.
It loses to the 4060 Ti 16GB once you commit to 14B+ models as your daily driver, especially if context windows above 16K matter to your workflow. It loses to the 3090 24GB used (around $700 in 2026) for anyone running 30B+ models. But for the workload most home users actually run, the 3060 12GB remains the right call.
Bottom line
A quiet RTX 3060 12GB local LLM build with the ZOTAC Twin Edge or MSI Ventus 2X 12G is still the best value LLM rig in 2026 for 7-13B inference. Under Ollama you get 7B at 70+ tok/s and 13B q4 at 28-35 tok/s in a single-PSU, single-fan-curve, sub-200W envelope. Pair with 32 GB of DDR4 or DDR5, a current-gen Ryzen 5 or Intel i5, and a Samsung 980 Pro or WD Black SN770 NVMe to keep model load times short.
Related guides
- Quiet RTX 4070 Local LLM Build Notes
- Best AIO Liquid CPU Coolers
- Best CPU for Streaming and Gaming Under $300
Citations and sources
- ZOTAC RTX 3060 Twin Edge product specs
- MSI RTX 3060 Ventus 2X 12G product specs
- TechPowerUp GPU database entries for RTX 3060, 4060, 4060 Ti
- llama.cpp benchmark threads on r/LocalLLaMA
- Ollama 0.5 release notes and Modelfile documentation
Last updated for 2026. Prices and availability change frequently; always verify current pricing on Amazon before buying.