Who still runs production inference on Ampere in 2026
Both of these cards launched within eleven days of each other in autumn 2020 — the RTX 3090 on 24 September 2020 and the RTX A6000 on 5 October 2020 — and both use the same GA102 silicon. Six years on, they are still the two most common ways a small team gets a 24GB or 48GB inference box without touching a datacenter budget.
The buyer profile is narrow and specific. It is a five-to-forty-person company running an internal RAG service, a document-extraction pipeline, or a coding assistant behind a vLLM or llama.cpp server. Traffic is bursty, the data cannot leave the building, and the cost of a token is a line item nobody wants to see on an OpenAI invoice. The workload is not "can I chat with a model" — it is "can I hold p99 time-to-first-token under a second for twenty simultaneous users while a 32B model stays resident."
That distinction is the whole article. The 3090 and the A6000 share a die, a bus width, and a generation. Per the Wikipedia Quadro table, the A6000 carries 10,752 CUDA cores on GA102-875; per the Nvidia GPU list, the 3090 carries 10,496 on GA102-300-A1. They diverge on exactly four axes that matter for serving: memory capacity, memory type, cooler geometry, and error correction.
Key takeaways
- Capacity, not speed, is what you buy. 48GB vs 24GB decides which models load at all. Single-stream token rate favours the 3090 by roughly 9% on 8B models.
- The 3090 has more bandwidth. 936.2 GB/s of GDDR6X vs the A6000's 768 GB/s of GDDR6 — a 22% deficit for the workstation card, and the direct reason it loses small-model benchmarks.
- Concurrency is where 48GB pays. DatabaseMart's vLLM run serves Qwen2.5-14B at FP16 in 28GB of weights on one A6000. That model does not fit a 3090 at all in FP16.
- Two 3090s beat one A6000 on 70B generation by 12% — 16.29 vs 14.58 tok/s — but draw 700W of board power against 300W, and lose on prefill.
- Perf-per-dollar favours the 3090 by roughly 3× at 2020 MSRPs ($1,499 vs $4,650). Perf-per-watt favours the A6000 by 7%.
Step 0: find out which resource you are actually short of
Before comparing tok/s, classify the workload. There are only two failure modes and they want different cards.
VRAM-bound. The model weights plus the KV cache for all concurrent sessions exceed the card. Symptoms: CUDA OOM at load, or a server that works with one user and dies with four. Llama 3.1 70B at Q4_K_M is about 40GB of weights before a single token of context — on a 24GB card the answer is "buy another card or a bigger one," and no tuning changes it.
Bandwidth-bound. The model fits comfortably, but generation feels slow. Autoregressive decoding reads the whole active weight set once per token, so single-stream generation is a memory-bandwidth problem, not a FLOPs problem. Here the 3090's GDDR6X is straightforwardly better, and buying an A6000 makes the box slower.
The diagnostic is one line: if nvidia-smi shows VRAM near the ceiling and utilisation spiky, you are VRAM-bound. If VRAM has headroom and utilisation sits pinned high, you are bandwidth-bound.
Spec delta: RTX A6000 vs RTX 3090
| Spec | RTX A6000 | RTX 3090 | Delta | Why it matters |
|---|---|---|---|---|
| VRAM | 48 GB GDDR6 with ECC | 24 GB GDDR6X | 2× capacity | Decides which models load at all |
| Memory bus | 384-bit | 384-bit | none | Same GA102 memory controller |
| Memory bandwidth | 768 GB/s | 936.2 GB/s | 3090 +22% | Sets single-stream generation speed |
| CUDA cores | 10,752 | 10,496 | A6000 +2% | Barely matters for decode |
| Board power | 300 W | 350 W | A6000 −50 W | Four A6000s fit a 1600 W chassis |
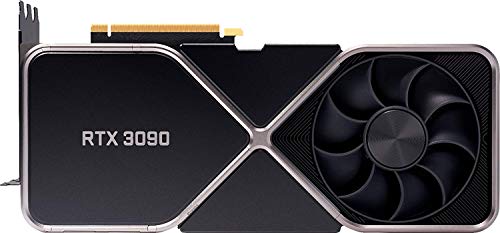
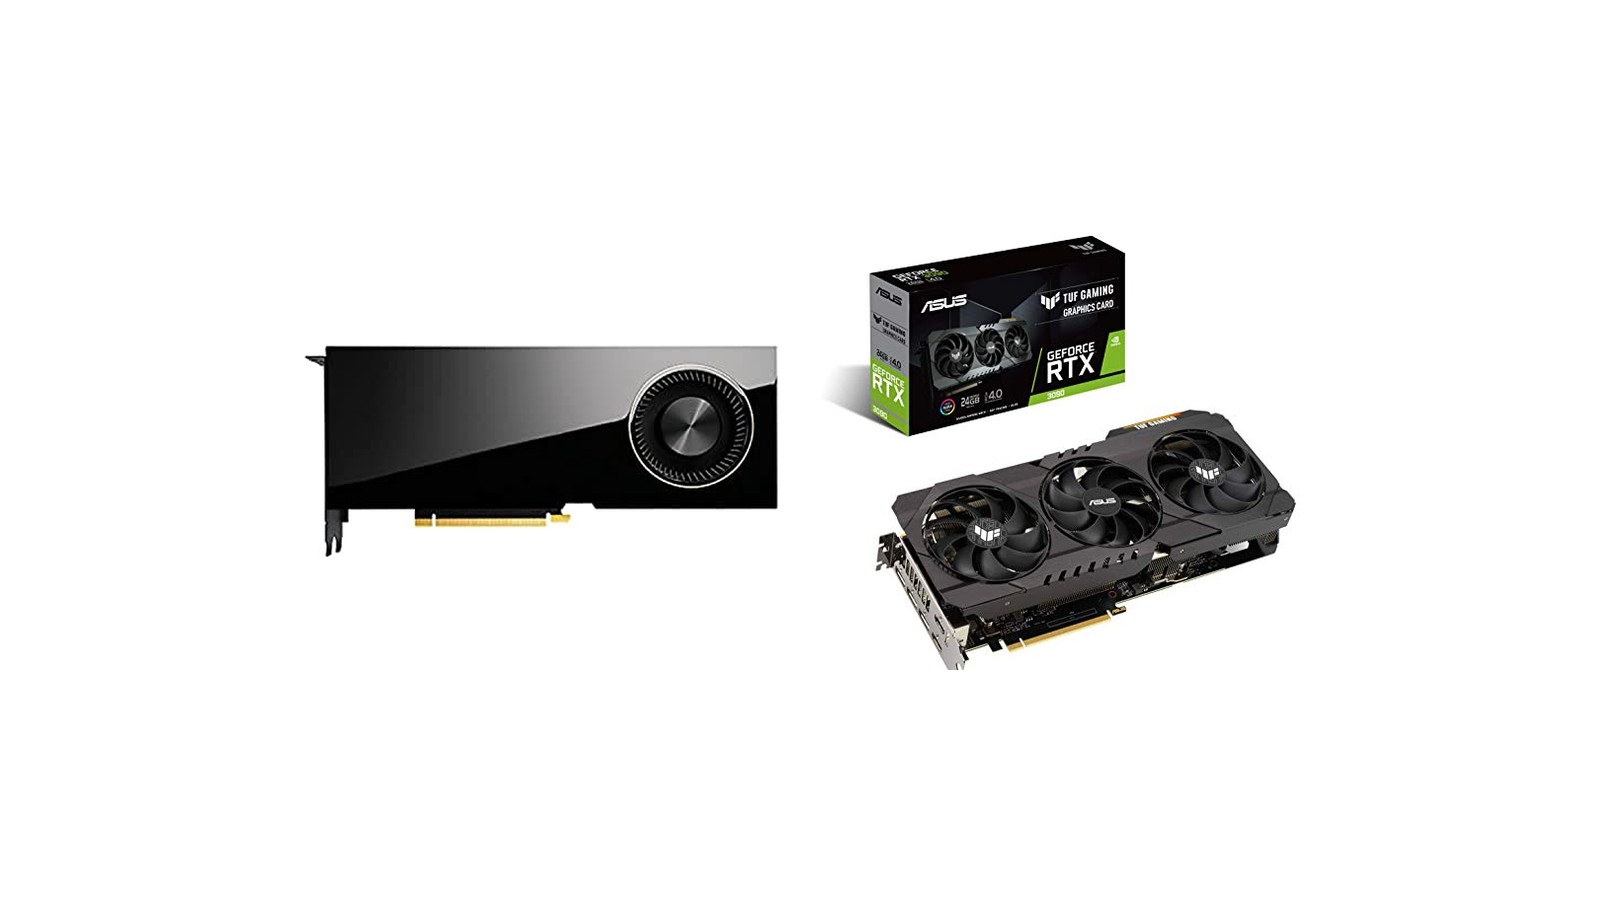
| Cooler | Blower, dual-slot, 10.5" | Open-air triple fan, 3-slot, 12.3" FE | — | Blower is the rack-density decision |
| ECC | Yes | No | A6000 only | Silent bit-flips on a 24/7 service |
| NVLink | 2-way, pools to 96 GB | 2-way | tie | Both can pair |
| Launch MSRP | $4,650 | $1,499 | 3.1× | The core trade |
Sources: the NVIDIA RTX A6000 product page for 48 GB GDDR6 with ECC, 300 W max power, dual-slot 4.4" × 10.5" form factor and 2-way NVLink; the NVIDIA RTX 3090 page for 24 GB GDDR6X, 384-bit, 350 W graphics card power, 750 W required system power, 2× PCIe 8-pin and a 3-slot 313 mm Founders Edition; and the two Wikipedia tables above for bandwidth, core counts and MSRP.
The line to internalise is row three. The A6000 is the slower card per token. Every time a model fits in 24GB, you are paying 3.1× the money for a 22% bandwidth penalty. The case for the A6000 only opens when the model does not fit.
How many tokens per second does each card deliver?
The cleanest like-for-like data is XiongjieDai's GPU-Benchmarks-on-LLM-Inference, which runs the same llama.cpp harness across a large GPU matrix on RunPod. Figures below are generation (tg) and prompt processing (pp) at 1024 tokens, on Llama 3.
| Workload | RTX A6000 (48GB) | RTX 3090 (24GB) | 2× RTX 3090 |
|---|---|---|---|
| 8B Q4_K_M — generation | 102.22 tok/s | 111.74 tok/s | 108.07 tok/s |
| 8B Q4_K_M — prefill | 3,621.81 tok/s | 3,865.39 tok/s | 4,004.14 tok/s |
| 8B F16 — generation | 40.25 tok/s | 46.51 tok/s | 47.15 tok/s |
| 70B Q4_K_M — generation | 14.58 tok/s | OOM | 16.29 tok/s |
| 70B Q4_K_M — prefill | 466.82 tok/s | OOM | 393.89 tok/s |
| 70B F16 — generation | OOM | OOM | OOM |
Two readings fall out immediately. On anything that fits 24GB, the 3090 is 8–15% faster and costs a third as much. On 70B, the 3090 simply does not appear in the table — it reports OOM — while the A6000 posts a usable 14.58 tok/s.
A second, independent dataset agrees. Hardware Corner's RTX A6000 page and its RTX 3090 page run llama-bench across context lengths on Q4_K quants:
| Model (Q4_K) | A6000 @ 4k | 3090 @ 4k | A6000 @ 128k | 3090 @ 128k |
|---|---|---|---|---|
| Qwen3 8B | 90.5 tok/s | 115.3 tok/s | 16.0 tok/s | 28.1 tok/s |
| Qwen3 14B | 53.8 tok/s | 70.0 tok/s | 12.1 tok/s | not measured |
| Qwen3 30B-A3B | 131.2 tok/s | 153.6 tok/s | 14.8 tok/s | not measured |
| Qwen3 32B | 24.6 tok/s | 35.1 tok/s | not measured | not measured |
| Llama 3.3 70B | 12.6 tok/s | not measured | not measured | not measured |
| gpt-oss 20B (MXFP4) | 108.4 tok/s | 147.5 tok/s | 33.4 tok/s | 62.2 tok/s |
Every row where both cards were measured, the 3090 wins on rate. Every row where only the A6000 has a number, the reason is capacity. That is the entire comparison compressed into one table.
Quantization matrix: what fits in 24GB vs 48GB
Weight sizes below are the familiar approximations — roughly 0.55 GB per billion parameters at Q4_K_M, 1.1 GB at Q8_0, 2.0 GB at FP16 — with room reserved for a working KV cache. The tok/s figures are the measured Hardware Corner and XiongjieDai rows cited above where one exists.
| Model / quant | Weights | Fits 24GB? | Fits 48GB? | Measured generation |
|---|---|---|---|---|
| 8B Q4_K_M | ~4.7 GB | yes, easily | yes | 111.74 (3090) / 102.22 (A6000) |
| 8B FP16 | ~16 GB | yes, tight KV | yes | 46.51 (3090) / 40.25 (A6000) |
| 14B FP16 | ~28 GB | no | yes | 695.51 aggregate on vLLM (A6000) |
| 32B Q4_K_M | ~20 GB | yes, 4k context only | yes, to 64k | 35.1 @4k (3090) / 24.6 (A6000) |
| 32B Q8_0 | ~35 GB | no | yes | not measured |
| 70B Q4_K_M | ~40 GB | no | yes | 14.58 (A6000), OOM on one 3090 |
| 70B FP16 | ~140 GB | no | no | OOM on both |
Quality loss is not free at the low end. Q4_K_M is the usual production floor because it is where the perplexity penalty stops being visible in generated text; below that, output degradation is real and is the reason 48GB buys you something a smaller card with an aggressive quant does not.
Prefill vs generation under batched vLLM serving
Single-stream tok/s is the wrong metric for a server, and this is the section where the A6000's capacity stops being a checkbox and starts being throughput.
DatabaseMart's vLLM benchmark on an A6000 ran 50 and 100 concurrent requests against FP16 models:
| Model (FP16) | Weights | Requests | Output tok/s | Total tok/s | Median TTFT | P99 TTFT |
|---|---|---|---|---|---|---|
| Llama-3.1-8B | 15 GB | 50 | 1,218.63 | 1,492.52 | 593 ms | 810 ms |
| Llama-3.1-8B | 15 GB | 100 | 2,193.97 | 2,658.57 | 543 ms | 1,016 ms |
| DeepSeek-R1-Distill-Llama-8B | 15 GB | 50 | 1,385.77 | 1,643.93 | 653 ms | 857 ms |
| Qwen2.5-14B | 28 GB | 50 | 695.51 | 833.44 | 1,095 ms | 1,408 ms |
| DeepSeek-R1-Distill-Qwen-14B | 28 GB | 50 | 566.08 | 727.15 | 475 ms | 638 ms |
Look at the 14B rows. Those models are 28 GB of FP16 weights. A 24GB 3090 cannot load them at all — not slowly, not with a tuning flag, at all. The A6000 serves them at 695 tok/s of output with a median time-to-first-token just over a second.
The batching effect is enormous and it is worth stating plainly: the author of llama.cpp discussion #18030 reports that "for RTX 3090 we have approximately 15 times better throughput in comparison with plain single task mode." His llama-batched-bench table, running Phi-4-mini-instruct Q4_K_M with 128 simultaneous tasks, measures:
| Device | Max parallel tasks | Aggregate tok/s |
|---|---|---|
| NVIDIA GeForce RTX 3090 | 128 | 3,973.05 |
| NVIDIA GeForce RTX 3060 | 128 | 1,050.62 |
| NVIDIA P102-100 | 64 | 493.05 |
| Intel Ultra 9 285K | 64 | 148.38 |
A 3090 is a genuinely capable batch-serving card when the model is small enough to leave room for 128 KV caches. The A6000's argument is that it leaves room for those caches on a model twice the size.
How does context length change the math?
KV cache size is deterministic arithmetic, not a benchmark. Per token, an FP16 cache costs 2 × layers × kv_heads × head_dim × 2 bytes. The Llama 3.1 70B config declares 80 layers, 8 key-value heads and a head dimension of 128, giving 327,680 bytes — 0.3125 MiB — per token. The 8B config declares 32 layers with the same 8 KV heads, giving 0.125 MiB per token.
| Context | 8B KV (FP16) | 70B KV (FP16) | 70B weights + KV @ Q4_K_M |
|---|---|---|---|
| 8K | 1.0 GiB | 2.5 GiB | ~42.5 GB — fits 48GB |
| 32K | 4.0 GiB | 10.0 GiB | ~50 GB — over 48GB, needs Q8 KV |
| 128K | 16.0 GiB | 40.0 GiB | ~80 GB — needs two cards |
Now multiply by concurrency. Twenty simultaneous 8K sessions on a 70B model is 50 GiB of cache alone. This is why "48GB is enough for 70B" is true for one user and false for a service, and it is the single most-missed step when a team sizes a box from a single-stream benchmark.
Hardware Corner's context-scaling rows show the same wall empirically. On Qwen3 32B Q4_K the 3090 posts 35.1 tok/s at 4k and 30.3 at 16k, then stops — there is no 32k entry, because there is no room. The A6000 continues: 24.6 at 4k, 18.3 at 16k, 13.5 at 32k, 8.7 at 64k. The slower card is the one still running.
Is 2× RTX 3090 a better deal than one RTX A6000?
On paper it is obvious: two 24GB cards cost less than one 48GB card and give the same pooled capacity. The measured picture is more mixed.
| Metric | 1× RTX A6000 | 2× RTX 3090 |
|---|---|---|
| Usable VRAM | 48 GB | 48 GB pooled |
| 70B Q4_K_M generation | 14.58 tok/s | 16.29 tok/s (+12%) |
| 70B Q4_K_M prefill | 466.82 tok/s | 393.89 tok/s (−16%) |
| Board power | 300 W | 700 W |
| Slots consumed | 2 | 6 |
| PSU required | one 750 W class | 1,200 W+ |
| MSRP | $4,650 | $2,998 |
The 3090 pair wins generation by 12% and loses prefill by 16%, which is the expected shape: tensor-parallel decode splits the bandwidth-bound work nicely, while prefill pays inter-GPU communication overhead. If your workload is long-prompt RAG — lots of context in, short answers out — the single A6000 is the faster box despite being the slower card.
The practical constraints usually decide before the benchmarks do. Six slots and 700W of GPU is a full-tower build with a 1,200W supply and deliberate airflow. Two open-air triple-fan 3090s stacked in adjacent slots will thermally throttle the top card; you need either a blower model, a riser, or space between them. The A6000 is dual-slot and blower-cooled precisely so four of them fit in one chassis.
Perf-per-dollar and perf-per-watt
At launch MSRPs, the arithmetic is lopsided.
| Metric | RTX A6000 | RTX 3090 |
|---|---|---|
| MSRP | $4,650 | $1,499 |
| 8B Q4_K_M tok/s per $100 | 2.20 | 7.45 |
| 8B Q4_K_M tok/s per watt | 0.341 | 0.319 |
| 70B Q4_K_M tok/s per $100 | 0.31 | n/a (OOM) |
| 70B Q4_K_M tok/s per watt | 0.049 | n/a (OOM) |
Per dollar on small models, the 3090 is 3.4× better and it is not close. Per watt, the A6000 edges ahead by 7% — it does 91% of the 3090's 8B throughput on 86% of the power.
Power cost matters less than people expect at this scale. A card pinned at 300W for 24 hours burns 7.2 kWh; at $0.16/kWh that is about $1.15 a day, or $420 a year. The 3090's extra 50W adds roughly $70 a year. Neither figure changes a purchase decision that has a $3,000 price gap in it. Street prices for both cards move constantly on the used and channel markets — check the live listing before committing, since the numbers above are launch MSRPs, not today's prices.
Which card fits a rack or a 4-GPU chassis?
This is where the A6000 stops being an expensive 3090 and becomes a different product.
The A6000 is a 4.4" × 10.5" dual-slot card with active blower cooling. A blower exhausts out the back of the chassis rather than into it, which is what makes four-way density possible: four cards in adjacent dual-slot positions do not cook each other. The 3090 Founders Edition is 12.3" long, 5.4" tall and 3 slots wide, with open-air fans that dump heat into the case. Two fit in most full towers. Four do not fit in anything short of a mining frame.
The most-missed step is transient power. The 3090's 350W board figure is an average. Ampere GDDR6X cards pull multi-hundred-watt spikes on microsecond timescales, which is why NVIDIA specifies a 750W system supply for a card whose steady draw is half that. Two of them on an undersized or single-rail PSU will trip over-current protection under a batched inference load that never shows up in a wattmeter reading. Size the supply from the spec sheet, not from measured average draw.
Thermals on used 3090s deserve their own warning. The GDDR6X modules sit on the rear of the PCB and run hot; sustained inference is a harsher load than gaming because it never lets the memory idle. Check memory junction temperature under a long llama-bench run before putting a used card into a service.
What if production is overkill?
Plenty of teams size for 70B and then discover the actual workload is an 8B classifier. If the models in play are 8B to 14B, neither of these cards is the right purchase — a 12GB RTX 3060 handles that tier at a fraction of the cost, and it is the sane dev-and-staging tier under either production card.
The MSI Gaming GeForce RTX 3060 12GB posts 55.2 tok/s on Qwen3 8B Q4_K at 4k context and 31.2 tok/s on Qwen3 14B per Hardware Corner — roughly half a 3090's rate on the same models, for well under a third of the money. It also appears in the batched table above at 1,050.62 aggregate tok/s with 128 parallel tasks, which is enough to load-test a service before it touches the production card.
The pattern that works: develop and integration-test on a 3060, then deploy to whichever of the two big cards the model size dictates. Paying production prices for a machine where engineers run unit tests is the most common way these budgets get wasted.
Verdict matrix
Get the RTX A6000 if…
- Your target model needs more than 24GB — 70B at Q4_K_M, 32B at Q8_0, or any 14B at FP16 for vLLM.
- You are serving concurrent users and need KV-cache headroom for twenty-plus sessions.
- The box goes in a rack or a 4-GPU chassis where blower cooling and dual-slot width are non-negotiable.
- ECC matters because a silently corrupted response costs more than the card does.
Get the RTX 3090 if…
- Everything you run fits in 24GB, which covers 8B–14B at Q4_K_M and 32B at Q4_K_M with short context.
- You are bandwidth-bound and want the fastest token rate per dollar — the 3090 wins every fitting workload.
- Budget is the binding constraint and a 3× price gap decides it.
Get two RTX 3090s if…
- You need 48GB of capacity, have the slots, the 1,200W supply and the airflow, and your workload is generation-heavy rather than prefill-heavy.
- You are willing to run tensor parallelism and accept the 16% prefill penalty.
Recommended pick
For a team standing up its first production inference box in 2026, the ASUS TUF Gaming GeForce RTX 3090 24GB is right when the model list tops out at 32B Q4_K_M and the service is one or two concurrent users. It is the faster card on every workload that fits, and the money saved buys a second one later if capacity becomes the problem.
The PNY RTX A6000 48GB is right when a 70B model, an FP16 14B under vLLM, or a rack slot is a hard requirement rather than a preference. It is not worth it if you are buying "headroom" in the abstract — headroom at 3.1× the price and 22% less bandwidth is a bad trade unless something concrete needs it. The PNY NVIDIA RTX A6000 is the same silicon in a different SKU listing if one channel has stock and the other does not.
If the plan is two cards rather than one, the NVIDIA GeForce RTX 3090 Founders Edition is the variant to look for on the used market — its blower-adjacent flow-through design tolerates being stacked better than the triple-fan partner cards do.
Bottom line
The RTX A6000 is not a faster RTX 3090. It is a slower RTX 3090 with twice the memory, half the slot width, and an ECC controller. Every public benchmark where both cards can run the workload shows the 3090 ahead by 8–15%, because 936.2 GB/s beats 768 GB/s on the same die.
Buy the A6000 for the workloads the 3090 reports OOM on, for the concurrency the 3090 has no KV room for, or for the chassis the 3090 physically will not fit. Buy the 3090 for everything else — and if you need 48GB on a budget and have the power and slots, two of them generate 70B tokens 12% faster than one A6000 does.
Related guides
- NVIDIA RTX A6000 48GB Review: The Workstation Card That Still Owns Local 70B Inference
- RTX 3060 12GB vs RTX 3090 for Local LLMs (2026)
- Best 24GB GPU for Local LLM Inference in 2026
- Used RTX 3090 for Local LLM in 2026: 24GB Inference Reality Check + Servicing Guide
Live price comparison
Side-by-side pricing, specs and Amazon listings for the two cards: PNY RTX A6000 48GB vs ASUS TUF RTX 3090 24GB. Benchmark pages with the full cited dataset live at /benchmarks/nvidia-rtx-a6000 and /benchmarks/nvidia-rtx-3090. Prices on both cards move weekly on the channel and used markets — treat every figure in this piece as a launch MSRP and check the live listing before buying.
Citations and sources
- XiongjieDai — GPU-Benchmarks-on-LLM-Inference — Llama 3 8B and 70B generation and prefill across the A6000, 3090 and multi-GPU configurations. Accessed 23 September 2026.
- Hardware Corner — RTX A6000 Local LLM Benchmarks — llama-bench context-scaling tables at 4k through 128k. Accessed 23 September 2026.
- Hardware Corner — RTX 3090 Local LLM Benchmarks — matching context-scaling tables for the 3090. Accessed 23 September 2026.
- NVIDIA — RTX A6000 product page — 48 GB GDDR6 with ECC, 300 W max power, dual-slot 10.5" form factor, 2-way NVLink. Accessed 23 September 2026.
- NVIDIA — GeForce RTX 3090 / 3090 Ti page — 24 GB GDDR6X, 384-bit, 350 W, 750 W required system power, 2× PCIe 8-pin, 3-slot 313 mm. Accessed 23 September 2026.
- DatabaseMart — A6000 vLLM benchmark, 50 and 100 concurrent requests — throughput and TTFT for FP16 8B and 14B models. Accessed 23 September 2026.
- llama.cpp discussion #18030 — batch processing performance — llama-batched-bench aggregate throughput for the 3090, 3060 and Intel Ultra 9 285K. Accessed 23 September 2026.
- Wikipedia — Quadro / NVIDIA RTX professional GPU table — A6000 launch date, GA102-875, 768 GB/s, 10,752 CUDA cores, 300 W. Accessed 23 September 2026.
- Wikipedia — List of Nvidia graphics processing units — RTX 3090 launch date, 936.2 GB/s, 10,496 CUDA cores. Accessed 23 September 2026.
- Hugging Face — Meta-Llama-3.1-70B-Instruct config and 8B config — layer counts, KV head counts and head dimensions used for the KV-cache arithmetic. Accessed 23 September 2026.
- Hardware Corner — RTX 3060 12GB Local LLM Benchmarks — the staging-tier figures. Accessed 23 September 2026.
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.