For most people running local LLMs, the Prime Big Deal Days GPU to buy is a 16GB RTX 5060 Ti. NVIDIA's RTX 5060 family page lists it with 16GB of GDDR7, and it launched at a $429 MSRP. That MSRP is the test for any event price: if the price doesn't beat it, the card isn't on sale.
As an Amazon Associate, SpecPicks earns from qualifying purchases. Prices change often during the event, so check the live price button beside each pick.
Introduction
This guide is for three kinds of buyers. The first is building a first local-LLM box and wants a card that runs Ollama or llama.cpp without fuss. The second already owns a 12GB card, such as an RTX 3060, and keeps hitting the VRAM wall on 14B-and-up models. The third is a gamer who also wants to run coding assistants and chat models on the same GPU.
As of late September 2026, every GPU listing in the SpecPicks catalog for these five picks is priced above its launch MSRP. That changes how to shop the event. A strikethrough "list price" on an Amazon page can be higher than the price the card launched at, so a "30% off" badge doesn't tell you much. The launch MSRP is a fixed number from the manufacturer, so this guide uses it as the benchmark, and each pick below carries it.
For local inference, VRAM decides which models you can run at all. Memory bandwidth mostly decides how fast they generate tokens. A card with more VRAM but less bandwidth will run bigger models, only more slowly. A card with more bandwidth but only 12GB will be very fast on small models and then stop working when a model gets too big.
In short: at MSRP-or-better, the ASUS Dual RTX 5060 Ti 16GB is the best general pick. The RX 9060 XT 16GB is the best value if your tools are llama.cpp or Ollama. The RTX 5070 Ti is the speed pick if its event price comes close to its MSRP. The two 12GB cards are for narrower cases, covered below.
Step 0 — Which VRAM tier do you actually need?
Before you look at prices, work out the largest model you'll run every day. The table below uses public measurements and model file sizes. At 4-bit quantization (Q4_K_M), the weights take roughly 0.6GB per billion parameters, and the KV cache for your context window comes on top of that.
| Model class | VRAM at Q4_K_M | VRAM at Q8_0 | Fits 12GB? | Fits 16GB? | Source |
|---|---|---|---|---|---|
| 8B dense (Llama 3.1 8B) | ~4.9GB in use | ~8.5GB in use | Yes, both quants | Yes, both quants | ComputingForGeeks, Compute Market |
| 14B dense (Qwen2.5-Coder 14B) | 8.4GB file | 14.6GB file | Q4 yes, Q8 no | Yes, both quants (Q8 with ~1GB headroom) | parsapp RX 9060 XT benchmarks |
| 27B dense (Gemma 3 27B) | Loads, tops out near 8K context | Does not fit | No | Barely, at Q4 only | InsiderLLM RTX 5060 Ti review |
| 32B dense (Qwen3 32B) | Only at Q3_K_M, ~4K context | Does not fit | No | Barely, at Q3 | InsiderLLM |
| 35B-A3B MoE (Qwen 3.5 35B-A3B) | Runs at ~100K context | Not reported | No public figure | Yes, at Q4 | InsiderLLM |
Here's how to read it. 12GB covers 8B at any quant and 14B at Q4. 16GB adds 14B at Q8, mixture-of-experts models up to about 35B, and a tight fit for 27B dense. If dense 27B–32B models are your main workload, no card in this guide is comfortable, and the 16GB GPU guide explains when a 24GB card is worth the step up.
The five picks at a glance
| Pick | Best For | Key Spec (VRAM, bus, bandwidth) | Launch MSRP | Verdict |
|---|---|---|---|---|
| ASUS Dual RTX 5060 Ti 16GB | Most local-LLM buyers | 16GB GDDR7, 128-bit, 448 GB/s | $429 | Best Overall |
| ASUS Dual RX 9060 XT 16GB | llama.cpp / Ollama on a budget | 16GB GDDR6, 128-bit, 320 GB/s | $349 | Best Value |
| ZOTAC RTX 3060 Twin Edge OC 12GB | Cheapest CUDA 12GB | 12GB GDDR6, 192-bit, 360 GB/s | $329 | Buy only near MSRP |
| MSI RTX 5070 Ti 16G Ventus 3X OC | Speed on 14B-class models | 16GB GDDR7, 256-bit, 896 GB/s | $749 | Best Performance |
| MSI RTX 5070 12G Ventus 2X OC | Gaming first, LLMs second | 12GB GDDR7, 192-bit, 672 GB/s | $549 | Capped at 12GB |
MSRPs and memory specs come from NVIDIA's RTX 5060 family page, NVIDIA's RTX 5070 family page, NVIDIA's RTX 3060 family page and AMD's RX 9060 XT product page. Partner-board factory overclocks don't change the memory figures.
Tokens per second by card and quant
Generation speed (tokens/sec, higher is better) from public llama.cpp measurements. A cell that says "no public figure" means none of the cited sources measured it. Those cells are not estimates.
| Card | Qwen3 8B, 16K ctx | Qwen3 14B, 16K ctx | 14B Q4_K_M, short ctx | 14B Q5_K_M | 14B Q8_0 | gpt-oss-20B MoE |
|---|---|---|---|---|---|---|
| RTX 3060 12GB | 41.97 | 22.66 | 33.4 (Qwen3 14B) | no public figure | does not fit | no public figure |
| RTX 5060 Ti 16GB | 51.41 | 32.91 | 32.9 (Qwen2.5 14B) | no public figure | no public figure | 82.42 |
| RX 9060 XT 16GB | no public figure | no public figure | 33.4 (Qwen2.5-Coder 14B) | 28.8 | 20.2 | no public figure |
| RTX 5070 12GB | 59.13 | 40.59 | 20.8 (Qwen2.5 14B) | no public figure | does not fit | no public figure |
| RTX 5070 Ti 16GB | 87.54 | 57.98 | 37.0 (Qwen2.5 14B) | no public figure | no public figure | 133.05 |
Sources: the 16K-context columns and gpt-oss-20B come from Hardware Corner's GPU ranking for local LLMs (Qwen3 at Q4_K_XL). The RTX 3060 short-context figure comes from TYO Lab's 12GB VRAM benchmark. The 5060 Ti, 5070 and 5070 Ti short-context figures come from LocalScore (5060 Ti, 5070, 5070 Ti). The RX 9060 XT quant sweep comes from parsapp's RX 9060 XT benchmarks (Vulkan backend). Different sources used different runtimes and settings, so compare within a column, not across columns.
Two patterns stand out. First, the RX 9060 XT and RTX 5060 Ti generate 14B Q4 models at essentially the same speed in these reports (about 33 tok/s). Second, the RTX 5070 Ti's 256-bit bus shows up directly as about 75% more throughput on Qwen3 14B at 16K context than the 5060 Ti.
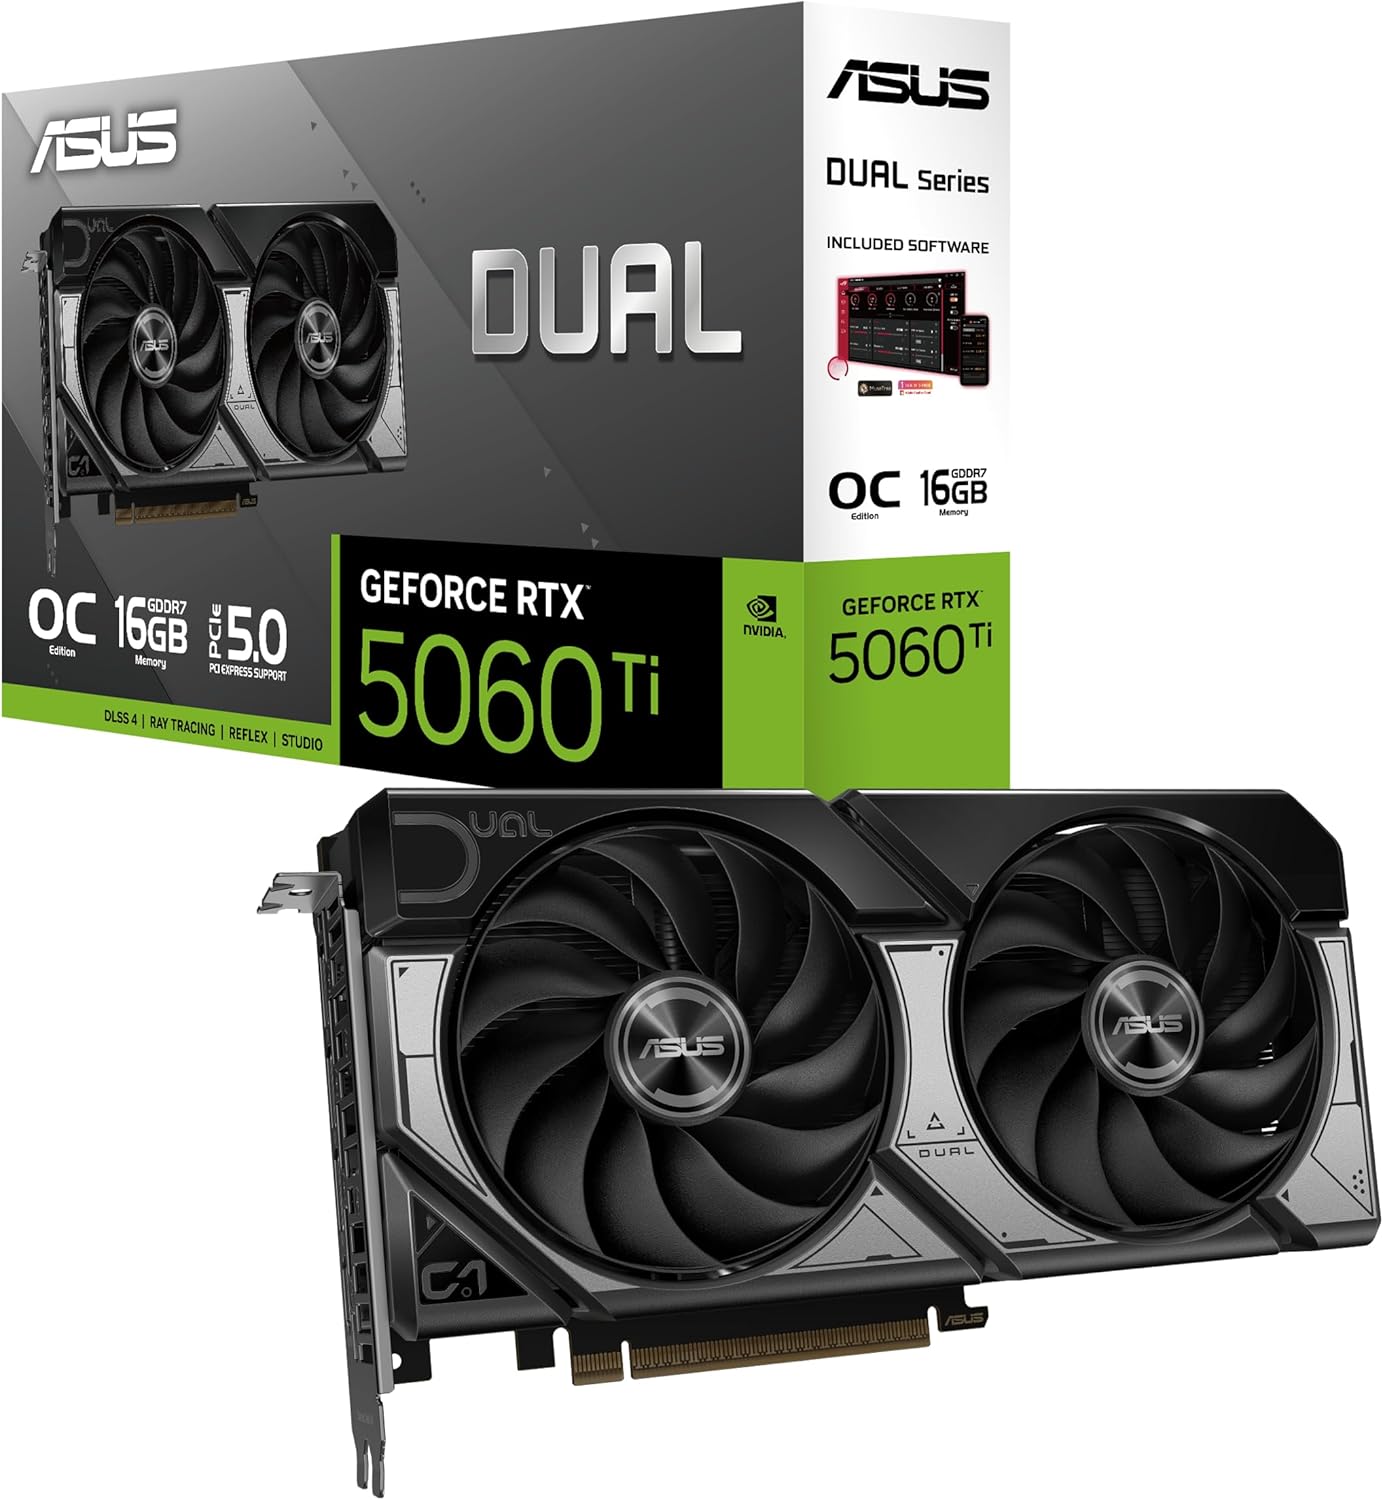
🏆 Best Overall: ASUS Dual GeForce RTX 5060 Ti 16GB
Verdict: The default local-LLM card for 2026. It has 16GB of VRAM, full CUDA support, and a 180W board power that fits almost any case.
The ASUS Dual RTX 5060 Ti 16GB gives you 16GB on a 128-bit GDDR7 bus running at 448 GB/s, per NVIDIA's spec sheet. That's enough to load 14B models at Q8_0 or at Q4 with long context. InsiderLLM's review reports Qwen 3.5 35B-A3B running at about 44 tok/s with roughly 100K context on this chip. MoE models like that are the main reason to buy 16GB rather than 12GB in 2026.
CUDA is the other reason. Ollama, llama.cpp, vLLM, ExLlamaV2 and ComfyUI all treat CUDA as their primary target, so new model architectures usually run here first. The 2.5-slot ASUS Dual cooler is short enough for most mid-tower and many SFF cases.
Where it's the wrong pick: If you only run 8B assistants, the 16GB is mostly unused. Hardware Corner's 16K-context results put the 5060 Ti only about 22% ahead of an RTX 3060 on Qwen3 8B (51.41 vs 41.97 tok/s). Deal rule: it's a deal at or under $429. As of this writing, the catalog listing is well above that.
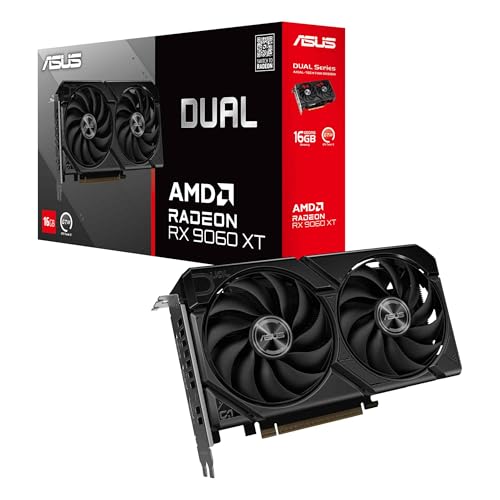
💰 Best Value: ASUS Dual Radeon RX 9060 XT 16GB
Verdict: The same 16GB tier as the 5060 Ti at an $80-lower MSRP ($349 per AMD), with close to equal 14B generation speed in llama.cpp.
The ASUS Dual RX 9060 XT 16GB is an RDNA 4 card with 16GB of GDDR6 on a 128-bit bus, per AMD's product page. Its 320 GB/s of bandwidth is lower than the 5060 Ti's, yet the parsapp benchmark repo measured Qwen2.5-Coder 14B at 33.4 tok/s (Q4_K_M), 28.8 (Q5_K_M) and 20.2 (Q8_0). The Q8_0 file (14.6GB) ran fully on the GPU.
Backend caveats: that same repo found llama.cpp's Vulkan (RADV) backend beat ROCm for token generation on both models tested, by 8.8% on the 14B. Vulkan is also the simpler install on Linux. ROCm 7.x supports this card, but some tools that assume CUDA (vLLM, certain ComfyUI nodes, ExLlama) either lag behind or need extra setup on consumer Radeon. If your workflow is llama.cpp, LM Studio or Ollama, those caveats barely matter.
Deal rule: buy at or under $349. The catalog listing currently sits above that. If the 9060 XT and the 5060 Ti end up within about $30 of each other during the event, CUDA's broader tool support makes the NVIDIA card the better buy.
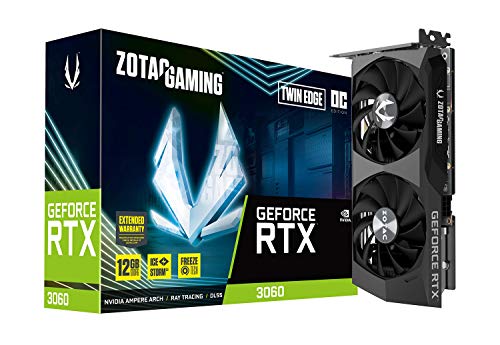
🎯 Best for CUDA on a Budget: ZOTAC RTX 3060 Twin Edge OC 12GB
Verdict: The cheapest way into 12GB with CUDA, but only at a price near its $329 launch MSRP.
The ZOTAC RTX 3060 Twin Edge OC 12GB is a 2021 card with 12GB of GDDR6 on a 192-bit bus (360 GB/s), per NVIDIA's RTX 3060 page. For 8B models it's still competitive: LocalScore measured Llama 3.1 8B Q4_K_M at 52.2 tok/s, and TYO Lab recorded Qwen3 14B at 33.4 tok/s with a short context.
The problem is price. The listing in the SpecPicks catalog is far above its $329 launch MSRP, which puts it at or above the RX 9060 XT 16GB's MSRP. At that price you'd be paying 16GB money for 12GB of five-year-old silicon. Wait unless the event closes most of that gap. If it doesn't, the budget GPU guide for local LLMs covers the used-market options.
⚡ Best Performance: MSI GeForce RTX 5070 Ti 16G Ventus 3X OC
Verdict: The fastest 16GB card in this price range. Its 256-bit bus roughly doubles the 5060 Ti's bandwidth.
The MSI RTX 5070 Ti Ventus 3X OC pairs 16GB of GDDR7 with a 256-bit bus at 896 GB/s, per NVIDIA's RTX 5070 family page. Token generation is limited by memory bandwidth, so that difference shows up directly in speed: Hardware Corner reports 57.98 tok/s on Qwen3 14B at 16K context against 32.91 on the 5060 Ti, and 133.05 vs 82.42 on gpt-oss-20B.
Prefill vs generation: prompt processing depends on compute rather than bandwidth, and the 5070 Ti's gap there is even larger. LocalScore's 5070 Ti page lists 3,657 tok/s prefill on Llama 3.1 8B Q4_K_M, against 2,365 on the 5060 Ti. That matters for RAG and long-document work, where you feed the model thousands of tokens before it writes anything.
The catch: it has the same 16GB ceiling as the 5060 Ti. It runs the same models faster but can't run bigger ones. It's also a 300W card and a long triple-fan board, so check the PSU and case notes below. Deal rule: it's worth buying at or near its $749 MSRP. The catalog listing is currently far above that, so this is the pick most likely to be a "wait".
🧪 Budget-Tier Gaming-First Pick: MSI GeForce RTX 5070 12G Ventus 2X OC
Verdict: A better gaming card than the 5060 Ti. For LLM buyers, it's the pick to avoid.
The MSI RTX 5070 12G Ventus 2X OC has 672 GB/s of GDDR7 bandwidth, per NVIDIA, and it's quick on anything that fits: Hardware Corner reports 59.13 tok/s on Qwen3 8B at 16K context. But 12GB is its hard limit. Q8 14B models don't fit, MoE models in the 30B class don't fit, and long-context 14B work runs out of room quickly.
This is the counter-case in this guide. If you play games at 1440p and run an 8B coding helper on the side, the 5070 is a reasonable $549-MSRP choice. If local models are why you're shopping, the 5060 Ti 16GB costs $120 less at MSRP and runs more models. The prebuilt comparison of the 5060, 5060 Ti and 5070 covers the same trade-off in complete systems.
What makes a Prime Big Deal Days GPU price a real deal?
MSRP anchor vs the strikethrough "list price"
Amazon's strikethrough price usually reflects a recent or listed price, not the launch MSRP. On GPUs that have sat above MSRP for months, a large percentage off can still leave you above launch pricing. Compare the event price against the MSRP column in the table above, not the badge.
VRAM-per-dollar math
Divide the price you'd pay by the card's VRAM in GB. At launch MSRP, the RX 9060 XT works out to about $21.80 per GB, the 5060 Ti to $26.80, the 3060 to $27.40, the 5070 Ti to $46.80 and the 5070 to $45.75. Run the same calculation on event prices. A 12GB card that costs more per GB than a 16GB card is a bad deal for LLM work, however good the badge looks.
12GB vs 16GB for 27B-class models
Dense 27B models at Q4_K_M are right at the edge of 16GB. InsiderLLM reports Gemma 3 27B at Q4_K_M running at about 15 tok/s with only ~8K context on the 5060 Ti. On 12GB they need partial offload to system RAM, which slows generation sharply. If 27B dense is what you want, 16GB is the minimum and 24GB is the comfortable tier.
PSU and slot-width checks
NVIDIA lists board power of 180W for the 5060 Ti, 250W for the 5070 and 300W for the 5070 Ti. AMD's page lists the RX 9060 XT 16GB at 160W. Check the recommended system power on the manufacturer page before you buy. Both ASUS Dual cards are 2.5-slot designs. The MSI Ventus 3X 5070 Ti is a longer triple-fan board, so check its length against your case's GPU clearance.
When to wait for Black Friday
Black Friday falls on November 27, 2026, about seven weeks after the event. If the cards you want don't reach MSRP on October 6–7, you get a second chance with the same product families.
Common pitfalls
- Buying the 8GB 5060 Ti by mistake. The 5060 Ti also comes in an 8GB version with a $379 MSRP, and the listings look almost identical. Check that the title says 16GB.
- Counting context as free. A 14B Q4 model that fits in 12GB at 4K context can overflow at 32K. Hardware Corner's data shows the RTX 3060 has no Qwen3 14B result at 32K context.
- Assuming ROCm is required on AMD. For llama.cpp, the Vulkan backend was faster in parsapp's measurements and needs less setup.
- Ignoring who the seller is. Third-party GPU listings at inflated prices often carry discount badges. Check the "Ships from" and "Sold by" lines, and prefer cards sold by Amazon or the manufacturer's storefront.
Verdict matrix
- Get the RTX 5060 Ti 16GB if you want the lowest-friction 16GB card with CUDA and the event price is at or below $429.
- Get the RX 9060 XT 16GB if you live in llama.cpp, LM Studio or Ollama, and it's clearly cheaper than the 5060 Ti on the day.
- Get the RTX 3060 12GB if it drops close to $329 and you mainly run 8B models with CUDA-only tools.
- Get the RTX 5070 Ti if generation speed and prefill matter to you (agents, RAG, long documents) and the price comes close to $749.
- Skip the event if every card stays well above MSRP, your current 12GB card already handles your models, or you actually need 24GB.
Price freshness
Prices change several times a day during Prime Big Deal Days, and Amazon releases deals in waves. Each pick above links to its live product page. The price box on each page shows the current price and when it was last checked, and the MSRPs in this guide stay fixed. For a full desk-and-GPU setup view, see Prime Big Deal Days 2026 local AI and gaming setup picks, or browse every card in the GPU category.
Citations and sources
- About Amazon — Prime Big Deal Days 2026 is set for October 6–7 (accessed 2026-09-28)
- NVIDIA — GeForce RTX 5060 family (accessed 2026-09-28)
- NVIDIA — GeForce RTX 5070 family (accessed 2026-09-28)
- NVIDIA — GeForce RTX 3060 family (accessed 2026-09-28)
- AMD — Radeon RX 9060 XT (accessed 2026-09-28)
- Hardware Corner — GPU ranking for local LLMs (accessed 2026-09-28)
- parsapp — RX 9060 XT llama.cpp benchmarks (GitHub) (accessed 2026-09-28)
- InsiderLLM — RTX 5060 Ti local AI benchmarks (accessed 2026-09-28)
- TYO Lab — 64GB RAM + 12GB VRAM local LLM benchmark (accessed 2026-09-28)
- LocalScore — RTX 5060 Ti, RTX 5070, RTX 5070 Ti, RTX 3060 (accessed 2026-09-28)
- ComputingForGeeks — RTX 5070 Ti vs 5060 Ti for local AI (accessed 2026-09-28)
- Compute Market — RTX 5070 Ti local AI (accessed 2026-09-28)
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.
Related guides
- Prime Big Deal Days 2026: local AI + gaming setup picks
- Prime Big Deal Days 2026 prebuilts: RTX 5060 vs 5060 Ti vs 5070
- Best 16GB GPU for local LLMs (2026)
- Best budget GPU for local LLMs (2026)
- All graphics cards
— Mike Perry