NVIDIA · GPU · Turing
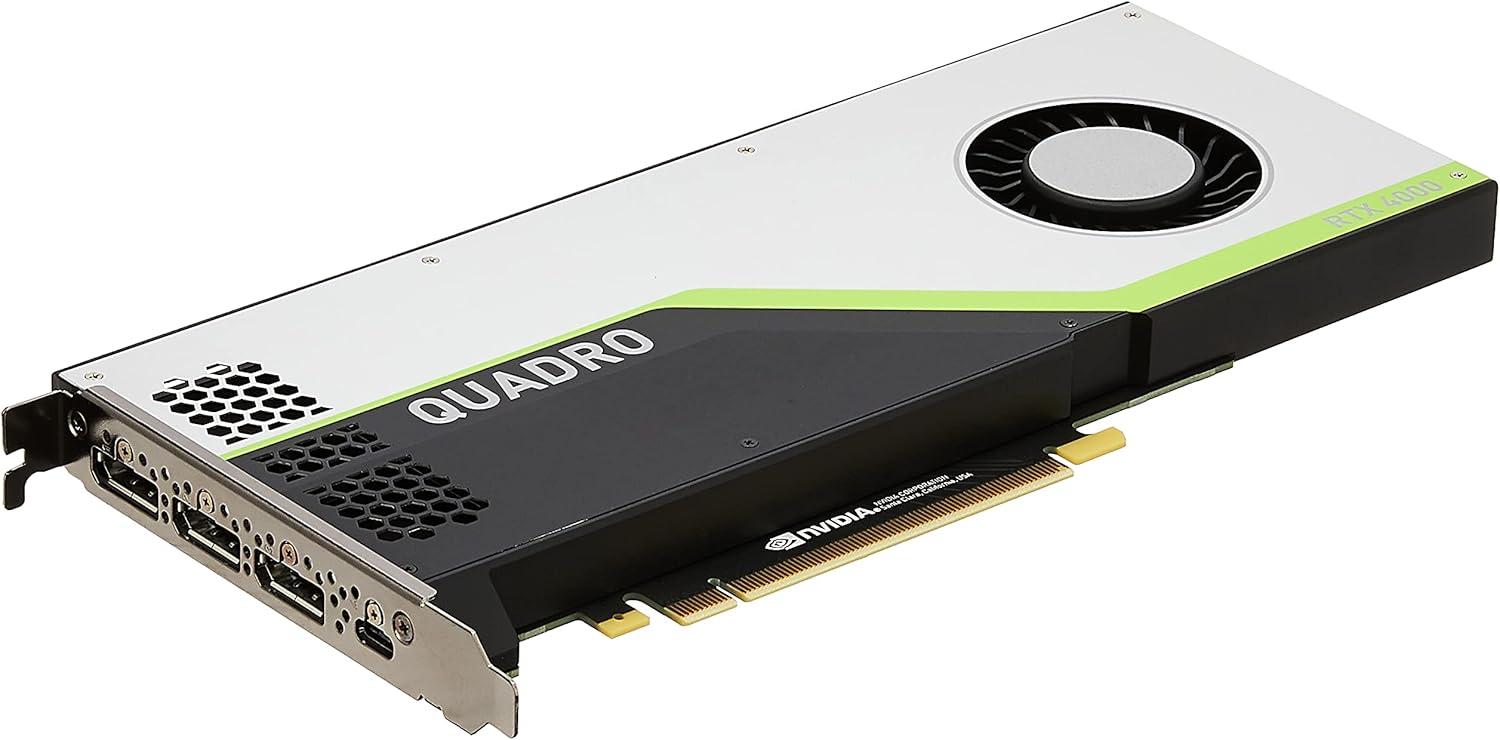
NVIDIA Quadro RTX 4000 — Benchmarks & Specs
8 GB VRAM160W TDP2018
Short answer: the NVIDIA Quadro RTX 4000 generates a median 58.6 tokens/sec on 7-9B dense models at 4-bit (Q4) under llama.cpp, across 5 cited runs from llama.cpp GitHub, GPU-Benchmarks-on-LLM-Inference and LocalScore. Its 8 GB of VRAM holds up to Gemma 2 9B at Q4_K_M with an ~8K context, by the Will-It-Run matrix's sizing (8 of 27 models fit). A used eBay listing for it is $174.99, checked (listings can end at any time).
- Median speed 58.6 tok/s 5 cited runs, 7-9B at Q4, llama.cpp
- Fits in 8 GB up to Gemma 2 9B at Q4_K_M → at ~8K context; 8 of 27 models in the Will-It-Run matrix
Who should buy this instead: the NVIDIA Quadro RTX 4000's 8 GB puts it in the 8 GB tier of the local-LLM GPU picks by VRAM (one card per tier, each with cited tok/s). If they need more than 8 GB, start at the 12 GB pick.
NVIDIA Quadro RTX 4000: verdict by use case
- For everyday local models (7-9B dense): a median 58.6 tok/s at 4-bit (Q4) under llama.cpp, across 5 cited runs (llama.cpp GitHub, GPU-Benchmarks-on-LLM-Inference).
- For the largest model in 8 GB: Gemma 2 9B at Q4_K_M with an ~8K context; 8 of the 27 models in the Will-It-Run matrix fit. By the same sizing, 65-73B models at Q4 do not fit, so 70B-class work needs a card with more VRAM or CPU offload.
Each verdict quotes a figure from a linked source or a row in the tables below. Where no cited figure exists for a use case, there is no verdict line for it.
Bottom line: how fast is the Quadro RTX 4000?
SpecPicks median: 58.6 tokens/sec across 5 cited single-user runs of 7-9B dense models at 4-bit (Q4) under llama.cpp (range 44.4–65.6 tok/s), from llama.cpp GitHub (2 runs), GPU-Benchmarks-on-LLM-Inference, LocalScore (2 runs). One of those runs: llama3:8b at q4_K_M generates 58.6 tokens/sec under llama.cpp, per GPU-Benchmarks-on-LLM-Inference. In Geekbench 5 OpenCL it scores 144,947 points, per Geekbench Browser. Its 8 GB of VRAM is the binding constraint for local inference: the llama3:8b run above (8B parameters) is the largest model on file at 4-bit quantization on this card.
Every figure above is a row in the tables below, and each row links out to the review or public benchmark database the number was taken from; the SpecPicks median is computed here from the runs it names, each a row in the AI table. SpecPicks aggregates published measurements; it does not report first-party benchmark runs.
eBay listing (Used): $174.99, checked . eBay listings are third-party and can end at any time; as an eBay Partner Network member, SpecPicks may earn a commission.
Check what fits in 8 GB: by file size at each listed quantization, 8 of the 27 open-weight model files in the SpecPicks Will-It-Run matrix load entirely into the NVIDIA Quadro RTX 4000's 8 GB while keeping at least 1.5 GB reserved for an ~8K context; the largest that fits, Gemma 2 9B (a 5.8 GB Q4_K_M file per its Hugging Face listing), leaves roughly 2.8 GB of the card's 8.6 GB (8 GiB) free. Check a model in the Will-It-Run matrix →
What fits in the NVIDIA Quadro RTX 4000's 8 GB, and what doesn't
1 of these 7 model files loads whole into 8 GB with room for an ~8K context. A file fits when the card keeps at least 1.5 GB free after the weights; file sizes are the GGUF downloads on Hugging Face in decimal GB, and the card's 8 GB (binary GiB) is 8.6 GB in the same units. Speeds are this card's single-user generation speed from cited community runs at the file listed; a row with no cited run says so rather than estimating one.
| Model | Quant | Fits in 8 GB? | Cited speed on this card |
|---|---|---|---|
| Llama 3.1 8B 4.9 GB file | Q4_K_M | Fits~3.7 GB left for context | 44.4 tok/smedian of 3 cited runs, per LocalScore (Mozilla Builders) |
| Qwen3 14B 9 GB file | Q4_K_M | Doesn't fit0.4 GB over; runs only with CPU offload | — (does not load into VRAM) |
| gpt-oss-20b 21B-A3.6B · 12.1 GB file | MXFP4 | Doesn't fit3.5 GB over; runs only with CPU offload | — (does not load into VRAM) |
| Qwen3 30B-A3B 18.6 GB file | Q4_K_M | Doesn't fit10 GB over; runs only with CPU offload | — (does not load into VRAM) |
| Qwen3 32B 19.8 GB file | Q4_K_M | Doesn't fit11.2 GB over; runs only with CPU offload | — (does not load into VRAM) |
| Gemma 3 27B 28.7 GB file | Q8_0 | Doesn't fit20.1 GB over; runs only with CPU offload | — (does not load into VRAM) |
| Llama 3.3 70B 42.5 GB file | Q4_K_M | Doesn't fit33.9 GB over; runs only with CPU offload | — (does not load into VRAM) |
The Quadro RTX 4000 is a graphics card from the Turing family released in 2018 from NVIDIA. Key on-paper specs include 8 GB of GDDR6 VRAM, 160W TDP. Data on this page draws on 2 linked listings, 11 synthetic benchmark results (top 10 shown), 10 community AI inference reports, compiled from LocalScore, GPU-Benchmarks-on-LLM-Inference, topcpu.net, Geekbench Browser, llama.cpp GitHub, PassMark, 3DMark, cputronic.com, LocalLLaMA; each table row links to its source. Read this page when shopping the Quadro RTX 4000, comparing it against other graphics cards in your build, or sizing it for a specific workload (synthetic benchmark scores or local LLM inference).
AI Inference Performance
Tokens per second under each model + quantization. Higher = faster generation. Bars compare runs across the same model.
| Model | Quantization | Relative | Tokens/sec | VRAM used | Source |
|---|---|---|---|---|---|
| llama3.2:1b | q4_K_M llama.cpp | 189.0 tok/s | — | LocalScore (Mozilla Builders) retrieved 2026-08-21 | |
| llama2:7b | q4_0 llama.cpp | 65.6 tok/s | — | llama.cpp GitHub (CUDA performance scoreboard) 2025-08 | |
| llama2:7b | q4_0 llama.cpp | 61.8 tok/s | — | llama.cpp GitHub Discussions #15013 2025-08-07 | |
| llama3:8b | q4_K_M llama.cpp | 58.6 tok/s | — | GPU-Benchmarks-on-LLM-Inference (GitHub) 2024-05 | |
| llama3.1:8b | q4_K_M llama.cpp | 53.5 tok/s | — | LocalScore (Mozilla Builders) 2025-01 | |
| qwen3:0.6b | — ollama | 47.1 tok/s | — | LocalLLaMA 2026-04-15 | |
| llama3.1:8b | q4_K_M llama.cpp | 44.4 tok/s | — | LocalScore (Mozilla Builders) retrieved 2026-08-21 | |
| llama3.1:8b-instruct | q4_K_M llama.cpp (LocalScore/llamafile) | 40.0 tok/s | — | LocalScore (Mozilla Builders) retrieved 2026-09-24 | |
| qwen2.5:14b | q4_K_M llama.cpp | 30.0 tok/s | — | LocalScore (Mozilla Builders) 2025-01 | |
| qwen2.5:14b | q4_K_M llama.cpp | 24.7 tok/s | — | LocalScore (Mozilla Builders) retrieved 2026-08-21 |
Synthetic Benchmarks
Higher is better. Bars are scaled within each benchmark family (multi-thread, single-thread, etc.) so you can compare like-with-like at a glance.
| Benchmark | Relative | Score | Source |
|---|---|---|---|
| Geekbench 5 OpenCL | 144,947 points | Geekbench Browser (via technical.city) retrieved 2026-06-11 | |
| Geekbench 5 Vulkan | 126,474 points | Geekbench Browser (via technical.city) retrieved 2026-06-11 | |
| PassMark G3D Mark | 23,674 points | PassMark Software retrieved 2026-05-08 | |
| PassMark G3D Mark | 14,854 pts | PassMark retrieved 2026-04-20 | |
| 3DMark Time Spy | 14,340 points | topcpu.net (aggregated 3DMark user submissions) retrieved 2026-06-11 | |
| 3DMark Time Spy Extreme | 6,708 points | topcpu.net (aggregated 3DMark user submissions) retrieved 2026-06-11 | |
| Blender GPU Cycles | 5,293 points | cputronic.com retrieved 2026-06-11 | |
| 3DMark Speed Way | 3,666 points | topcpu.net (aggregated 3DMark user submissions) retrieved 2026-06-11 | |
| 3DMark Steel Nomad DX12 (Graphics score) | 1,847 points | 3DMark (UL Benchmarks) 2026-09-24 | |
| PassMark G2D Mark | 814 pts | PassMark retrieved 2026-04-20 |
Products Featuring the Quadro RTX 4000

Full Specifications
| TDP | 160 W |
|---|---|
| VRAM | 8 GB |
| CUDA cores | 2304 |
| Memory type | GDDR6 |
Quadro RTX 4000 — Frequently Asked Questions
What is the Quadro RTX 4000 best used for?
Quadro RTX 4000 is an 8 GB VRAM Turing-family workstation graphics card. Professional 3D modeling, CAD, rendering and simulation on certified drivers are the headline use cases; the benchmark tables on this page place it within its generation.
When was the Quadro RTX 4000 released?
Quadro RTX 4000 was released in 2018, a Turing-generation part.
Where do the Quadro RTX 4000 benchmark numbers come from?
Each benchmark row on this page names its source (public benchmark databases such as TechPowerUp, PassMark, Geekbench and Cinebench, and community reports such as r/LocalLLaMA threads) and links to it, so every number can be checked against the original.
Can the Quadro RTX 4000 run local LLMs?
Yes — AI inference results for the Quadro RTX 4000 are on file; the AI Inference Performance section on this page lists model, quantization and tokens-per-second for each run. 8 GB VRAM fits models up to about 9B parameters at Q4.
Where can I buy the Quadro RTX 4000?
Amazon listings for the Quadro RTX 4000 are linked at the top of this page and in the Products Featuring the Quadro RTX 4000 section. SpecPicks earns a small affiliate commission on qualifying purchases, at no extra cost to the buyer.
Buying guides that rank the Quadro RTX 4000's class
This page is the raw performance data. The guides below turn it into a ranked pick for a specific build.
Editorial guides covering the Quadro RTX 4000
In-depth SpecPicks reviews, build guides, and head-to-heads referencing this graphics card.
- $1,200 Gaming PC Build 2026: Parts, Cost, 1440p FPS
- Can You Build an $800 Gaming PC in 2026? Parts + Cost
- RX 9060 XT 16GB vs 8GB: Which One to Buy (Benchmarks)
- 1080p Gaming PC Build 2026: Cost, Parts, FPS
- $2,000 Gaming PC Build 2026: Parts, Cost, 1440p FPS
- $1,500 Gaming PC Build 2026: Parts, Cost, 1440p FPS
- 9800X3D + RTX 5070 Ti PC Build 2026: 1440p High-Refresh
- 4K Gaming PC Build 2026: Cost, Parts, FPS
- Browse all SpecPicks reviews →
More guides & deep dives from the SpecPicks archive
Browse all articles & guides →- The Complete Voodoo5 5500 AGP Driver Guide (2026 Edition)
- RTX 4070 Super vs RX 7800 XT — Which to Buy in 2026
- Emulation Hardware in 2026: FPGA, Software, and Cart-Reader Ecosystems
- How to Build a Windows 98 Retro PC in 2026
- Best 1440p Gaming GPUs in 2026
- Best Budget Gaming PC Build 2026 — ~$1,000 Parts List
- Best Retro Handhelds in 2026 — From $35 to $500
More reviews from the SpecPicks archive
Browse all reviews →- Best Mini PC for Local LLM Inference in 2026: Ryzen vs Apple vs Intel
- First-Time Steam Deck Emulation Setup: A Complete Guide
- 9800X3D vs Core Ultra 9 285K — gaming vs productivity
- AI-Driven Win98 Voodoo3 Driver Recovery on a Raspberry Pi 5 Companion
- Inside the Creative Katana V2X Soundbar Teardown — and What It Says About Sound Blaster
- Best Cheap Raspberry Pi Alternatives in 2025
- Why FurMark Has a 'GPU Killer' Reputation
- ChatGPT Full-Duplex Voice: What Real-Time Speech Needs on Your Desk
- Imaging Big-Box CD-ROMs to CompactFlash for a Windows 98 Retro PC
- Gemma 4 31B Creative-Writing Finetunes on RTX 3060 12GB
- SANSUI vs KOORUI 27" 4K: Which Budget 4K Gaming Monitor Wins?
- Four Frontier Models in Eight Days: What a 12GB GPU Can Actually Run
- gpt-oss 20B on 16GB GPUs: RTX 5060 Ti vs RX 9060 XT vs RTX 4070 Ti Super
- A 2007 Samsung UMPC Becomes a Wii U Gamepad
- GPT-5.5 Instant Shipped: What an RTX 3060 12GB Local Stack Covers When OpenAI Retires a Model
- Claude Fable 5 Launches at #1 on the Intelligence Index — What Local Builders Should Take Away
- AMD Ryzen AI Max+ 395 Box (Strix Halo) for Local LLMs: What 128GB Unified Memory Actually Buys You
- Best Quiet PC Cooling Upgrades in 2026
- GLM-5.2 vs Qwen3 on a 12GB GPU: Best Open-Weights LLM for an RTX 3060
- 3dfx Voodoo 5 5500 Install Troubleshooting on Windows 98 SE: Drivers, IRQs, and Glide Wrapper Fixes
- Win98 SE on 1GB+ RAM: The vcache Fix Every Retro Builder Needs
- Qwen3.6 35B on a Single RTX 3060 12GB: What Actually Fits
- Ex-Sega Engineer Builds a 'Super-Realistic' CRT Emulator
- Best Budget AIO CPU Cooler for Gaming PCs (2026)
More buying guides from SpecPicks
Browse all buying guides →- Best CPU Coolers for 2026
- Best Gaming Mice for 2026
- Best PC Cases for Building in 2026
- Best GPUs for Running Local LLMs in 2026
- Best 1440p 240Hz Gaming Monitors in 2026
- Best Gaming Monitors for 2026
- Best Controllers for PC Gaming in 2026
- Best CPUs for Content Creators in 2026
- Best Graphics Cards for Gaming in 2026
- Best DDR5 RAM for Gaming PCs in 2026
- Best CPUs for Gaming in 2026
- Best External SSDs for Content Creators in 2026
- Best GPUs for 4K Gaming in 2026
- Best NVMe SSDs for Gaming in 2026
- Best Tools for Building and Repairing Retro PCs in 2026
- Best NVMe External Enclosures for 2026
- Best Retro Gaming Consoles & Handhelds for 2026
- Best Mechanical Keyboards for Gaming in 2026
- Best 4K Monitors for Content Creators in 2026
- Best GPU for Running 27B-32B Local LLMs in 2026
- Best AM5 Motherboards for 2026
Hardware benchmark data on SpecPicks
All benchmarks →- AMD Ryzen 9 7940HS — benchmarks & specs
- Apple M3 Max 14 Core — benchmarks & specs
- Ryzen 5 5600X — benchmarks & specs
- Radeon RX 6800 XT — benchmarks & specs
- Ryzen 7 9800X3D — benchmarks & specs
- GeForce RTX 5060 — benchmarks & specs
- GRID RTX6000-6Q — benchmarks & specs
- Intel Arc B390 GPU — benchmarks & specs
- Intel Core i9-12900K — benchmarks & specs
- NVIDIA GeForce RTX 3070 Ti — benchmarks & specs
- Apple M3 8 Core — benchmarks & specs
- Ryzen 5 4500 — benchmarks & specs
- NVIDIA GeForce RTX 2080 SUPER — benchmarks & specs
- Intel Core i5-11400F — benchmarks & specs
- AMD Ryzen Threadripper 7960X — benchmarks & specs
- NVIDIA GeForce RTX 5070 — benchmarks & specs
- Ryzen 5 3500U — benchmarks & specs
- AMD Ryzen 7 7735U — benchmarks & specs
- AMD Ryzen 9 5900 — benchmarks & specs
- Radeon RX 7500 — benchmarks & specs
- GeForce 4 Ti 4200 — benchmarks & specs
- GeForce 4 Ti 4600 — benchmarks & specs
- AMD Ryzen 7 7736U — benchmarks & specs
- AMD Ryzen 5 7640HS — benchmarks & specs