Best Parts for a Dual RTX 3060 24GB Local-LLM Build in 2026
Two 12GB cards, one eight-core host, and the slot spacing that decides whether any of it works.
By Mike Perry, Founder & Editor-in-Chief · Published 2026-09-09 · Updated 2026-10-12 · 15 min read
Best parts: two RTX 3060 12GB cards (ZOTAC Twin Edge, MSI Ventus 2X), a Ryzen 7 5800X, an ML240L V2 AIO and a Crucial BX500 1TB SSD, plus any 750 W PSU and an x8/x8-capable AM4 board (not in the cart).
Two 12 GB cards is the cheapest honest route to 24 GB of resident VRAM, and "resident" is the word doing all the work. The difference between a model that lives entirely in graphics memory and one that spills into system RAM is not a percentage — it is the difference between streaming weights at 360 GB/s (TechPowerUp) and streaming a chunk of them at roughly 51 GB/s across a dual-channel DDR4 bus. A build that eliminates offload is a categorically different machine from one that merely reduces it.
What you give up against a single 24 GB card is throughput and simplicity. Layer-splitting across two devices adds a synchronization step on every token, and in a naive split only one card computes at a time. You are buying capacity, not speed. You also take on two GPUs' worth of heat in a chassis where the top card breathes the bottom card's exhaust, a PSU sizing problem, and a motherboard-lane question. None of those is hard. All of them are easy to get wrong.
This guide ranks the parts that actually decide whether the build works, in the order they decide it: the two cards, the offload host, the cooling that keeps the host alive in a two-card chassis, and the storage that holds the model library. Every pick is a currently-listed SKU with a linked product page, and every specification claim carries an inline source.
Median generation throughput at 7–9B models (Llama 3.1 8B, Qwen 3 8B), Q4 quantization, from community-reported runs SpecPicks tracks. Each row pools runs from different sources, runtimes and models in that class, so the rows are not a matched head-to-head; where the article compares cards on the same rig, its own figures are the like-for-like result. Street price is the second-lowest listing priced within the last 24 hours inside a sane band of MSRP, so no single listing sets it; where too few listings pass that check the row shows launch MSRP instead. Rows marked for comparison are not the cards this article is about — they are included so the throughput column has something to be read against.
Which models fit on one RTX 3060, and on a pair (24 GB)?
RTX 3060 carries 12 GB of VRAM. This article compares two of them: the pair column splits the layers across both cards, 24 GB pooled less about 1 GB for the second card's runtime, while the measured column stays single-card runs. The weights column is the range of real Q4_K_M
files on Hugging Face for the models in each size class (about 0.6 GB per billion parameters),
and the runtime plus a usable context window wants about 2 GB on top; every tokens-per-second figure is a
median over community-reported Q4 runs SpecPicks tracks for this card, with the run count and
the source beside it.
Model size
Weights at Q4
One card (12 GB)?
Fits in 2×12 GB (24 GB)?
Measured
Left for context (one card)
Source
3B (Llama 3.2 3B, Qwen 3 4B)Runs on almost anything with a discrete GPU, and usably on modern integrated graphics.
20-27B (Gemma 3 27B, Mistral Small)A 27B Q4_K_M file (about 16.7 GB) is more than a 16 GB card holds, so 16 GB means a Q3 quant or partial CPU offload; a 24B loads with a short context. 20 GB holds the class with a usable context window, 24 GB with a long one.
about 16.7 GB
Nospills to system RAM — system-RAM bandwidth sets the speed
Fitsweights and a usable context window
—
none
—
30-35B (Qwen 3 32B, QwQ 32B)The step change. A 24 GB card holds this entirely in VRAM; below that it is CPU offload.
about 19.9 GB
Nospills to system RAM — system-RAM bandwidth sets the speed
Tightweights are resident; context is the constraint
—
none
—
70B+ (Llama 3.3 70B, Qwen 2.5 72B)One 48 GB card or two 24 GB cards. A 32 GB card runs it only with layers in system RAM.
about 42.5 GB
Nospills to system RAM — system-RAM bandwidth sets the speed
Nospills to system RAM — system-RAM bandwidth sets the speed
The table below lists the five parts this guide ranks, with current Amazon prices. The motherboard, memory, 750 W power supply and case are left to you; the checks under "What to look for" below cover slot spacing, lane splits and PSU headroom.
Total for the 5 parts priced on Amazon in the last 24 hours: $1514.91.
🛒 Add this build to your Amazon cart (5 parts)Adds the 5 Amazon-priced parts above in one step; you review the cart on Amazon before buying. Alternative picks for the same slot are not added.
*Prices sourced from Amazon.com, read 2026-10-13 to 2026-10-14 PT (each row shows its own date). Price and availability subject to change.
Verdict: 12 GB of GDDR6 on a 192-bit bus at 170 W, in the shortest board of the group — the primary card in a two-slot build.
Specs: 12 GB GDDR6 · 192-bit bus · 360 GB/s · 3,584 CUDA cores · 170 W board power · 550 W recommended system PSU (NVIDIA, TechPowerUp)
Pros
12 GB of VRAM at the lowest street price of any current NVIDIA card with that capacity.
Compact dual-fan board — physical length is the constraint that kills most dual-GPU builds in mainstream cases.
170 W reference board power keeps the combined figure for two cards at 340 W, well inside a good 750 W supply.
192-bit bus at 15 Gbps yields 360 GB/s, the figure that sets generation speed for resident weights.
Cons
Ampere-generation efficiency; a modern card does more work per watt.
No NVLink on this class, so multi-GPU is layer-splitting over PCIe rather than a unified memory pool.
Used-market pricing is volatile and mining-era cards are common in the listings.
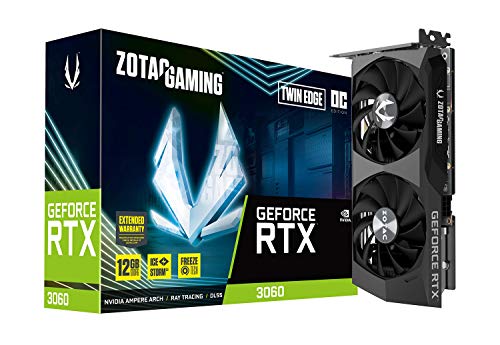
The ZOTAC Gaming GeForce RTX 3060 Twin Edge OC 12GB earns the top slot on physical fit as much as on specification. Both cards in this build have identical memory subsystems — same 12 GB, same 192-bit bus, same 360 GB/s (TechPowerUp) — so the tiebreaker is whether two of them fit in your case with air between them. The Twin Edge is the short one. Put it in the top slot, where it gets clean intake, and give the longer card the bottom position.
Prices on used and channel stock move constantly — check the current listing before buying.
💰 #2 Best Value: MSI GeForce RTX 3060 Ventus 2X 12G — the second card
Verdict: Same silicon, longer cooler, more fin area. The right choice for the second slot precisely because matching VRAM matters more than matching brand.
Specs: 12 GB GDDR6 · 192-bit bus · 360 GB/s · 170 W reference board power (NVIDIA)
Pros
Identical 12 GB capacity, which is the only spec a layer-splitting runtime cares about.
Larger heatsink than the Twin Edge, so it runs quieter at the same heat load in the bottom slot.
Buying a different brand for the second card widens your sourcing options on a thin used market.
Cons
Longer board — check clearance against front fans and drive cages.
Two-slot cooler in the bottom position still starves the card above it of intake.
You do not need matched brands. You need matched capacity. A layer-splitting runtime in the llama.cpp family sizes its per-device allocation from what each card reports, and pairing a 12 GB card with an 8 GB one wastes most of the larger card's advantage — the split has to respect the smaller budget on any layer assigned to it. The MSI GeForce RTX 3060 Ventus 2X 12G is the same 12 GB on the same bus, which is all the requirement there is.
One thing to check on the listing: the RTX 3060 also shipped in an 8 GB variant on a 128-bit bus. It carries the same model number and it is not interchangeable here.
Prices move constantly — verify current stock and price before ordering.
Eight cores is the point where offloaded-layer throughput stops scaling with core count and starts scaling with memory bandwidth.
AM4 platform keeps board and DDR4 costs low, which is the whole premise of a dual-3060 build.
PCIe 4.0 support on the primary slots, useful for model load times even when per-token traffic is small.
Cons
No integrated graphics — one of your two GPUs has to drive the display, or the machine runs headless.
Mainstream AM4 boards split the primary slots to x8/x8 with both populated, and some route the second slot at x4 through the chipset.
The AMD Ryzen 7 5800X is the offload host, and its job is smaller than it looks. In a properly configured dual-3060 build there is no offload — 24 GB of aggregate VRAM holds an 18.6 GB Q4_K_M model resident (Qwen3-30B-A3B-GGUF) with room for the KV cache. The CPU matters for the cases where you exceed that: a larger quantization, a bigger model, or a long-context experiment.
When that happens, memory bandwidth governs, not core count. Populate two matched DIMMs. A single stick roughly halves effective bandwidth and halves your offloaded throughput with it. Our CPU-offload host comparison works through why the eight-core part is sufficient and the sixteen-core part is not meaningfully better.
Price varies by retailer and stock — check before ordering.
⚡ #4 Best Performance: Cooler Master MasterLiquid ML240L RGB V2
Verdict: A 240 mm AIO moves CPU heat straight out of a chassis that has two GPUs warming the air.
Specs: 240 mm radiator · dual-chamber pump · closed-loop AIO
Pros
Radiator exhausts CPU heat directly out of the case instead of dumping it into an already-hot interior.
Frees the space above the socket, which improves airflow to the top graphics card.
Runs at lower fan speed than a tower cooler under the same sustained load, which matters on a machine that is always on.
Cons
A pump is a moving part with a finite life on a 24/7 box.
Radiator mounting competes with front intake in smaller cases.
Overkill if your CPU is idle most of the time, which it will be once offload is eliminated.
Two-card builds have a specific thermal failure mode: the top GPU inhales the bottom GPU's exhaust, and the CPU cooler sits in the same recirculating air. The Cooler Master MasterLiquid ML240L RGB V2 addresses the second half of that by exporting CPU heat rather than moving it around inside the case.
If you would rather have no pump on an always-on machine, the Noctua NH-U12S is the quiet air alternative — it puts the heat back into the case, but a 5800X that is mostly idle is not contributing much of it. Either way, prioritise front intake over rear exhaust; the top card's temperature is set by how much fresh air reaches it. Our 24/7 rig cooling comparison covers the air-versus-AIO trade in detail.
Cooler pricing is stable but stock is not — verify availability.
🧪 #5 Budget Pick: Crucial BX500 1TB — the model library
Verdict: 540 MB/s of SATA read is enough for weights and nowhere near enough for swap. Buy capacity, not speed.
Specs: 1 TB · SATA 6 Gb/s · up to 540 MB/s sequential read (Crucial)
Pros
Loads an 18.6 GB Q4_K_M 30B-class file in roughly 34 seconds — a one-time cost per model swap, not a per-token cost.
A terabyte holds several 30B-class quantizations plus a working set of smaller dense models.
SATA cabling avoids competing with the graphics cards for PCIe lanes, which are already split x8/x8.
Cons
Useless as swap. If the system starts paging, SATA turns a slow situation into an unusable one.
DRAM-less design means sustained large writes taper; irrelevant for a read-mostly model library.
The Crucial BX500 1TB is the right storage tier for this build because model loading is a bandwidth problem you solve once. Using the published 540 MB/s figure (Crucial) against the published 18.6 GB Q4_K_M file size (Qwen3-30B-A3B-GGUF), a cold load is about 34 seconds. An NVMe drive cuts that to a handful of seconds and changes nothing else about the machine.
If your library is small, the Kingston 960GB A400 is the same idea with less room. Our NVMe vs SATA comparison covers the narrow set of cases where the faster interface is worth the money.
Storage prices move with NAND supply — check the current listing.
Two 12 GB cards report 24 GB, and a layer-splitting runtime can genuinely use nearly all of it — but not as one pool. Each layer lives entirely on one device. A model whose largest single tensor exceeded 12 GB would be a problem; in practice, quantized transformer layers are far smaller than that, so the split is clean. What you lose is a few hundred megabytes per device to context buffers and runtime overhead. Budget 23 GB usable from 24 GB nominal, and the 18.6 GB Q4_K_M file plus a 3 GiB fp16 KV cache at 32K context fits with room left over.
PCIe lanes and x8/x8 splits
Most mainstream AM4 boards split the primary x16 slot to x8/x8 when both slots are populated; some route the second slot at x4 through the chipset instead. This matters less than the numbers suggest. PCIe bandwidth is consumed heavily during model load and lightly during inference — layer-splitting passes a hidden-state vector between devices per token, not weight tensors. An x4 second slot adds seconds to load time and very little to per-token latency. Read the board manual for the exact split before buying, and prioritise physical slot spacing over lane count.
Slot spacing and case airflow
This is the constraint that actually kills builds. Two dual-slot cards in adjacent slots leave the top card with no intake gap, and its fans end up recirculating the bottom card's exhaust. Look for a board with three or four slot positions between the primary x16 slots, so the cards sit with a gap. Then feed the gap: front intake fans matter far more than rear exhaust here. Under sustained inference — which loads a card far more steadily than gaming does — the top card's temperature is set almost entirely by how much fresh air reaches its intake.
PSU headroom above combined board power
Two cards at 170 W reference board power is 340 W (NVIDIA), plus an eight-core CPU, plus drives and fans. NVIDIA recommends a 550 W system supply for a single card; two cards plus the rest of the platform sits comfortably inside a good-quality 750 W unit for inference workloads, which draw far more steadily than gaming does. Size for transient spikes rather than the nominal sum, and use native PCIe cables from the supply rather than daisy-chaining a single cable across both connectors on a card.
Layer-split vs tensor-parallel runtimes
Two different multi-GPU strategies, two different fits. Layer-splitting — the default in the llama.cpp family — assigns whole layers to each device and passes activations between them. Communication per token is tiny, mismatched cards are tolerated, and a single user sees the full benefit of the combined capacity. Tensor parallelism, as documented for serving stacks like vLLM, splits individual tensors across devices; it scales better under concurrent load and expects more uniform hardware and more VRAM headroom. For one person chatting or coding against one model, layer-splitting is the pragmatic default.
When a single 24 GB card is the better buy
If your case has poor slot spacing, your PSU is marginal, or you value quiet and low idle draw, a single larger card wins on every axis except price per gigabyte. It also avoids the per-token synchronization step entirely, so throughput on resident weights is higher. The dual-3060 route is strongest in three situations: you already own one card, used prices are unusually good, or your workload is capacity-bound rather than latency-sensitive.
Common pitfalls
Mismatched VRAM. Pairing 12 GB with 8 GB gives you far less than 20 GB of practical capacity, because the runtime budgets from the smaller device on shared layers.
Adjacent slots with no gap. The top card thermally throttles and the whole build gets loud. Slot spacing is a purchase decision, not a tuning decision.
Daisy-chained PCIe power. Two cards at 170 W each want their own cables. Splitters are a common source of instability under sustained load.
Expecting double throughput. Two cards give you capacity, not speed. In a naive layer split, only one device computes at a time.
Forgetting display output. The 5800X has no integrated graphics (AMD), so plan for headless operation or accept that one card also drives a monitor.
Bottom line
Buy two 12 GB RTX 3060s only if the thing stopping you today is capacity. Twenty-four gigabytes of aggregate VRAM turns an 18.6 GB Q4_K_M 30B-class model from an offloading experiment into a resident, responsive workload, and no amount of tuning achieves that on a single 12 GB card. Put the short card on top, give the pair a slot of air, feed it 750 W from native cables, and hang a terabyte of SATA off it for the model library.
Buy a single larger card instead if you are latency-sensitive, space-constrained, or starting from zero with a budget that reaches 24 GB in one purchase. The dual build is a value play, and its value is highest when the first card is already sitting in the machine.
As an Amazon Associate, SpecPicks earns from qualifying purchases; we also earn on qualifying eBay purchases via the eBay Partner Network. Prices shown were last tracked at crawl time and may vary — check the listing for the current price.
📹 Watch a review
Friendly Fire: AMD Ryzen 7 5800X CPU Review & Benchmarks vs. 5600X & 5900X — Gamers Nexus on YouTube
Frequently asked questions
Do both graphics cards have to be the same model?
They have to match on VRAM capacity, because a layer-splitting runtime sizes its per-device budget from the smaller card. Brand, cooler design and factory clocks can differ without breaking anything — the slower card simply sets the pace on the layers assigned to it. Mixing a 12GB card with an 8GB one wastes most of the larger card's advantage, which is the mistake to avoid.
Does two 12GB cards equal one 24GB card?
For capacity, close enough to matter: a quant level that needed 24GB of resident weights now fits without offloading to system RAM. For speed, no. Splitting layers across two devices adds a synchronization step over PCIe on every token, so throughput lands below a single card holding the same model. You are buying capacity at a small latency cost, not buying performance.
What power supply does this build need?
Size it from the combined rated board power of both cards plus the CPU, then add meaningful headroom for transient spikes rather than sizing to the nominal sum. Two mid-range cards plus an eight-core CPU is comfortably inside a good-quality 750W unit for inference workloads, which draw far more steadily than gaming does. Use native PCIe cables from the supply, not daisy-chained splitters.
Will a consumer motherboard give me enough PCIe lanes?
Most mainstream desktop boards split the primary slots to x8/x8 when both are populated, and some route the second slot through the chipset at x4. For inference this matters less than it sounds — PCIe bandwidth is consumed during model load and per-token synchronization, not continuously. Check the board manual for the exact split and for physical clearance between slots before buying.
Which runtime handles two GPUs best?
The llama.cpp family splits layers across devices with a simple per-GPU allocation and handles mismatched cards gracefully, which suits a home build. Batched-serving stacks offer tensor-parallel modes that scale better under concurrent load but expect more uniform hardware and more VRAM headroom. For a single user chatting or coding against one model, layer-splitting is the pragmatic default.
When should I buy one bigger card instead?
If your case has poor spacing, your PSU is marginal, or you value quiet and low idle draw, a single larger card wins on every axis except price per gigabyte. The dual-3060 route is strongest when you already own one card, when used prices are unusually good, or when your workload is capacity-bound rather than latency-sensitive.