

NVIDIA · GPU · Ada Lovelace
NVIDIA GeForce RTX 4070 — Benchmarks & Specs
12 GB VRAM$599 MSRP
Short answer: the NVIDIA GeForce RTX 4070 generates a median 52.1 tokens/sec on 7-9B dense models at 4-bit (Q4) under llama.cpp, across 7 cited runs from knightli.com llama.cpp GPU Benchmark Scoreboard, Local LLM Benchmarks, LocalScore.ai and Hardware Corner. Its 12 GB of VRAM holds up to Phi-4 14B at Q4_K_M with an ~8K context, by the Will-It-Run matrix's sizing (13 of 23 models fit). At the $849.00 Amazon price checked 17 h ago (prices change), that is 61.4 tok/s per $1,000, the SpecPicks Value Index. That ranks #24 of 29 GPUs on tok/s per $1,000 in the SpecPicks value table (table built 2026-10-21 13:12 UTC).
- Median speed 52.1 tok/s 7 cited runs, 7-9B at Q4, llama.cpp
- Fits in 12 GB up to Phi-4 14B at Q4_K_M → at ~8K context; 13 of 23 models in the Will-It-Run matrix
- Lowest linked price $849.00 Amazon, checked ; prices change
- Value Index 61.4 tok/s per $1,000 median speed ÷ the price above
Bottom line: how fast is the GeForce RTX 4070?
SpecPicks median: 52.1 tokens/sec across 7 cited single-user runs of 7-9B dense models at 4-bit (Q4) under llama.cpp (range 38.1–92.3 tok/s), from knightli.com llama.cpp GPU Benchmark Scoreboard, Local LLM Benchmarks, LocalScore.ai, Hardware Corner (4 runs). At the $849.00 Amazon price of the cheapest linked listing (checked ; prices change), that is a SpecPicks Value Index of 61.4 tok/s per $1,000. One of those runs: llama3.1:8b at q4_K_M generates 76.3 tokens/sec under llama.cpp, per LocalScore.ai. At 1440p Ultra, the GeForce RTX 4070 averages 91 fps in Cyberpunk 2077, per Overclocking.com. In 3DMark Fire Strike it scores 37,790 points, per Overclocking.com. Its 12 GB of VRAM is the binding constraint for local inference: the largest model on file at 4-bit quantization on this card is qwen2.5:14b (14B parameters, q4_K_M), generating 37.9 tokens/sec under llama.cpp, per LocalScore.ai.
Every figure above is a row in the tables below, and each row links out to the review or public benchmark database the number was taken from; the SpecPicks median is computed here from the runs it names, each a row in the AI table, and the per-$1,000 figure divides it by the dated listing price. SpecPicks aggregates published measurements; it does not report first-party benchmark runs.
Amazon listing: $849.00
This Amazon listing is above the GeForce RTX 4070's $599 launch MSRP. Compare new and used listings on eBay before buying.
*Price sourced from Amazon.com. Last updated 2026-10-20. Price and availability subject to change.
Read the full comparison → Ryzen AI Max+ 395 vs RTX 4070: Gaming vs AI in 2026
Check what fits in 12 GB: by Q4-class file size, 13 of the 23 open-weight models in the SpecPicks Will-It-Run matrix load entirely into the NVIDIA GeForce RTX 4070's 12 GB with 1.5 GB left for an ~8K context, up to Phi-4 14B (a 9.1 GB Q4_K_M file per its Hugging Face listing). Check a model in the Will-It-Run matrix →
The GeForce RTX 4070 is a graphics card from the Ada Lovelace family from NVIDIA. Key on-paper specs include 12 GB of VRAM. It launched with a $599 MSRP, though street prices typically diverge meaningfully from launch pricing — see the linked product cards below for current listings. Data on this page draws on 8 linked listings, 15 synthetic benchmark results (top 10 shown), 14 community AI inference reports (top 12 shown), 84 game frame-rate results (top 15 shown), compiled from TechSpot, Overclocking.com, LocalScore.ai, PC Guide, Hardware Corner, knightli.com llama.cpp GPU Benchmark Scoreboard, llama.cpp GitHub, Local LLM Benchmarks, Puget Systems, 3DMark, LocalLLaMA, PassMark, TopCPU.net; each table row links to its source. Read this page when shopping the GeForce RTX 4070, comparing it against other graphics cards in your build, or sizing it for a specific workload (gaming at 1080p/1440p/4K, synthetic benchmark scores, or local LLM inference).
Gaming Performance (reported FPS)
Average and 1% low frame rates by game, resolution, and quality preset. Bars are scaled against the fastest result on this page.
| Game | Resolution | Settings | Relative | Avg FPS | 1% low | Source |
|---|---|---|---|---|---|---|
| Counter-Strike 2 | 1080p | High | 313 fps | — | PC Guide 2026-06-10 | |
| Doom Eternal | 1440p | RT Ultra RT on | 249 fps | — | TechSpot 2023-04-12 | |
| Counter-Strike 2 | 1440p | High | 214 fps | — | PC Guide 2026-06-10 | |
| Rainbow Six Extraction | 1440p | — | 191 fps | — | TechSpot 2023-04-12 | |
| Call of Duty: Modern Warfare II | 1440p | — | 182 fps | — | TechSpot 2023-04-12 | |
| Counter-Strike 2 | 1440p | DLSS Ultra Quality | 165 fps | 150 fps | Puget Systems 2023-08-25 | |
| Shadow of the Tomb Raider | 1440p | RT Ultra RT on DLSS Balanced | 164 fps | — | Overclocking.com 2023-04-13 | |
| Counter-Strike 2 | 1440p | Ultra | 150 fps | 135 fps | Puget Systems 2023-08-25 | |
| Hitman 3 | 1440p | Ultra | 147 fps | — | TechSpot 2023-04-12 | |
| Hitman 3 | 1440p | — | 147 fps | — | TechSpot 2023-04-12 | |
| Resident Evil Village | 1440p | RT Ultra RT on | 144 fps | — | TechSpot 2023-04-12 | |
| The Outer Worlds | 1440p | — | 141 fps | — | TechSpot 2023-04-12 | |
| Shadow of the Tomb Raider | 1440p | — | 139 fps | — | TechSpot 2023-04-12 | |
| Shadow of the Tomb Raider | 1440p | Highest | 139 fps | — | TechSpot 2023-04-12 | |
| Cyberpunk 2077 | 1440p | Ultra | 91 fps | — | Overclocking.com 2023-04-13 |
AI Inference Performance
Tokens per second under each model + quantization. Higher = faster generation. Bars compare runs across the same model.
| Model | Quantization | Relative | Tokens/sec | VRAM used | Source |
|---|---|---|---|---|---|
| llama3.2:1b | q4_K_M llama.cpp | 283.0 tok/s | — | LocalScore.ai retrieved 2026-07-10 | |
| llama2:7b | q4_0 llama.cpp | 92.3 tok/s | — | knightli.com llama.cpp GPU Benchmark Scoreboard 2026-04-23 | |
| llama2:7b | Q4_0 llama.cpp (Vulkan) | 92.3 tok/s | — | llama.cpp GitHub (Vulkan scoreboard) 2025-01-12 | |
| llama2:7b | Q4_0 llama.cpp (Vulkan, FA on, coopmat2) | 91.5 tok/s | — | llama.cpp GitHub (Vulkan scoreboard) 2025-01-12 | |
| llama3.1:8b | q4_K_M llama.cpp | 78.0 tok/s | — | Local LLM Benchmarks (kunalganglani.com) 2024-06 | |
| llama3.1:8b | q4_K_M llama.cpp | 76.3 tok/s | — | LocalScore.ai retrieved 2026-07-10 | |
| qwen3:8b | q4_K_XL llama.cpp | 52.1 tok/s | — | Local LLM Speed Comparison — singhajit.com 2025-05 | |
| llama3.1:8b | q4_K_XL llama.cpp | 52.1 tok/s | — | Ajit Singh / Hardware-Corner 2024-06 | |
| qwen3:8b | Q4_K_XL llama.cpp 16K context | 52.1 tok/s | — | Hardware Corner 2025-11-02 | |
| qwen3:0.6b | — ollama | 47.1 tok/s | — | LocalLLaMA 2026-04-15 | |
| qwen3:8b | Q4_K_XL llama.cpp 32K context | 38.1 tok/s | — | Hardware Corner 2025-11-02 | |
| qwen2.5:14b | q4_K_M llama.cpp | 37.9 tok/s | — | LocalScore.ai retrieved 2026-07-10 |
Synthetic Benchmarks
Higher is better. Bars are scaled within each benchmark family (multi-thread, single-thread, etc.) so you can compare like-with-like at a glance.
| Benchmark | Relative | Score | Source |
|---|---|---|---|
| 3DMark Fire Strike | 37,790 points | Overclocking.com 2023-04-13 | |
| PassMark G3D Mark | 26,909 pts | PassMark retrieved 2026-04-20 | |
| 3DMark Time Spy | 17,887 points | TopCPU.net retrieved 2026-07-10 | |
| 3DMark Time Spy | 16,822 points | 3DMark 2023-06 | |
| 3DMark Port Royal | 11,126 points | 3DMark (UL Benchmarks database — Ryzen 7 7700X system) 2023-04 | |
| 3DMark Port Royal | 10,953 points | PC Guide 2024-01 | |
| 3DMark FireStrike Ultra | 9,880 points | PC Guide 2024-01 | |
| 3DMark Time Spy Extreme | 8,592 points | Overclocking.com 2023-04-13 | |
| 3DMark Time Spy Extreme | 8,320 points | PC Guide 2024-01 | |
| 3DMark Speed Way | 4,485 points | Overclocking.com 2023-04-13 |
Products Featuring the GeForce RTX 4070
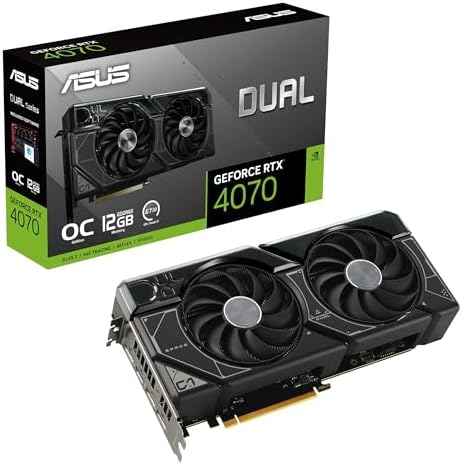


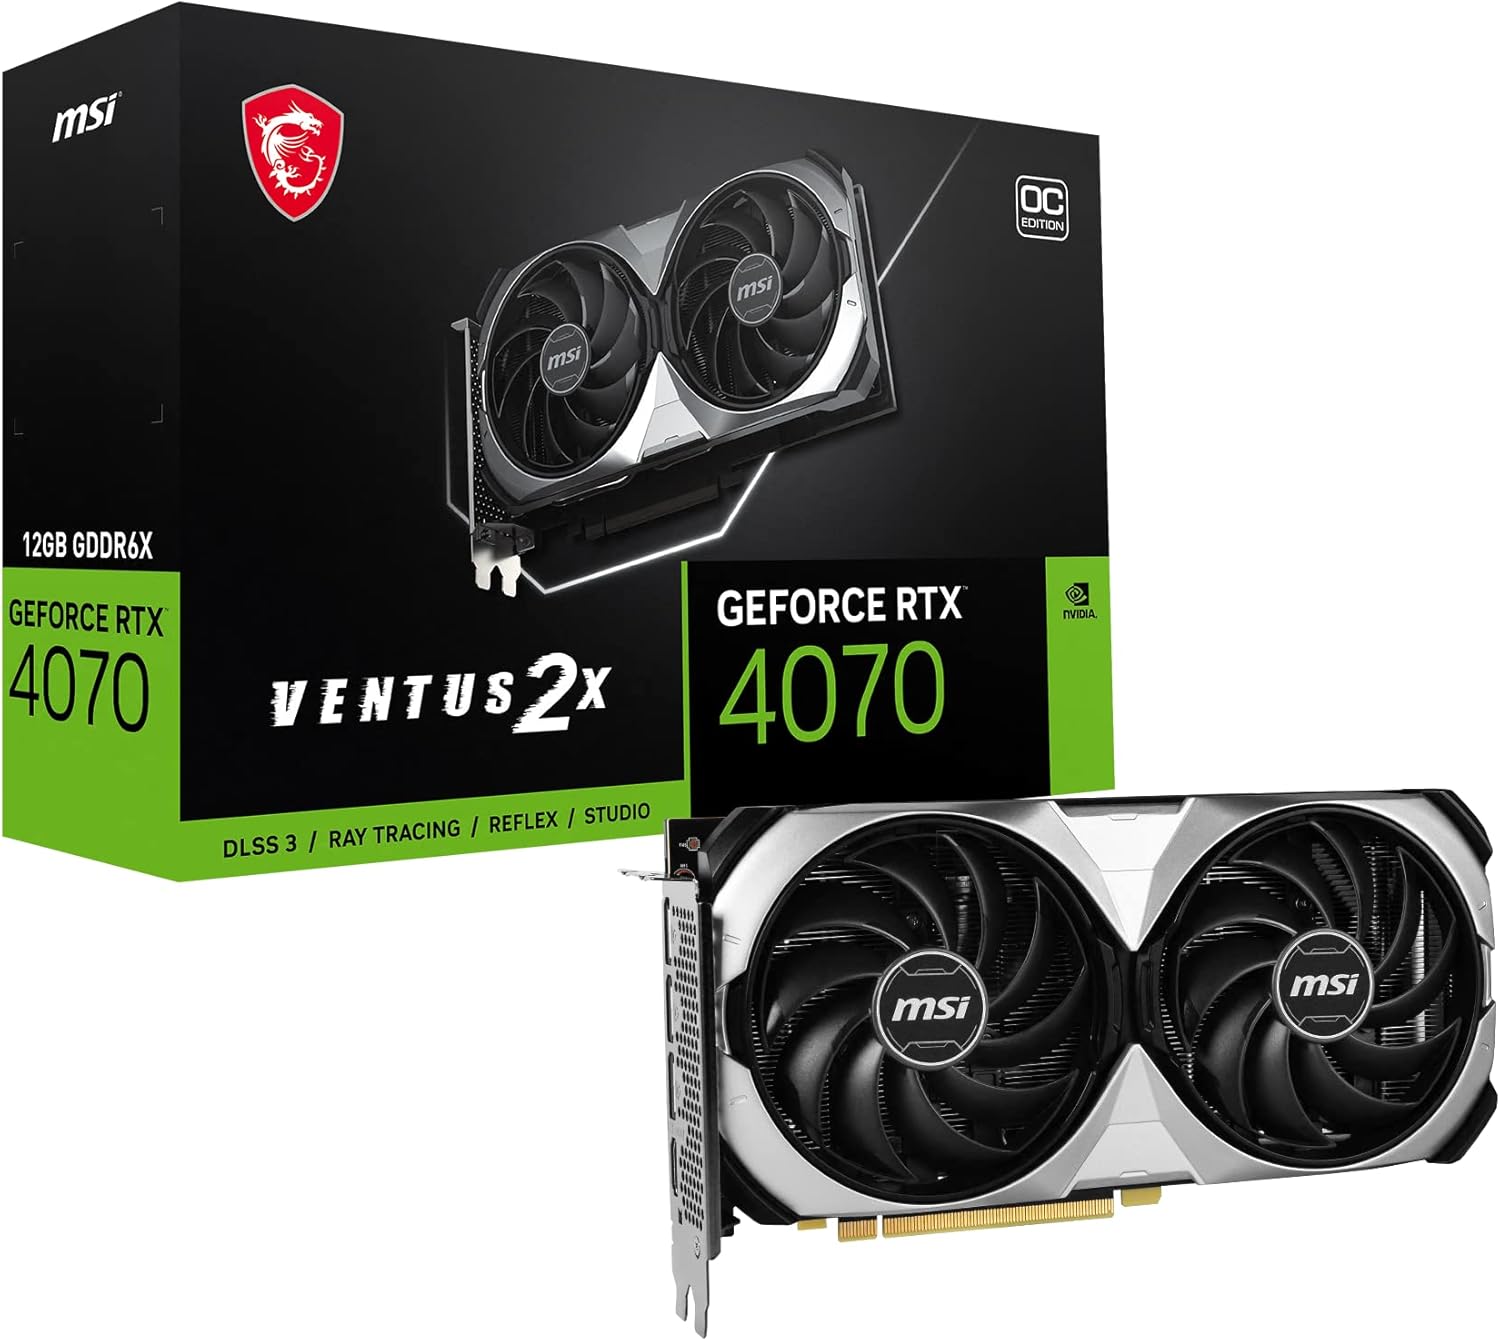
Full Specifications
| VRAM | 12 GB |
|---|
GeForce RTX 4070 — Frequently Asked Questions
What is the GeForce RTX 4070 best used for?
GeForce RTX 4070 is a 12 GB VRAM Ada Lovelace-family graphics card. 1080p/1440p gaming and lightweight content creation are the headline use cases; the benchmark tables on this page place it within its generation.
Where do the GeForce RTX 4070 benchmark numbers come from?
Each benchmark row on this page names its source (public benchmark databases such as TechPowerUp, PassMark, Geekbench and Cinebench, and community reports such as r/LocalLLaMA threads) and links to it, so every number can be checked against the original.
Can the GeForce RTX 4070 run local LLMs?
Yes — AI inference results for the GeForce RTX 4070 are on file; the AI Inference Performance section on this page lists model, quantization and tokens-per-second for each run. 12 GB VRAM fits 8-13B-parameter models at Q4_K_M.
Where can I buy the GeForce RTX 4070?
Amazon listings for the GeForce RTX 4070 are linked at the top of this page and in the Products Featuring the GeForce RTX 4070 section. SpecPicks earns a small affiliate commission on qualifying purchases, at no extra cost to the buyer.
Buying guides that rank the GeForce RTX 4070's class
This page is the raw performance data. The guides below turn it into a ranked pick for a specific build.
Editorial guides covering the GeForce RTX 4070
In-depth SpecPicks reviews, build guides, and head-to-heads referencing this graphics card.
- RTX 3060 12GB vs RTX 4070 12GB for Qwen2.5 14B (2026)
- Best GPU for Qwen3 8B in 2026
- RTX 5060 8GB vs RTX 4070 12GB for Qwen3 14B: Does 8GB Fit? (2026)
- Best Hardware for Running Qwen3 Locally in 2026
- 1080p Gaming PC Build 2026: Cost, Parts, FPS
- 9800X3D + RTX 5070 Ti PC Build 2026: 1440p High-Refresh
- 4K Gaming PC Build 2026: Cost, Parts, FPS
- 1440p Gaming PC Build 2026: Cost, Parts, FPS
- Browse all SpecPicks reviews →
More guides & deep dives from the SpecPicks archive
Browse all articles & guides →- Emulation Hardware in 2026: FPGA, Software, and Cart-Reader Ecosystems
- Best Retro Handhelds in 2026 — From $35 to $500
- Best 1440p Gaming GPUs in 2026
- How to Build a Windows 98 Retro PC in 2026
- RTX 4070 Super vs RX 7800 XT — Which to Buy in 2026
- Best Budget Gaming PC Build 2026 — ~$1,000 ($800 on Sale)
- The Complete Voodoo5 5500 AGP Driver Guide (2026 Edition)
More reviews from the SpecPicks archive
Browse all reviews →- The Budget Streaming Starter Kit: Mic, Light, and Webcam Under $250
- vLLM vs llama.cpp for Single-User Chat on a 12GB GPU (2026)
- Best PC Gaming Gear for Console Players Making the Switch in 2026
- Best Budget GPU for Local LLM Inference Under $400 (2026)
- RTX 3060 12GB vs Arc B580 for 1080p Gaming: Which Wins?
- Running a 26B LLM Locally With No GPU: The CPU Setup Guide
- Forza Horizon 6 on Steam Deck: Best Settings, Dock & Storage in 2026
- Tesla Caps AI Spend at $200/Week — The Local RTX 3060 Rig Case
- Best CPU Cooler for Ryzen 7 5800X Overclocking in 2026
- Microsoft Now Points to 32GB RAM for Windows 11 Gaming — What It Means for Your Build
- Raspberry Pi 5 16GB for Local LLMs: What Models Actually Fit?
- Best PC Gaming Controllers in 2026: 5 Top Picks
- Chrome Using Too Much RAM? Fixes + Hardware Upgrades
- Best Internal SSDs for Gaming PCs (2026)
- How to Find and Join Active UT99 and UT2004 Servers in 2026
- Best Budget Gaming Peripherals in 2026
- Qwen3 0.6B: Raspberry Pi 4 8GB vs Ryzen 5 5600G for Tiny-Model Hosts (2026)
- Ryzen 5 5600G vs Ryzen 7 5700X for a Budget Homelab and Virtualization Box in 2026
- Best Raspberry Pi for a Retro Console Build in 2026: Pi 4 8GB vs Pi Zero 2 W
- Voodoo5 5500 AGP Won't POST: Complete Troubleshooting Guide for 2026 Restorations
- Pentium II/III LAN Party Build Brand Profile: Why Creative and 3dfx Defined the Era
- No Wonder My CPU Was Hitting 100°C: 7 Build Mistakes
- Shared ChatGPT and Claude Chat Links Are Spreading Malware (And Local LLMs Fix It)
- Build a Pi Zero W Handheld Retro Emulator in 2026: Full Parts List and Setup
More buying guides from SpecPicks
Browse all buying guides →- Best DDR5 RAM for Gaming PCs in 2026
- Best Gaming Mice for 2026
- Best GPUs for Running Local LLMs in 2026
- Best 1440p 240Hz Gaming Monitors in 2026
- Best CPUs for Content Creators in 2026
- Best CPUs for Gaming in 2026
- Best Graphics Cards for Gaming in 2026
- Best 4K Monitors for Content Creators in 2026
- Best Tools for Building and Repairing Retro PCs in 2026
- Best GPUs for 4K Gaming in 2026
- Best NVMe External Enclosures for 2026
- Best External SSDs for Content Creators in 2026
- Best Gaming Monitors for 2026
- Best PC Cases for Building in 2026
- Best NVMe SSDs for Gaming in 2026
- Best AM5 Motherboards for 2026
- Best Controllers for PC Gaming in 2026
- Best Retro Gaming Consoles & Handhelds for 2026
- Best Mechanical Keyboards for Gaming in 2026
- Best GPU for Running 27B-32B Local LLMs in 2026
- Best CPU Coolers for 2026
Hardware benchmark data on SpecPicks
All benchmarks →- Quadro RTX 6000 — benchmarks & specs
- Google Coral PCIe Accelerator — benchmarks & specs
- Ryzen 7 5700 — benchmarks & specs
- Raspberry Pi 4 8GB — benchmarks & specs
- RTX 4500 Ada Generation — benchmarks & specs
- Radeon RX 6800M — benchmarks & specs
- AMD Ryzen 9 7950X3D — benchmarks & specs
- NVIDIA GeForce RTX 4070 Ti SUPER — benchmarks & specs
- AMD Ryzen Threadripper PRO 5995WX — benchmarks & specs
- Ryzen 7 7735HS — benchmarks & specs
- NVIDIA GeForce RTX 2060 — benchmarks & specs
- Ryzen 5 7600 — benchmarks & specs
- Apple M4 Max — benchmarks & specs
- Apple M2 Pro 10 Core 3480 MHz — benchmarks & specs
- AMD Ryzen 9 7945HX — benchmarks & specs
- AMD Ryzen 9 7945HX3D — benchmarks & specs
- Intel Core i7-14700K — benchmarks & specs
- Quadro RTX 5000 (Mobile) — benchmarks & specs
- Ryzen 5 7500F — benchmarks & specs
- NVIDIA GeForce RTX 2080 — benchmarks & specs
- Intel Arc B390 GPU — benchmarks & specs
- Radeon RX 6750 GRE 10GB — benchmarks & specs
- Radeon RX 9070 GRE — benchmarks & specs
- AMD Ryzen 9 7950X — benchmarks & specs