

NVIDIA
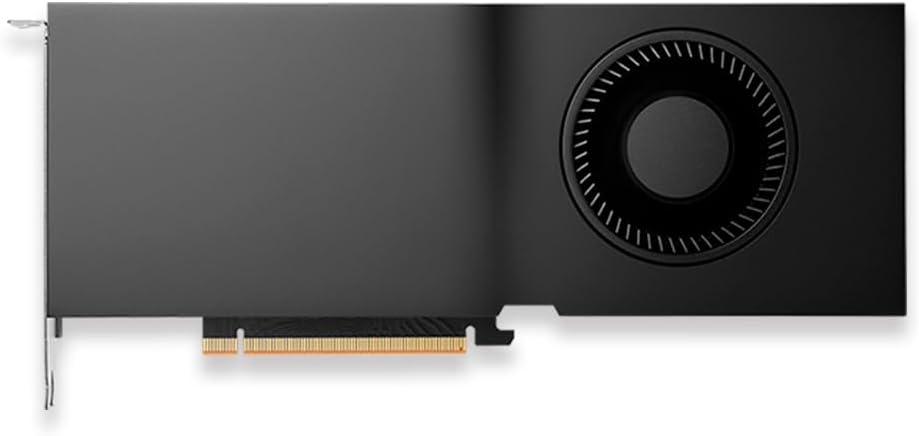
NVIDIA RTX 4000 SFF Ada Generation Workstation Ada Lovelace Architecture Dual Slot Low Profile Professional Graphics Board 900-5G192-2571-000 VD8465
Bottom line: The NVIDIA RTX 4000 SFF Ada Generation Workstation Ada Lovelace is a specs-and-price decision rather than a crowd-consensus one in the graphics cards category, priced around $1,949.95 on Amazon as of 2026-11-12 23:14 UTC. Check the specification table below against one or two close alternatives — on price and spec fit, not on star ratings.
As an Amazon Associate, SpecPicks earns from qualifying purchases. Full disclosure →
*Price sourced from Amazon.com. Last updated 2026-11-12. Price and availability subject to change.
Pros & Cons
Pros
- ✓ VD8465 Japanese Authorized Distributor Product
- ✓ Backed by NVIDIA's warranty and support channels
Cons
- ✗ Confirm socket / form-factor / power-rating compatibility against your build before ordering
- ✗ Price, stock, shipping and returns are set by the retailer and may have changed since this page was last updated
Manufacturer description
Ada generation graphic board with a compact form factor for full-size performance
SpecPicks Verdict
SpecPicks scored NVIDIA RTX 4000 SFF Ada Generation Workstation Ada Lovelace… using a rating × review-volume × price-fit model applied to our editorial and benchmark analysis across the graphics cards category. NVIDIA's graphics cards lineup sits within the broader category mid-tier; price and specs are the deciding factors over brand loyalty here. Judge it on the specification table and the price rather than on sentiment: check the figures that decide your use case, then put it side-by-side with two or three close alternatives in the Compare tool before clicking through.
Common buyer scenarios for graphics cards of this kind: matching it to an existing build, replacing a failing part, or upgrading from a previous-generation equivalent. Check the spec table below against your current setup — particularly socket / form-factor / power-rating fields — and confirm compatibility on the retailer's listing before purchase. Prices and stock are set by the retailer and may have moved since this page was last updated.
Video review
TINY 70 watt RTX 4000 SFF ADA Generation GPU For AI, Docker, Plex, Jellyfin, and MORE! — Level1Techs on YouTube
Key Features
- VD8465 Japanese Authorized Distributor Product
- The speed of FP32 calculation is twice as fast as previous generations, which greatly improves the complex 3D processing and graphics simulation workflow
- Up to 2X the throughput compared to previous generations and significantly faster workloads such as video content rendering, architectural design assessments, and virtual prototypes of product design
- Achieve more than twice the previous generation AI performance improvement, support faster FP8 precision data and accelerate the execution of mixed flotation decimal and whole numbers
- It has a large capacity of memory necessary for working with a vast array of data sets and workloads such as rendering, data science, and simulation
Full Specifications
| ASIN | B0D4TXH59M |
|---|---|
| Brand | NVIDIA |
| Model Name | NVIDIA RTX |
| Manufacturer | NVIDIA |
| Model Number | NVIDIA RTX |
| Built-In Media | Quick start guide, support guide, mini DP to DP adapter, ATX bracket |
| Video Processor | NVIDIA |
| Graphics Card Ram | 20 GB |
| Graphics Ram Size | 20 GB |
| Graphics Ram Type | GDDR6 |
| Compatible Devices | Desktop |
| Graphics Coprocessor | NVIDIA RTX 4000 |
| Graphics Description | Exclusive |
| Video Output Interface | Mini DisplayPort |
| Graphics Card Interface | PCI-Express x16 |
| Display Resolution Maximum | 7680x4320 Pixels |
| Graphics Processor Manufacturer | NVIDIA |
Performance Data
View gaming FPS, AI inference throughput, and synthetic scores for the RTX 4000 SFF Ada Generation — the core hardware component in this product. Benchmarks sourced from TechPowerUp, PassMark, and the r/LocalLLaMA community.
Which local LLMs fit in 20 GB?
20 GB holds a 20–27B model at Q4 with a modest context window; 30B-class weights need 24 GB.
- ✅ 7–9B models (Llama 3.1 8B, Qwen 3 8B) — fits at Q4
- ✅ 12–14B models (Qwen 3 14B, Phi-4) — fits at Q4
- ✅ 20–27B models (Gemma 3 27B, Mistral Small) — fits at Q4
- ❌ 30–35B models (Qwen 3 32B, QwQ 32B) — needs 24 GB+
- ❌ 70B models (Llama 3.3 70B, Qwen 2.5 72B) — needs 48 GB+
Across 7 community runs from 4 sources, the RTX 4000 SFF Ada Generation generates a median 58.6 tok/s on 7–9B models at Q4 (per LocalScore (Mozilla Builders)).
Benchmark data for other graphics cards
Ready to buy?
NVIDIA RTX 4000 SFF Ada Generation Workstation Ada Lovelace Architecture Dual Slot Low Profile Professional Graphics Board 900-5G192-2571-000 VD8465 is listed on Amazon. Price, availability, shipping and returns are set by Amazon and its sellers — check the listing for current terms. SpecPicks earns a small commission on qualifying purchases — thank you for supporting independent review work.
*Price sourced from Amazon.com. Last updated 2026-11-12. Price and availability subject to change.
Read our analysis
SpecPicks coverage that features this Graphics Card.
Related Graphics Cards


NVIDIA RTX 4000 SFF Ada Generation Workstation… head-to-head
Side-by-side specs, prices, and a pick for each matchup — no tab-switching.
More guides & deep dives from the SpecPicks archive
Browse all articles & guides →- How to Build a Windows 98 Retro PC in 2026
- Best Retro Handhelds in 2026 — From $35 to $500
- Emulation Hardware in 2026: FPGA, Software, and Cart-Reader Ecosystems
- RTX 4070 Super vs RX 7800 XT — Which to Buy in 2026
- The Complete Voodoo5 5500 AGP Driver Guide (2026 Edition)
- Best Budget Gaming PC Build 2026 — ~$1,000 Parts List
- Best 1440p Gaming GPUs in 2026
More reviews from the SpecPicks archive
Browse all reviews →- How Fast Is Local LLM Inference on a Ryzen 7 5800X (CPU-Only, No GPU)?
- Best Budget SSDs for Retro and Homelab Builds in 2026
- Best Mechanical Keyboard for Office and Hybrid Coding in 2026
- The Best Retro Game Emulators for Mac in 2026
- How to run DeepSeek-R1 32B on AMD Radeon RX 7900 XTX
- The vLLM MCP Vulnerability: What Local LLM Operators Need to Do
- Ryzen 9800X3D Idle Temp: What's Normal (2026 Guide)
- Best CPU cooler for the Ryzen 7 5800X in 2026
- Prime Day 2026: Logitech Gaming Mice Drop Up to 47% Off
- Build a Raspberry Pi Bird-Song Logger with a USB Mic (2026)
- Best Budget Streaming Setup for Beginners in 2026
- Athlon XP + Radeon 9800 Pro AGP Build Guide: 2003 Period-Correct Rig
- Best GPU for Local Llama 3 8B Under $400: Why the RTX 3060 12GB Wins
- Building a 1998 Voodoo2 SLI Glide Rig in 2026: CompactFlash Boot and Quake II
- Best CPU for Gaming in 2026: Intel vs AMD Showdown
- Microsoft's Copilot Super App vs a Local RTX 3060 Ollama Box in 2026
- Intel IPEX-LLM vs Ollama on AMD: AI Rig Guide 2025
- Imaging Your Big-Box CD-ROM Collection: A CompactFlash + IDE Workflow
- Intel Arc Stable Diffusion Benchmark: A770, B580 & B60 (2025)
- OpenAI and Broadcom Unveil 'Jalapeño' Inference Chip
- Best Gaming Gifts Under $60 in 2026
- Running a Local Coding Agent on a Small Model: What Actually Breaks (and How to Fix It)
- Best 12GB GPU for Stable Diffusion: RTX 3060 in 2026
- Best USB Microphone for Streaming and Podcasting (2026)
Earliest SpecPicks reviews
Browse full archive →- Best GPU for Llama 3.1 8B (2026)
- Best GPU for Qwen 3 14B (2026)
- Best GPU for Qwen 3 32B (2026)
- Best GPU for Llama 3.1 70B (2026)
- Best GPU for DeepSeek-R1 32B (2026)
- Best GPU for Llama 3.1 405B (2026)
- How to run Llama 3.1 8B on NVIDIA GeForce RTX 5090
- How to run Qwen 3 14B on NVIDIA GeForce RTX 5090
- How to run Qwen 3 32B on NVIDIA GeForce RTX 5090
- How to run Llama 3.1 70B on NVIDIA GeForce RTX 5090
- How to run DeepSeek-R1 32B on NVIDIA GeForce RTX 5090
- How to run Llama 3.1 8B on NVIDIA GeForce RTX 4090