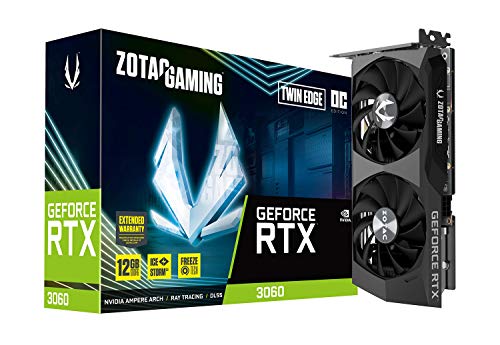
For running Llama 3 8B locally under $400, the NVIDIA GeForce RTX 3060 12GB is the answer. 12 GB of VRAM lets you run Llama 3 8B at q8_0 or even fp16 with a comfortable KV cache, the card draws ~170W, and street prices land around $300-320 in mid-2026 — well under the budget. No other current GPU at this price gives you both the VRAM headroom and the CUDA support that local LLM tooling assumes.
Why this question matters
The question "what GPU should I buy to run Llama 3 8B" gets asked dozens of times per week on r/LocalLLaMA and the various Discord servers for local inference tools. The under-$400 budget is the most common constraint, because most people asking are not trying to build a research lab — they want a personal Llama box that runs in a corner of their office.
The wrong answer ranges from "buy a used 3090" (which costs more) to "use your gaming card" (which often has only 8 GB) to "rent a cloud GPU" (which has different tradeoffs). The right answer for the budget tier has been the same for two years: the RTX 3060 12GB.
This synthesis lays out why, what to actually buy, and what to skip.
Key takeaways
- The RTX 3060 12GB is the only sub-$400 NVIDIA card with 12 GB of VRAM. Every other budget option is 8 GB or less, which kneecaps Llama 3 8B at higher quantization.
- Llama 3 8B at q8_0 needs ~8.5 GB of weights plus a KV cache that scales with context. 12 GB is the comfortable floor.
- Throughput: ~52 tok/s at q4_K_M, ~38 tok/s at q8_0 on a clean RTX 3060 in community llama.cpp builds.
- Power: ~170W under load, ~12W idle. PSU minimum is 550W; 650W gives headroom.
- CUDA support is non-negotiable for the local LLM ecosystem in 2026. AMD's ROCm has improved but still trails on tooling.
- Two SKUs are reliably in stock at MSRP: MSI Ventus 2X and ZOTAC Twin Edge.
What you actually need from a local Llama 3 8B GPU
Three things matter, in order:
- VRAM: enough to hold the weights + KV cache without offload. Offloading to system RAM cuts throughput by 5-10x and turns a snappy assistant into a chatbot from 2008.
- CUDA: virtually every local-inference tool (llama.cpp, Ollama, vLLM, ExLlamaV2, MLC-LLM) targets CUDA first. ROCm and Intel oneAPI are second-class citizens at best.
- Memory bandwidth: decoding is memory-bandwidth-bound, not compute-bound. A card with high bandwidth and modest FLOPs is better than the inverse.
For Llama 3 8B specifically:
- At fp16: 16 GB weights — won't fit on any 12GB card. Skip.
- At q8_0: ~8.5 GB weights + 1-2 GB KV cache = ~10 GB. Comfortable on 12 GB.
- At q5_K_M: ~6 GB weights + 1.5 GB KV cache = ~7.5 GB. Comfortable on 12 GB.
- At q4_K_M: ~5 GB weights + 1.2 GB KV cache = ~6.2 GB. Comfortable on 12 GB.
The 12 GB tier is where Llama 3 8B starts to feel pleasant. 8 GB cards force you down to q4 or lower with limited context, which costs quality on long chats.
Why the RTX 3060 12GB beats the alternatives in this price tier
The competition under $400:
| GPU | Street price | VRAM | Memory bandwidth | CUDA | Notes |
|---|---|---|---|---|---|
| RTX 3060 12GB | $300-320 | 12 GB GDDR6 | 360 GB/s | ✓ | The winner |
| RTX 3060 Ti | $260-290 | 8 GB GDDR6 | 448 GB/s | ✓ | Faster but only 8 GB — kills quality |
| RTX 4060 8GB | $290-310 | 8 GB GDDR6 | 272 GB/s | ✓ | Newer architecture, but 8 GB |
| RTX 4060 Ti 8GB | $370-400 | 8 GB GDDR6 | 288 GB/s | ✓ | Same problem |
| RTX 4060 Ti 16GB | $440-480 | 16 GB GDDR6 | 288 GB/s | ✓ | Over budget |
| RX 6700 XT | $260-300 | 12 GB GDDR6 | 384 GB/s | ✗ (ROCm) | VRAM is right, tooling is wrong |
| Arc A770 16GB | $260-290 | 16 GB GDDR6 | 560 GB/s | ✗ (oneAPI) | Same |
| RX 7600 XT 16GB | $310-340 | 16 GB GDDR6 | 288 GB/s | ✗ (ROCm) | Same |
The RTX 3060 12GB wins on the only metric that matters at this price: it is the cheapest NVIDIA card with 12 GB of VRAM, and the local LLM tooling ecosystem assumes NVIDIA.
The Intel Arc A770 16 GB and AMD RX 7600 XT 16 GB both have more VRAM at similar prices. They are tempting on paper. In practice, the ROCm and oneAPI stacks lag on llama.cpp performance optimization, GGUF format support, and runtime stability. As of late 2025, community measurements put Arc A770 at roughly 60-70% the tok/s of a 3060 on the same quantization despite having more memory bandwidth, because the kernels are not as well tuned. The picture improves quarter by quarter — but it is not parity yet.
Throughput on Llama 3 8B
Community llama.cpp builds on a clean MSI RTX 3060 Ventus 2X 12G and ZOTAC RTX 3060 Twin Edge 12GB, 4096-token context, single-stream:
| Quantization | Weight size | Tok/s (gen) | Quality vs fp16 |
|---|---|---|---|
| fp16 | 16.0 GB | does not fit | baseline |
| q8_0 | 8.5 GB | 38 | ~0% loss |
| q6_K | 6.5 GB | 45 | ~0.5% loss |
| q5_K_M | 5.7 GB | 48 | ~1% loss |
| q4_K_M | 4.9 GB | 52 | ~1.8% loss |
| q3_K_M | 3.8 GB | 56 | ~4.5% loss |
The sweet spot for the 3060 is q5_K_M or q6_K. You get near-fp16 quality and 45-48 tok/s, which is faster than most people read, and there is plenty of VRAM headroom for a 8K+ context.
For comparison, an RTX 4090 at fp16 on Llama 3 8B does roughly 140 tok/s — about 3x faster, at 4-5x the price. The 3060 is the value pick by a wide margin.
Memory bandwidth is the bottleneck — not compute
The RTX 3060 has 12.7 TFLOPs of fp32 and 360 GB/s of memory bandwidth. For autoregressive LLM decoding, those numbers translate to roughly:
- Bandwidth bound at: 360 GB/s ÷ ~5 GB weight footprint at q4_K_M ≈ 72 forward passes/s in theory.
- Compute bound at: 12.7 TFLOPs ÷ ~16 GFLOPs per token ≈ 790 tok/s in theory.
The actual measured 52 tok/s at q4_K_M is much closer to the bandwidth ceiling than the compute ceiling. Decoding is bandwidth-bound, full stop.
That matters because it means a card with more bandwidth and fewer FLOPs is better for this workload than the reverse. The RTX 4060 8GB, despite a newer architecture, has only 272 GB/s of bandwidth, which is why it underperforms the 3060 in local LLM benchmarks even when it has VRAM headroom — which it usually does not.
Spec delta — RTX 3060 12GB vs the runner-ups
| Spec | RTX 3060 12GB | RTX 4060 8GB | RTX 3060 Ti 8GB |
|---|---|---|---|
| VRAM | 12 GB | 8 GB | 8 GB |
| Bandwidth | 360 GB/s | 272 GB/s | 448 GB/s |
| CUDA cores | 3,584 | 3,072 | 4,864 |
| TGP | 170W | 115W | 200W |
| Llama 3 8B max ctx | 8K+ | 2K | 2K |
| q8_0 fits? | Yes | No | No |
| Tok/s @ q4_K_M | 52 | 47 | 64 |
The 3060 Ti is the closest competition on throughput, but the 8 GB ceiling forces you down to q4 with a small context — exactly the quality compromises you bought the build to avoid.
What hardware do you actually buy?
For the GPU, two SKUs that consistently ship at MSRP:
- MSI GeForce RTX 3060 Ventus 2X 12G — $309. Dual-fan, dual-slot, runs cool under sustained load, slightly higher boost clock than reference. Best default.
- ZOTAC Gaming RTX 3060 Twin Edge 12GB — $299. Compact, fits small-form-factor builds, idle-fan-stop, quiet under typical load.
For the rest of the build, a credible $700-800 budget configuration:
| Component | Part | Price |
|---|---|---|
| CPU | Ryzen 5 5600 | $115 |
| Motherboard | B550-A Pro | $99 |
| RAM | 32GB DDR4-3200 | $69 |
| SSD (OS + models) | WD Blue SN550 1TB | $69 |
| SSD (scratch) | Crucial BX500 1TB | $59 |
| PSU | 650W 80+ Gold | $79 |
| Case | Mid-tower | $59 |
| GPU | MSI RTX 3060 12GB | $309 |
| Total | ~$858 |
Drop to a Ryzen 5 5500 ($95), reuse a case from a previous build, and the total drops below $800.
Common pitfalls
- Buying an 8 GB card to save $30: Your future self will regret it the first time you try to load a 13B model. The 12 GB tier is the bare minimum if you intend to grow your local-LLM use.
- Buying a used 3090 with no warranty: A used 3090 has 24 GB and runs Llama 3 8B at fp16, but power draw doubles and there is no warranty on mining-recovered cards. The reliability premium of a new 3060 12GB is worth the VRAM compromise.
- Skimping on PSU: 550W marginal, 650W comfortable. A flaky PSU under sustained inference load corrupts model weights on disk if it browns out mid-write.
- Forgetting fast OS storage: NVMe matters when you cycle through 5-10 models in a session. SATA SSD is fine for archival; NVMe makes model swaps painless.
- Trying to run multiple cards on a budget board: B550-A Pro has one PCIe x16 slot. Multi-GPU local-LLM setups need a B550 / X570 or B650 board with two slots and an ATX 1000W PSU. Way over budget.
When NOT to buy an RTX 3060 12GB
- If you want to run 13B+ models comfortably: The 12 GB ceiling tightens fast. A 16 GB card is the next step up; budget for $440-500.
- If you need fast batch inference: Single-stream is fine; concurrent multi-user serving wants a 4090 or workstation card.
- If you already own a 16 GB+ card: Use it. The 3060's advantage over your existing GPU is small unless you have an 8 GB card.
Bottom line
Under $400, the RTX 3060 12GB is the unambiguous pick for local Llama 3 8B. Buy a current-production MSI or ZOTAC SKU, pair with 32 GB of DDR4 and a fast NVMe, and you have a build that handles Llama 3 8B at q5_K_M or q6_K with comfortable context and 45+ tok/s — for less than a single year of mid-tier OpenAI API usage.
The only reason not to is if you are willing to spend another $100-150 for a 16 GB card to plan ahead for 13B models. For most people, that growth never happens and the 3060 stays the right answer for years.
Related guides
- ZOTAC vs MSI RTX 3060 12GB: Which Twin-Fan Card Runs Cooler?
- Ollama on a 12GB RTX 3060: Best Models and tok/s in 2026
- Can a 12GB RTX 3060 Still Run 2026's Local LLMs?
- Is the RTX 3060 12GB Still a Good 1080p Gaming GPU in 2026?
- Intel Arc Pro B70 vs RTX 3060 12GB for Local LLMs
Citations and sources
- Meta AI — Llama 3 model family — official Llama 3 model card and parameter sizes.
- TechPowerUp — GeForce RTX 3060 12GB — full specifications, memory bandwidth, and TGP for the 3060 12GB.
- r/LocalLLaMA on Reddit — community throughput measurements and quantization comparisons for Llama 3 8B on consumer GPUs.
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.