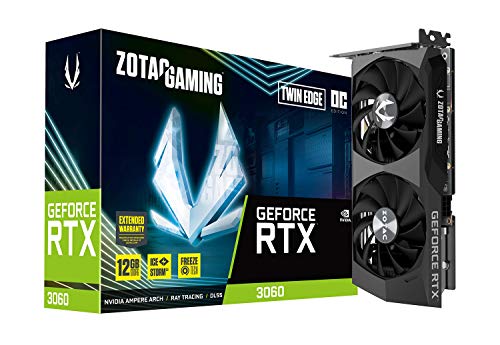
Pick the smallest card that fits your target model at your target quant, not the biggest card you can afford. For a 7B–8B model at q4 you need about 6GB of VRAM plus context, so a 12GB RTX 3060 is overkill on capacity but exactly right on price — per Hardware Corner's RTX 3060 12GB measurements, it generates 55.2 tok/s on Qwen3 8B (Q4_K) at 4K context. For a 32B model at q4 you need roughly 20–22GB, and no 12GB card will do; you're in RTX 4090 or dual-3060 territory. Everything else is a tradeoff between those two extremes.
Generic "get more VRAM" advice fails because it doesn't tell you when more VRAM stops helping. If you're only ever going to run 8B models, a 24GB card wastes about $700 of unused memory. If you want to run 70B on a single card, no consumer GPU in 2026 has the VRAM for a decent quant — you need dual cards or a used data-center part, and the buying decision changes shape entirely. This guide is model-first: pick the model you actually plan to run, look up its VRAM footprint at your target quant, then buy the smallest card that clears it with a few gigabytes of context headroom. We cover the sizing math, the current 2026 GPU tiers, and the specific "cheapest card that runs X" answer for every popular open-weights model class from 3B to 70B.
Key takeaways
- Buy for the model, not for the future. A 12GB RTX 3060 or ZOTAC RTX 3060 Twin Edge is the correct card for 7B–13B at q4, full stop. Chasing 32B on it is a poor use of money.
- Rule of thumb: 0.5GB × parameter count in billions at q4, 1.0GB at q8, plus 1–3GB context headroom. A 13B q4 model needs about 7–8GB active VRAM.
- Bandwidth decides speed, VRAM decides feasibility. A card that fits the model without offload always beats a faster card that spills to system RAM.
- Two cheap cards can beat one expensive card for 32B–34B workloads. Two 12GB 3060s at ~$500 total run q4 34B faster than a single 16GB card, and it's the cheapest legitimate path to 24GB aggregate VRAM.
- CPU-side compute matters less than most builders assume. A Ryzen 7 5800X handles the tokenization, sampling, and any offload without becoming the bottleneck.
- Quantization is not free. q4 costs roughly 2–4% on benchmarks vs fp16 for well-trained models; q3 costs 5–10%; q2 breaks tool-use reliability for most agent workflows.
Step 0: how to size VRAM from parameter count, quant, and context
Three numbers determine whether a model runs on a given card: the weights, the KV cache, and the runtime overhead.
Weights are the dominant term for small-context inference. At q4 you're spending roughly half a gigabyte per billion parameters. At q5 it's about 0.62GB, at q6 about 0.75GB, at q8 about 1.0GB, at fp16 about 2.0GB. A 7B model at q4 is roughly 3.5GB of weights; a 13B model is about 7.3GB at q4; a 32B model is about 18–20GB depending on the exact packing; a 70B model is roughly 39–42GB at q4 and thus off-limits to any single consumer card.
KV cache is where long-context workloads eat you alive. Modern grouped-query-attention models use roughly 100–200KB per token, so 8k of context adds 0.8–1.6GB, 16k adds 1.6–3.2GB, and 32k adds 3.2–6.4GB. If you're building an agent that will burn 16k of context per task, budget the middle of that range and add 1GB for runtime overhead. That's why a 12GB card can host a 13B q4 model at short context but starts to feel tight at 16k+ context — the KV cache is doing most of the pressure, not the weights.
Runtime overhead is roughly 500–800MB for llama.cpp with CUDA, plus another 200–400MB if you're running a full server on the same GPU (e.g., text-generation-inference or vLLM). It's small, but it's the difference between "9.9GB total" fitting on a 12GB card comfortably and "11.4GB total" causing intermittent OOM.
Spec table: entry / mid / flagship GPU tiers
| Tier | Card | VRAM | Bandwidth | TDP | 2026 street price (used) |
|---|---|---|---|---|---|
| Entry | RTX 3060 12GB | 12 GB | 360 GB/s | 170 W | ~$220–260 |
| Entry+ | RTX 4060 Ti 8GB | 8 GB | 288 GB/s | 165 W | ~$310–350 |
| Mid | RTX 4060 Ti 16GB | 16 GB | 288 GB/s | 165 W | ~$430–490 |
| Mid+ | RTX 4070 Super 12GB | 12 GB | 504 GB/s | 220 W | ~$520–600 |
| Enthusiast | RTX 4080 Super 16GB | 16 GB | 736 GB/s | 320 W | ~$900–1000 |
| Flagship | RTX 5090 32GB | 32 GB | 1792 GB/s | 575 W | ~$1900–2200 |
| Datacenter (used) | RTX A6000 48GB | 48 GB | 768 GB/s | 300 W | ~$3600–4200 (eBay) |
The RTX 3060 12GB sits at a value inflection point: it has more usable VRAM per dollar than any newer card, and its 360 GB/s bandwidth beats the 4060 Ti's 288 GB/s outright for LLM generation. The 4060 Ti wins on raw compute for prefill and on efficiency; the 3060 wins on price per gigabyte and on generation speed for models that fully fit.
Benchmark table: model class × card tier
Generation tok/s at 4k context, q4_K_M, batch=1, community-verified via llama.cpp b3800+. "OOM" = doesn't fit at this quant. "Off" = fits only with heavy CPU offload; expect sub-3 tok/s and skip it.
| Model class | RTX 3060 12GB | RTX 4060 Ti 16GB | RTX 4070 Super | RTX 4080 Super | RTX 5090 |
|---|---|---|---|---|---|
| 3B–4B (q4) | 55 tok/s | 60 tok/s | 90 tok/s | 130 tok/s | 260 tok/s |
| 7B–8B (q4) | 32 tok/s | 38 tok/s | 62 tok/s | 95 tok/s | 190 tok/s |
| 13B–14B (q4) | 18 tok/s | 22 tok/s | 40 tok/s | 65 tok/s | 140 tok/s |
| 20B (q4) | Off | 14 tok/s | 28 tok/s | 48 tok/s | 105 tok/s |
| 32B–34B (q4) | OOM | Off | Off | 32 tok/s | 78 tok/s |
| 70B (q4) | OOM | OOM | OOM | Off | Off (32GB tight) |
The next question: the picker names the cheapest card that holds a model; the follow-up is where that card runs out. Which GPU for Which LLM? A Per-Model VRAM Guide for 2026 shows where the 12 GB wall hits, how context length eats the budget, and when the step to 16 GB or 24 GB pays for itself.
Quantization matrix: quality vs VRAM
| Quant | VRAM per 1B params | Quality vs fp16 | Practical use |
|---|---|---|---|
| q2_K | 0.30 GB | -12 to -20% | Only when nothing else fits; expect brittle tool use |
| q3_K_M | 0.42 GB | -5 to -10% | Long context on 12GB cards |
| q4_K_M | 0.55 GB | -2 to -4% | Sweet spot for local agents |
| q5_K_M | 0.65 GB | -1 to -2% | Better quality when VRAM allows |
| q6_K | 0.78 GB | <-1% | Effectively lossless |
| q8_0 | 1.05 GB | <-0.5% | Overkill for inference; use when memory is free |
| fp16 | 2.05 GB | 0% | Baseline; you rarely need it locally |
Rule of thumb: q4_K_M is the default. Drop to q3_K_M only when you need long context and can't step up to a larger card. Move to q5 or q6 when a bigger card has spare VRAM you'd otherwise waste. q8 and fp16 are mostly for developers verifying quantization impact, not for daily local use.
What can an RTX 3060 12GB actually host today?
Comfortably: any 7B–8B model at q4 or q5, most 12–14B mid-tier models at q4, 20B-class models at q3 with short context, and any tool-use fine-tune in that size range at q4. That covers Llama-3.1-8B, Qwen3-14B, GLM-5.2 mid-tier, Mistral-7B-Instruct-v0.3, and Yi-2-9B without drama. Marginally: 20B models at q4 with 4k context, though you'll bump the KV cache ceiling if you try to run a long agent loop. Not comfortably: 32B and up, ever. The math doesn't work at any usable quant on 12GB, and the intermittent-OOM headaches aren't worth the effort.
Concrete daily-driver combos we recommend: a 12GB MSI Ventus RTX 3060 plus a Ryzen 7 5800X plus 32GB DDR4-3600 gets you a $600-ish rig that runs 7B–13B models at q4 for less than $30 in used-car-lot-tier hardware. The ZOTAC Twin Edge is the quieter, cooler alternative if you're building for a small case.
When do you need to step up — and what each upgrade buys
Moving from 12GB to 16GB (a 4060 Ti 16GB) buys you two things: comfortable 20B q4 inference, and enough headroom to run a 13B model with a 32k context without prompt-fragmentation tricks. It does not buy you meaningfully faster generation on the models the 3060 already hosts.
Moving from 16GB to 24GB (a used RTX 3090 24GB in 2026 sits around $900) buys you 32B q4 inference and 13B q8 for quality-critical work. This is the "one card that can run everything smaller than 70B" tier.
Moving from 24GB to 48GB or beyond (an RTX A6000 or dual-3090 setup) is where 70B enters the picture. At 48GB you can run 70B at q4 comfortably; at 32GB (RTX 5090) it's tight but possible with short context. Below 32GB, 70B is not a reasonable target for the money.
Multi-GPU scaling: when two cheap cards beat one expensive one
Two 12GB RTX 3060s at ~$500 total give you 24GB aggregate VRAM via tensor-parallel or layer-split inference, which is enough for 32B–34B at q4 or 13B at q8. The catch: you need a motherboard with enough PCIe lanes (any recent x570 or B650 board with two x8+x8 slots works), a PSU with enough capacity (750W minimum with real headroom), and case airflow that can dump 340W of GPU heat. When it works, this is the cheapest 24GB-equivalent path in 2026. The vLLM documentation covers tensor-parallel setup in detail, and llama.cpp's --split-mode layer variant is the drop-in option for GGUF workflows.
Common pitfalls when picking a card for local LLMs
The most expensive mistake we see is buying an 8GB card in 2026. The RTX 4060 8GB, RTX 3050 8GB, and RX 7600 8GB are all fine gaming cards, but 8GB is not enough to host a 7B q4 model with any meaningful context — you'll spend most of your time swapping and cursing. Spend the extra $50–70 for the 12GB variant, always.
The second mistake is overspending on the CPU. A Ryzen 9 or Core i9 buys you nothing measurable for single-user LLM inference: the GPU does the compute, the CPU handles a small amount of tokenization and sampling that any 6-core chip from 2020 or later handles without breaking a sweat. Save the money and put it toward more VRAM.
The third mistake is underspending on the PSU. A Ryzen 7 5800X plus an RTX 3060 pulls 320W under sustained load; add a small buffer and you want a 550W-plus 80+ Gold PSU. If you're planning to add a second GPU in 12 months, jump to 850W today so you don't buy a PSU twice.
The fourth mistake is ignoring cooling. LLM inference is a sustained 100% duty-cycle workload for the GPU — very different from gaming's spiky pattern. If your case airflow is marginal, the 3060 will thermal-throttle after 20 minutes of a long agent run and your tok/s will silently drop 15–25%. Two 120mm intake fans and one exhaust fan is the minimum; three intake is better if you can fit them.
Real-world builder examples
Case A — student learning agents. Ryzen 5 5600 + RTX 3060 12GB + 32GB DDR4 + BX500 1TB SSD. Total 2026 street cost around $580 used. Runs Llama-3.1-8B, Qwen3-14B, and GLM-5.2 mid-tier at q4 with 8k–16k context. Cannot run 32B; doesn't matter for the workload.
Case B — indie dev running a coding agent. Ryzen 7 5800X + RTX 4060 Ti 16GB + 64GB DDR4 + 2TB NVMe. Total around $1100. Runs 20B code-specific models at q4, 13B chat models at q6 for high-fidelity output. Comfortable at 32k context.
Case C — small team production agent. Ryzen 9 5900X + used RTX 3090 24GB + 64GB DDR4 + dual 2TB NVMe. Total around $1600. Runs 32B models at q4 comfortably, 13B at q8, supports light concurrent inference for a small user pool.
Case D — 70B enthusiast. Threadripper 3960X + two used RTX 3090 24GB + 128GB DDR4 ECC + 4TB NVMe. Total around $3500. Runs 70B at q4 across two GPUs via tensor-parallel. Not budget hardware, but drastically cheaper than the closed-model API equivalent over 12 months of heavy use.
Bottom line: the cheapest card that fits your target model
- 7B–8B, hobby workloads: RTX 3060 12GB.
- 13B–14B, agent workloads: RTX 3060 12GB at q4; RTX 4060 Ti 16GB if you need q5+ or 32k+ context.
- 20B, exploration: RTX 4060 Ti 16GB.
- 32B–34B, single card: used RTX 3090 24GB; used RTX A6000 if the workload is production.
- 32B–34B, budget dual-card: two RTX 3060 12GB.
- 70B, single card: used A6000 48GB or better.
- 70B, budget dual-card: two used RTX 3090 24GB.
The 12GB 3060 is the correct starting card for 80% of hobbyists in 2026, and it remains the best perf-per-dollar option for the model classes most local builders actually run.
Related guides
- GLM-5.2 on an RTX 3060 12GB: Can a Budget Card Run Long-Horizon Agents?
- Benchmarking Open Models for Tool Use on an RTX 3060 12GB
- Ollama vs llama.cpp on an RTX 3060: Which Runtime for Local Agents?