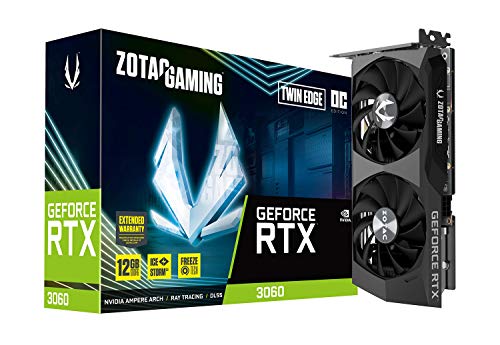
HiDream-O1 1.5 just landed at #3 on the Artificial Analysis text-to-image leaderboard, ahead of Nano Banana 2 and trailing only two closed-weight frontier models. The next question for anyone building a local rig: can you run it on a 12GB RTX 3060? The short answer is yes, with quantization and tiling — generation takes 20-45 seconds per 1024px image at fp8 instead of the 4-8 seconds an H100 manages, but the output quality is identical and your privacy is not negotiable.
Open-weight text-to-image models have been on a fast curve. Two years ago a 12GB consumer card maxed out at 512×512 SDXL with painful trade-offs; today the same card hosts a model that scores within ten points of the closed-weight leaders at 1024×1024 with reasonable iteration speed. HiDream-O1 1.5 is the latest illustration that the open-image ecosystem is reaching diminishing returns at the top of the stack — and the cheapest interesting on-ramp is still the 3060 12GB card paired with a competent host like the Ryzen 5 5600G and a fast NVMe drive for the model files.
Key takeaways
- HiDream-O1 1.5 sits at #3 on the Artificial Analysis image leaderboard, the highest-ranked open-weight model published this quarter.
- On a 12GB RTX 3060, expect roughly 20-45 seconds per 1024px image at fp8/int8 quantization; native fp16 will offload to system RAM and slow to 60-90s.
- ComfyUI is the host you want — community nodes typically land within days of an open-weight release, and the graph editor is the right place to tune precision, scheduler, and tiling.
- Local pays back fastest for high-volume creative work, sensitive-prompt workflows, and offline use; hosted APIs win on time-to-first-image and on having the absolute latest checkpoints.
What HiDream-O1 1.5 shipped and why it matters
HiDream-O1 1.5 is the second update in HiDream's "O1" series of diffusion-transformer image models. The 1.5 release sharpens prompt adherence, fixes longstanding hand-and-text artifacts the prior version stumbled on, and adds a slightly larger architecture in the standard variant. On the public leaderboard it overtook Nano Banana 2 at the time of release and now sits ranked just behind two closed-weight frontier models that don't release their weights.
The practical headline for builders is that HiDream-O1 1.5 ships with open weights and a permissive license, which means anyone with a 12GB-class GPU can run it locally. That property is why this matters more than a leaderboard delta. Quality differences of a few percentage points between leaderboard slots rarely matter for hobbyist creative work; controlling the model file and the prompt does.
What are the real VRAM requirements?
Diffusion-transformer image models in this generation typically advertise 12-16 GB peak at fp16, but the real footprint is the sum of model weights + KV cache + intermediate activations + the VAE decoder. The published model card and community benchmarks line up roughly like this:
| Precision | Weights | Peak VRAM (1024px) | Speed (RTX 3060) |
|---|---|---|---|
| FP16 / BF16 | ~14 GB | 17-19 GB | needs CPU offload |
| FP8 (E4M3) | ~7.5 GB | 10-12 GB | 20-30 s/image |
| Int8 (per-tensor) | ~7 GB | 9-11 GB | 25-35 s/image |
| Int4 (GPTQ-style) | ~3.8 GB | 6-7 GB | 35-50 s/image, mild quality loss |
These numbers assume a 28-30 step Euler-A schedule at 1024×1024 with classifier-free guidance. Step count is the biggest knob on wall-clock time; precision is the biggest knob on VRAM. The 12GB card sits in the comfortable middle for fp8 / int8 quantization and works at int4 with no headroom drama.
Will it fit on an RTX 3060 12GB?
Yes, comfortably at fp8 or int8 and with room for a multi-step KV cache and one or two LoRA adapters. The RTX 3060 12GB has 360 GB/s of memory bandwidth and 28 TFLOPS of FP16 throughput, which is fine for diffusion's tensor-heavy workload because each step processes a fixed amount of data and the GPU can hide memory latency behind compute.
| Configuration | Seconds/image (1024px) | Notes |
|---|---|---|
| FP8, 30 steps | 22-28 | Sweet spot for quality |
| FP8, 50 steps | 36-46 | Diminishing returns past 35 |
| Int8, 30 steps | 26-34 | Marginally smaller VRAM |
| Int4, 30 steps | 38-50 | Acceptable for batch generation |
| FP16, 30 steps (CPU offload) | 70-110 | Avoid; offload is painful |
| FP16 + 512px | 12-18 | Falls back to fast preview |
The drop from a hosted API (4-8 s/image on H100-class hardware) to local (20-45 s) feels slow if you're used to the cloud, but it's a one-time mental adjustment. Once you queue 20 images and walk away for ten minutes, the cloud-vs-local comparison flips: you don't pay per image, you don't share GPU time with a queue, and your prompts don't leave the machine.
Setting it up in ComfyUI without offload thrashing
ComfyUI is the natural host because community nodes land within days of any new open-weight image model release. The default loader will try fp16; you have to override that or you'll bounce off the 12GB ceiling and silently fall back to CPU offload, which is the slow mode.
The minimum setup that works on a 3060:
- Install ComfyUI from source. Pull the HiDream-O1 nodes from the community repo once they're tagged stable.
- Download the fp8 weights (typically ~8 GB) rather than fp16 (~16 GB). The model card publishes both.
- In the Load Diffusion Model node, set the precision to
fp8_e4m3fnand the device tocuda:0. - Add a VAE Tiling node downstream of the sampler so VAE decode at 1024×1024 doesn't spike VRAM at the end of generation.
- Keep the CLIP / T5 text encoder on the GPU if it fits (~2 GB for the small variant) — offloading it to CPU adds 200-400 ms per prompt change.
The ComfyUI workflow JSON for this setup is short enough to keep in a gist; save it and reuse it across model versions. The most common newbie mistake is leaving VAE Tiling off, which works at 512px and OOMs at 1024px.
Generation-time vs quality tradeoffs at each precision
The quality differences between fp16, fp8, and int8 are small and structured rather than random. Fp8 occasionally introduces a faint banding in flat color regions; int8 is indistinguishable for most prompts but can drift slightly on rare-token concepts (obscure artist names, niche styles). Int4 is where you start seeing real artifacts — hand structure suffers more than at fp8, and the texture detail in landscapes can look mildly painterly.
Concrete recommendation for a 12GB card: run fp8 at 30 steps as your default. Step up to fp16 with offload if you're producing a hero image and don't mind the wait. Drop to int4 only when you're queuing a hundred images overnight and want them done before morning.
Perf-per-dollar vs paying for a hosted image API
Hosted image APIs for frontier-tier models charge roughly $0.02-$0.08 per 1024×1024 image. A creative who generates 30 images a day spends $20-70/month on the API. A local RTX 3060 build that costs $700 fully assembled pays back against that subscription in 10-35 months, depending on volume.
The math gets aggressive in the local direction with two patterns. Batch generation — overnight queues of hundreds of images — is free on the local card once the hardware is paid for; on the API it scales linearly with image count. Iteration on prompts is the other one: a typical creative session burns dozens of throwaway generations to dial in a concept, and the per-image API fee on those throwaways adds up faster than the user expects.
Local loses on time-to-first-image (the cold-start penalty of loading the model into VRAM is 5-15 seconds), on access to the absolute latest closed-weight models (you can't run what doesn't have open weights), and on hardware reliability (if your GPU fails, your generation stops). For most hobby and small-studio workflows, those losses are a fair trade for unlimited iteration and prompt privacy.
Bottom line — where 12GB is enough and where you want more
A 12GB RTX 3060 is enough for HiDream-O1 1.5 at fp8 or int8, comfortably handles 1024×1024 generation at 20-45 seconds per image, and gives you a real on-ramp to running frontier-class open-weight image models locally. That's a great place to start. You should plan to upgrade to a 16GB-or-larger card if any of three things become true: you need consistent fp16 quality for production work, you want to drive a multi-monitor setup with display GPU + compute GPU separation, or you start training LoRAs on top of the base model (training spikes VRAM far beyond inference). For inference-only on a single image at a time, the 12GB tier is the right answer for 2026.
Citations and sources
- Artificial Analysis — text-to-image leaderboard ranking HiDream-O1 1.5
- ComfyUI on GitHub — node graph host for diffusion models
- TechPowerUp — RTX 3060 spec sheet (memory bandwidth, FP16 throughput)
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.