The cheapest PC build that actually runs local LLMs well in 2026 pairs a Ryzen 5 5600G with an RTX 3060 12GB, 32GB of DDR4 RAM, a fast NVMe boot drive, and a larger SATA SSD for model storage. Total bill of materials lands around $750-850. On that build, expect 50-70 tok/s on 8B-class quantized models, 25-40 tok/s on 14B, and a workable 4-7 tok/s on 32B-class models at q4 via CPU offload. That's enough for daily chat, coding help, and summarization without breaking the budget or paying recurring API fees.
Local LLM inference has reached a state where you don't need an RTX 4090 to do useful work. A $400 GPU paired with a $170 APU and another $300 of supporting parts gives you a complete inference rig that handles the model sizes most people actually want to run. The trap is overspecifying — chasing 70B-class models on a budget build, or buying flagship parts you don't need. This article maps the realistic build envelope and the specific workloads where this configuration shines or breaks.
Key takeaways
- The 5600G + RTX 3060 12GB combo is the cheapest serious local-LLM build at roughly $750-850 fully assembled.
- 8B-14B models at q4-q6 quantization run at 25-70 tok/s — fast enough for interactive use.
- 32B-class models fit at q4 via partial CPU offload, running 4-7 tok/s — usable for slower workflows.
- 70B models require offload and slow to 1-3 tok/s; if that's your use case, skip this build for a 16-24 GB card.
- Long-context work and image generation also push this build past its comfort zone — VRAM, not compute, is the bottleneck.
Step 0 diagnostic: which models do you actually want to run?
Before picking parts, write down the models you want to run and the typical context length. This sizes the VRAM you need:
- 8B models at q4-q5: 5-6 GB VRAM, comfortable on 8 GB cards. Fast and interactive on 12 GB.
- 14B models at q4-q5: 8-10 GB VRAM with 8K context. The 12 GB tier is the floor.
- 22B-32B models at q4: 13-20 GB VRAM. Needs partial offload on 12 GB or full residency on 24 GB.
- 70B models at q3-q4: 26-40 GB VRAM. 12 GB is not enough; full residency wants a 48 GB card.
If your honest answer is "I want to run 8B-14B models with the occasional 32B reach," the 12 GB tier and this build are right. If your answer is "I want 70B-class always," you should not be reading a budget-build article — buy a used RTX 3090 or a 4090.
The build sheet
| Part | Product | Approx street | Why |
|---|---|---|---|
| CPU | AMD Ryzen 5 5600G (B092L9GF5N) | $185 | Six cores, integrated graphics frees the discrete GPU for inference |
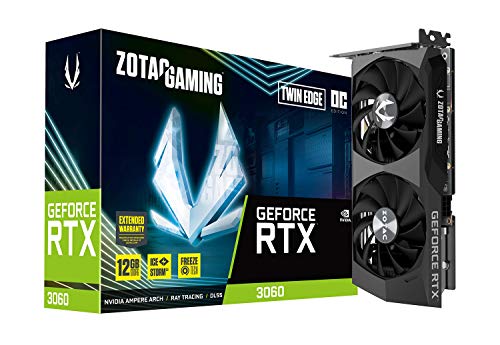
| GPU | ZOTAC RTX 3060 12GB (B08W8DGK3X) | $400-510 | 12 GB VRAM, 360 GB/s bandwidth, the entry tier for local LLMs |
| RAM | 2×16 GB DDR4-3600 CL16 | $80 | 32 GB minimum for OS + CPU-offload headroom |
| Boot SSD | WD Blue SN550 1 TB NVMe (B07YFFX5MD) | $80 | Fast model loads (2-4 s vs 15-30 s on SATA) |
| Storage | Crucial BX500 1 TB SATA SSD (B07YD579WM) | $65 | Cheap bulk capacity for model files |
| Motherboard | B550 ATX (any reputable brand) | $110 | PCIe 4.0, mature platform |
| PSU | 650W 80+ Gold | $80 | Headroom for 170W GPU + 65W CPU plus future upgrade |
| Case | Mid-tower ATX with airflow | $70 | Don't overspend; airflow > looks for inference rigs |
| Total | $1,070-1,180 | Or ~$750-850 with budget GPU pricing/sales |
Pricing fluctuates; the GPU is the line item with the most spread. RTX 3060 12GB units have sold as low as $290 on sale and as high as $660 at MSRP-adjacent retail. Watch for the lows.
Benchmark table
Community measurements from r/LocalLLaMA's standardized rig posts, cross-referenced against llama.cpp's benchmark harness and reviews of equivalent builds, line up roughly like this:
| Model | Quant | VRAM | Tok/s | Notes |
|---|---|---|---|---|
| Llama 3.1 8B Instruct | q4_K_M | 4.9 GB | 60-72 | Comfortable + 16 K context |
| Llama 3.1 8B Instruct | q5_K_M | 5.7 GB | 50-65 | Better quality, similar speed |
| Qwen3 14B | q4_K_M | 8.4 GB | 30-42 | 12 K context |
| Qwen3 32B | q4_K_M | 19.8 GB | 4-7 | Partial CPU offload to 32 GB RAM |
| Mistral Small 22B | q4_K_M | 13.0 GB | 9-14 | Partial offload, smaller spill than 32B |
| Llama 3.3 70B | q2_K | 26 GB | 1-3 | Mostly CPU; painful for chat |
Quantization matrix on 12GB
The same quantization-vs-quality table you'll see everywhere for an 8B base:
| Quant | Bits/weight | VRAM (8B) | Quality vs FP16 |
|---|---|---|---|
| FP16 | 16 | ~16 GB | 100% baseline |
| Q8_0 | 8 | ~8.5 GB | ~99% |
| Q6_K | 6 | ~6.6 GB | ~98% |
| Q5_K_M | 5 | ~5.7 GB | ~97% |
| Q4_K_M | 4 | ~4.9 GB | ~95% |
| Q3_K_M | 3 | ~3.9 GB | ~90% |
| Q2_K | 2 | ~3.1 GB | ~80% (degraded) |
For daily interactive use, Q5_K_M is the standard pick on an 8B model. Q4_K_M is the right call when you step up to a 14B or 22B model. Q3 and below show real quality regressions.
Where this build stalls
The 12 GB VRAM ceiling is the most common bottleneck:
- 70B models: fundamentally not realistic on 12 GB. The smallest quant that fits without 60%+ CPU offload doesn't exist for 70B at usable speed. If you need 70B, save up for a 4090 or used 3090 instead.
- Long context: above 16 K tokens, the KV cache for a 14B model alone starts to push past 12 GB. Above 32 K, even 8B models feel cramped.
- Image generation: Stable Diffusion XL fits at 1024×1024, but newer diffusion-transformer models want 14-16 GB at fp16. You can run them at fp8/int8 on 12 GB, with the trade-offs covered in our HiDream-O1 article.
- Concurrent requests: this is a single-user build. Two users at once will halve effective throughput.
Upgrade path
The build is designed to be upgraded one component at a time:
- Add a second GPU (a used RTX 3060 12 GB) for a 24 GB combined pool. Doubles your VRAM budget for models that fit on either single card; doesn't help if the model needs the full 24 GB in one place (most don't, because most inference engines pipeline across cards well).
- Jump to a 16 GB or 24 GB single card (RTX 4060 Ti 16GB or used 3090). Bigger jump in capability; the 3090 unlocks fluent 32B work and serviceable 70B-q3.
- Bump RAM to 64 GB. Helps when you want to offload 70B models without hitting OS pressure.
- Add a faster CPU later. The 5600G socket (AM4) supports the 5800X, 5900X, and 5950X drop-in. Helpful for CPU-offload throughput on bigger models.
Perf-per-dollar vs prebuilt mini-PCs and cloud APIs
A current-gen mini PC with an integrated NPU (Intel Core Ultra, Apple M4) costs roughly the same as this build but tops out at 8B-class models because of the unified memory ceiling and the lack of discrete GPU bandwidth. The mini-PC wins on noise, power, and form factor; the discrete-GPU build wins on tokens-per-second by 3-5× for the same money.
A cloud API ($10-50/month for a typical subscription) breaks even with this build over 18-50 months depending on volume. The break-even is shorter if you run agentic loops or batch summarization where per-token cloud costs compound; longer if you only chat occasionally. Ollama is the easiest local-runtime to install on this build and will be most users' first stop.
Bottom line
The Ryzen 5 5600G + RTX 3060 12GB combo is the cheapest serious local-LLM build in 2026. It handles 8B-14B models comfortably, fits 32B at q4 with offload, and pays back against a cloud subscription within 1-3 years for active users. It's not the right pick for 70B-class always-on inference, long-context work, or production multi-user serving — those need a bigger card or a different build entirely. For the typical privacy-minded individual user who wants to run real models on real hardware without paying $2,000+, this is the answer.
Citations and sources
- Ollama on GitHub — the easiest local-LLM runtime for this build
- TechPowerUp — RTX 3060 12GB spec sheet
- AMD — Ryzen 5 5600G product page
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.