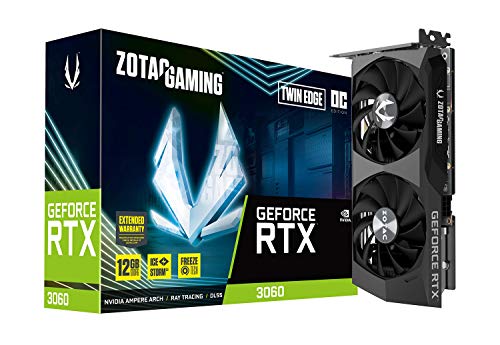
Short answer: Under $400 in 2026, the RTX 3060 12 GB is the best new card for local LLM work, and a used RTX 3060 12 GB at $200–230 is the price-to-performance winner overall. The ZOTAC RTX 3060 Twin Edge and the MSI RTX 3060 Ventus 2X are the two safest new-card buys; both ship with a true 12 GB VRAM buffer that comfortably hosts 7B–13B class open-weights models at q4–q5 quantization.
Best GPU for Local LLMs Under $400 in 2026
VRAM capacity, not raw compute, sets the floor — and 12 GB is the sweet spot under $400.
Best GPU for local LLMs under $400 in 2026: new vs used 12 GB picks, AMD's software-stack gap, and the right pairing for each.

Which GPU for which model, at Q4
Start from the model you want to run. At Q4_K_M the weights take roughly 0.55 GB per billion parameters and the runtime plus a usable context window wants about 2 GB on top, which is where the VRAM column comes from. The card in each row is the cheapest one SpecPicks holds measurements for that clears that figure; the column after its price is the fastest card with at least 3 pooled runs in the same band at up to $2,500, for when the budget stretches. A card with fewer runs in the band is not ranked here, even where its benchmark page quotes a faster median. Every tokens-per-second number is a median over community-reported Q4 runs, with the run count and the source beside it.
| Model you want to run | VRAM you need | Cheapest card that clears it | Measured | Price | Fastest card with 3+ runs | Source |
|---|---|---|---|---|---|---|
| 3B (Llama 3.2 3B, Qwen 3 4B)~2 GB of weights at Q4 | 6 GBweights plus a usable context window | NVIDIA GeForce GTX 16606 GB | 38.4 tok/s3 runs · 2 sources | $200streetView current price | GeForce RTX 50608 GB · 93 tok/s over 6 runs · source$500 streetView current price | DatabaseMart |
| 7-9B (Llama 3.1 8B, Qwen 3 8B)~5 GB of weights at Q4 | 8 GBweights plus a usable context window | Intel Arc B57010 GB | 49.6 tok/s5 runs · 3 sources | $219MSRP | NVIDIA GeForce RTX 509032 GB · 224.8 tok/s over 4 runs · source$1,999 MSRP | llama.cpp GitHub (SYCL perf… |
| 12-14B (Qwen 3 14B, Phi-4)~8 GB of weights at Q4 | 12 GBweights plus a usable context window | Arc B58012 GB | 35 tok/s4 runs · 4 sources | $249MSRP | NVIDIA GeForce RTX 509032 GB · 89.9 tok/s over 3 runs · source$1,999 MSRP | llama.cpp GitHub Discussions |
| 30-35B (Qwen 3 32B, QwQ 32B)~19 GB of weights at Q4 | 24 GBweights plus a usable context window | NVIDIA GeForce RTX 309024 GB | 29.2 tok/s4 runs · 3 sources | $2,300streetView current price | NVIDIA GeForce RTX 509032 GB · 55.6 tok/s over 8 runs · source$1,999 MSRP | Hardware Corner |
| 70B+ (Llama 3.3 70B, Qwen 2.5 72B)~40 GB of weights at Q4 | 48 GBweights plus a usable context window | AMD Radeon Pro W7900 48GB48 GB | 11.3 tok/s8 runs · 3 sources | $3,999MSRP | No card under $2,500 with 3+ runs measured 10%+ faster | Windows Forum (citing AMD) |
Full per-model GPU reference: VRAM by quant and by card tier → Best AI rigs: the same table with the fastest card in each band → Full local-LLM GPU buying guide How we source these numbers
Prices change often; the price at checkout is the one that counts. As an Amazon Associate, SpecPicks earns from qualifying purchases.
Hardware at a Glance
Median generation throughput at 7–9B models (Llama 3.1 8B, Qwen 3 8B), Q4 quantization, from community-reported runs SpecPicks tracks. Each row pools runs from different sources, runtimes and models in that class, so the rows are not a matched head-to-head; where the article compares cards on the same rig, its own figures are the like-for-like result. Street price is the second-lowest listing priced within the last 24 hours at 0.5–2× launch MSRP, so no single listing sets it, and a street figure well above MSRP says so in its cell; where too few listings pass that check the cell shows a dash and the launch MSRP, which is not comparable with the street figures. Rows marked for comparison are not the cards this article is about — they are included so the throughput column has something to be read against.
| GPU | VRAM | Llama-3-8B class, Q4 | Street price | Sources |
|---|---|---|---|---|
| NVIDIA GeForce RTX 3060 12 GB | 12 GB | 55 tok/s23 runs · 9 sources | —too few current listings for a street figure · launch MSRP was $329 | SpecPicks median of 23 runs; sources: TYO Lab blog, Hardware Corner, llama.cpp GitHub (CUDA performanc…, Ajit Singh / Hardware-Corner +5 more |
| GeForce RTX 4070 SUPERfor comparison | 12 GB | 57.8 tok/s12 runs · 6 sources | $1,099street, all listings · 1.8× the $599 launch MSRP | SpecPicks median of 12 runs; sources: Hardware Corner, llmrun.dev, LocalScore (Mozilla Builders), llama.cpp GitHub Discussions +2 more |
| Arc B580for comparison | 12 GB | 41 tok/s11 runs · 9 sources | —too few current listings for a street figure · launch MSRP was $249 | SpecPicks median of 11 runs; sources: Compute Market, llama.cpp GitHub Discussions, dev.to, InsiderLLM +5 more |
Why VRAM, not compute, sets the floor
Local LLM workloads in 2026 are overwhelmingly bottlenecked by VRAM capacity, not by raw compute. The reason is that a transformer's per-token generation throughput is memory-bandwidth-bound: each token requires re-reading the model's weights from VRAM. Inference compute fits in a small fraction of the GPU's available FLOPS at every consumer-class card. What you actually need is enough VRAM to hold the model weights plus the KV cache plus runtime overhead. Per the llama.cpp reference repository, the GGUF quantization formats target consumer-VRAM footprints by design — q4_K_M is the sweet spot for a 7B-class model on a 12 GB card.
This has direct implications for shopping. A $300 GPU with 8 GB of VRAM and a $400 GPU with 12 GB of VRAM will run the same 7B-class model at roughly similar throughput — but the 12 GB card can also host a 13B-class model at the same quant level. For local LLM work, capacity dominates.
What "$400 budget" gets you in 2026
Three categories cluster in the under-$400 band:
- New 12 GB cards — chiefly the RTX 3060 12GB and the MSI RTX 3060 Ventus 2X, available new for $260–290.
- New 8 GB cards — including newer-generation entry SKUs that price in the $300–380 band. Faster on the small models, but capped at the 7B class because of VRAM.
- Used 12 GB and 16 GB cards — the used RTX 3060 12 GB at $200–230 is the price-to-performance leader; used 16 GB workstation cards (RTX A4000) cluster around $400 on eBay.
The question for a buyer is whether the extra capacity of a 12 GB card outweighs the extra speed of a newer 8 GB card. For LLM work the answer is consistently yes — VRAM caps you out of model sizes you cannot run any other way.
Side-by-side: cards under $400
| Card | New price (2026) | VRAM | Mem bandwidth | TGP | Best for |
|---|---|---|---|---|---|
| RTX 3060 12 GB (new) | ~$260 | 12 GB | 360 GB/s | 170 W | best value 7B–13B at q4 |
| RTX 3060 12 GB (used) | ~$200 | 12 GB | 360 GB/s | 170 W | overall winner |
| RTX 4060 Ti 8 GB | ~$370 | 8 GB | 288 GB/s | 160 W | fast 7B; can't host 13B at q4 |
| RX 7600 XT 16 GB | ~$320 | 16 GB | 288 GB/s | 190 W | 13B class fits; weaker LLM software stack on ROCm |
| RTX A4000 16 GB (used) | ~$400 | 16 GB | 448 GB/s | 140 W | 13B at q5; workstation form factor |
The 16 GB AMD card looks superficially compelling but in 2026 the open-source LLM software stack still ships better-tuned CUDA paths than ROCm paths. Llama.cpp's CUDA backend leads its ROCm backend by 15–30% on equivalent silicon for most models; vLLM's AMD support is functional but lags. If you are comfortable with the software gap, the 7600 XT is a fine choice; if you want the path of least resistance, the 3060 is.
Why the RTX 3060 12 GB still wins on value
Per the TechPowerUp RTX 3060 specifications, the card delivers 12 GB of GDDR6 at 360 GB/s. That bandwidth is the floor for hosting a 7B-class model at usable interactive speed (25–35 tok/s at q4_K_M) and the ceiling for a 13B-class model at q4 (15–20 tok/s). Both of those points are above the "useful as a local assistant" threshold. Higher-bandwidth cards in this price band do not exist; cards with more VRAM in this band are either used workstation parts (RTX A4000) or AMD silicon with the software-stack caveat.
Used market is the best deal
A used RTX 3060 12 GB regularly sells around $200–230 in 2026. That price point is the best overall value for local LLM work — you get the full 12 GB buffer, full CUDA tooling, and a card that has thousands of dollars of new-stack capability for a couple hundred dollars. The risks of buying used (mining cards, prior heavy use) are real but mitigated by checking for honest sellers and stress-testing on receipt. Mining cards typically had quiet, cool lives at sustained moderate load — counterintuitively often a good buy, not a bad one.
Pair the card with a competent platform
A modern 12 GB card is wasted on an older platform that bottlenecks PCIe transfer or CPU offload. For an under-$400 GPU purchase, pair with:
- A modern desktop CPU like the AMD Ryzen 7 5800X (AM4, 8 cores, DDR4)
- 32 GB of system RAM — model offload eats RAM as a fallback when VRAM is exhausted
- A fast NVMe SSD like the WD Blue SN550 for quick model loads
- A quality 550–650 W PSU; the 3060's 170 W TGP keeps PSU requirements modest
The total platform under these assumptions runs around $700–900 for a complete new build, half of which is the GPU and CPU. That is the cheapest credible local-LLM box in 2026.
Common pitfalls
- Buying an 8 GB card and being capped at 7B-class models forever.
- Treating GPU compute as the bottleneck; it is not — memory bandwidth and capacity are.
- Buying an AMD card without understanding the software-stack gap.
- Pairing a strong GPU with an old CPU that bottlenecks PCIe or offload throughput.
- Skipping a fast NVMe; model loads on a slow disk are tens of seconds vs single-digit seconds.
When NOT to buy a $400 GPU for LLM work
If your workload requires a 70B-class model, no card in this budget can run it without aggressive offload that ruins throughput. Either save for a 24 GB card or use a hosted API. If your workload is unpredictable bursts (quiet most weeks, heavy a few days a month), API billing dominates the math and a local card is wasted capital. If you have a budget for $700+, the next tier opens up — but at $400 the 3060 is the clear pick.
Bottom line
The RTX 3060 12 GB and the MSI RTX 3060 Ventus 2X are the safest new-card buys under $400 for local LLM work in 2026. A used 3060 12 GB at $200–230 is the price-to-performance leader if you are willing to buy used. Pair the card with a modern 6+ core CPU like the Ryzen 7 5800X and a fast WD Blue SN550 NVMe for a complete sub-$900 local-LLM rig that handles 7B–13B class models comfortably.
Used-card market context
The used GPU market in 2026 is healthier than at any point since 2020. Mining demand collapsed in 2022, then stabilized at a much lower baseline; consumer demand is normal; and the cards that were heavily mined (RTX 30-series) have aged into the secondhand market in volume. The used RTX 3060 12 GB at $200–230 is the standout example — abundant supply, a card that did not push the silicon hard even under mining loads (mid-range cards mined at modest power), and full CUDA software compatibility for years to come.
The risks of buying a used card are real but manageable:
- Cosmetic wear is usually purely aesthetic. Dings on the shroud, scuffs on the I/O bracket — these do not affect function.
- Worn thermal paste is fixable. A repaste-and-reseat takes 30 minutes and a $5 tube of paste; thermals improve by 5–10°C on a card that has been running for years.
- Failing fans are replaceable as a worst case. Most cards in this band use standard 92mm or 100mm fan sizes; replacements are $10–15.
- Memory errors are the deal-breaker. Run OCCT's VRAM tester or MemTest86's GPU-RAM mode for 30 minutes on receipt; if any errors show, return the card.
- Coil whine is permanent and audible. If you can hear it during the seller's test, you will hear it for the card's life. Decide whether you can live with it.
A return window — even just 7 days — is what separates a good used buy from a roll of the dice. eBay's Money Back Guarantee covers this on most listings; Marketplace transactions usually do not.
Extended platform comparison for under-$900 builds
A full local-LLM rig in 2026 under $900 — GPU plus everything else — settles on these picks pretty consistently:
| Component | Pick | Price | Why |
|---|---|---|---|
| GPU | RTX 3060 12 GB | ~$260 | 12 GB VRAM is the LLM cap |
| CPU | Ryzen 7 5800X | ~$170 | 8 cores, mature AM4 |
| Motherboard | B550 mid-range | ~$120 | dual M.2, PCIe 4.0 |
| RAM | 32 GB DDR4-3600 CL16 | ~$70 | model offload fallback |
| Storage | WD Blue SN550 1 TB | ~$55 | fast model loads |
| PSU | 650 W gold | ~$70 | headroom for upgrade |
| Cooler | tower air, e.g. NH-U12S-class | ~$60 | 5800X needs it |
| Case + fans | mid-tower with mesh front | ~$80 | airflow matters under LLM load |
Total: ~$885. That is a complete new build that runs 7B–13B class models at q4_K_M with full GPU offload, hosts ComfyUI for image generation, and pairs with two 1080p monitors comfortably.
Swap the GPU for a used 3060 12 GB at $200 and the total drops to ~$825. Substitute the Ryzen 7 5700X for the 5800X and you save another $30 with negligible LLM-workload impact.
Multi-GPU dual-card builds in this budget
Some users notice that two used 3060 12 GB cards for $400 give you 24 GB total VRAM and ask: can you treat that as a 24 GB pool for LLM work? The short answer is yes for some inference backends (vLLM, exllamav2 with tensor parallelism), no for others (most llama.cpp configurations). The longer answer is that two 12 GB cards as a 24 GB pool give you the model size of a single 24 GB card but typically at lower throughput than a single 24 GB card because of PCIe inter-card bandwidth.
For a buyer choosing between two used 3060s and one used RTX 3090 24 GB, the 3090 is usually the better pick if you can find one in budget. The dual-3060 route is the right choice only when you cannot find a single-card 24 GB option at the price.
Common mistakes that waste this budget
- Buying a $400 GPU and pairing it with a $40 PSU. The PSU is the most likely failure point in any build; do not skimp.
- Buying a $400 GPU and pairing it with 16 GB of RAM. Model offload spills to system RAM; 16 GB is uncomfortably tight.
- Buying a high-end CPU like the 9800X3D specifically for LLM work. CPU rarely matters for inference once you have a competent 6+ core chip.
- Treating PCIe Gen 5 NVMe as a meaningful upgrade for LLM work. Model load times are noticeable but not the bottleneck of the loop.
Related guides
- GLM-5.2 Review: Can the Top Open-Weights LLM Run Locally?
- Benchmarking Open Models for Agentic Tool Use on an RTX 3060
- ComfyUI on an RTX 3060 12GB: Real Image-Gen Throughput in 2026
- RTX 3060 12GB in 2026: Is It Still a 1080p Value Champion?
Citations and sources
- TechPowerUp — GeForce RTX 3060 specifications
- llama.cpp — reference open-source inference runtime with consumer-VRAM-targeted quantization
- Hugging Face — research blog on consumer-VRAM open-weights model sizes
This piece is editorial synthesis based on publicly available information. No independent first-party benchmarking is reported.
Products mentioned in this article
Amazon & eBay listings, plus full specs and alternatives on each product page.


As an Amazon Associate, SpecPicks earns from qualifying purchases; we also earn on qualifying eBay purchases via the eBay Partner Network. Prices shown were last tracked at crawl time and may vary — check the listing for the current price.
Watch a review
Friendly Fire: AMD Ryzen 7 5800X CPU Review & Benchmarks vs. 5600X & 5900X — Gamers Nexus on YouTube
Frequently asked questions
Why is the RTX 3060 12GB recommended for local LLMs?
Its 12GB of VRAM is unusually generous for its price tier, and VRAM is the binding constraint for local inference. Per public benchmarks, the 3060 runs 7B-13B models at usable speeds and fits larger models at lower quants. Faster cards with less memory often cannot load the same models, making the 3060's capacity the deciding value factor.
Can I run 70B models on a sub-$400 GPU?
Not comfortably on a single budget card. A 12GB GPU forces heavy quantization and CPU offload for 70B-class models, which collapses throughput. Per memory math, 70B inference wants far more VRAM or multiple cards. Under $400, target 7B-13B models you can fully fit, where the experience is fast and the quality loss minimal.
Does my CPU matter for budget local inference?
When the model fits in VRAM, the GPU dominates and CPU impact is small. Under partial offload, the host CPU and memory bandwidth become bottlenecks, so a capable chip like the Ryzen 7 5800X helps. For a smooth budget AI box, pair the GPU with a competent CPU so prompt processing and offload paths do not stall.
What power supply do I need for an RTX 3060 build?
The RTX 3060 is modest on power compared to flagships, so a quality mid-wattage PSU is sufficient. Per the card's specs, size your supply with headroom above the combined GPU and CPU draw, and use a reputable unit. Budget AI builds rarely need the huge supplies that 4090-class cards demand, which keeps total cost down.
When should I spend more than $400?
Step up when your target models consistently exceed 12GB, when you need higher throughput for production workloads, or when you run image-gen at high resolution. Per cited figures, a larger card pays off for sustained heavy use, but for learning, 7B-13B chat, and light agents, the sub-$400 RTX 3060 is the smarter starting investment.
Related reading
- Is the RTX 3060 12GB Still the Best Sub-$400 AI Card in 2026?
- Ryzen 5 5600G vs Ryzen 7 5800X for a 24/7 Ollama Box
- Intel Arc Pro B60 vs RTX 3060 12GB for Local LLMs
- Best GPU for Ollama Under $300: Why 12GB Beats a Faster 8GB Card
- ZOTAC RTX 3060 Twin Edge vs MSI RTX 3060 Ventus 3X: Which 12GB Card?
- RTX 3060 12GB Local LLM Guide: Which Models Actually Fit (2026)
- Mac Mini M4 vs RTX 3060 12GB for Local LLMs: Which Actually Wins?
- Best GPU for a NAS or Homelab Running Local LLMs (2026)
